
Pinned Tweet
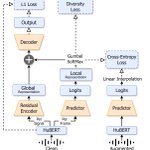
🚨I’m excited to share our #INTERSPEECH2024 paper "NAST: Noise Aware Speech Tokenization for Speech Language Models” 🥳 W/ @adiyossLC
Paper-arxiv.org/abs/2406.11037
Code-github.com/ShovalMessica/NAS…

Shoval Messica retweeted
Do VLMs reason spatially or verbally? Kelly Cui @nikhil07prakash @ShovalMessica trace binding within VLMs.
Is "X to the left of Y" about geometry or words?Interestingly, they see *dual* spatial+verbal mechanisms.
Remove one, and the other kicks in.
They think *both* ways. ➡️

Shoval Messica retweeted

VLMs use pointer-like signals for spatial variable binding. But where does the binding actually happen?
We find a dual mechanism: the vision encoder is the primary source of binding, with the LM backbone playing a secondary role.

Shoval Messica retweeted

Have LLMs become supervised learners (once again)?!
In our new paper, we argue that current LLMs’ post-training methods have effectively reverted to the "pre-train then fine-tune" era, explicitly tailoring models to desired behaviors.
1/n
🤖 Made with AI

Shoval Messica retweeted

MFA is a beautiful visualization, but not only that.
It’s a practical tool:
competitive localization and better steering, while revealing that concepts live in regions, not just single directions.
Grateful I got to contribute to this with an awesome team!

Shoval Messica retweeted
8/
📄 Read the full paper:
arxiv.org/abs/2505.21218
Thanks for reading!
#AI #LLM #Uncertainty #Interpretability #Research

Shoval Messica retweeted
🤔Can an LLM "unconscious" feel a lie bubbling up before it speaks?
🤔And what mysteries hide in its linear space of uncertainty?
Thrilled to share our new paper:
“Pre-trained LLMs Learn Multiple Types of Uncertainty” (@roicohen9•@OmriFahn•@GerardDeMelo)
arxiv.org/abs/2505.21218
Shoval Messica retweeted

🚨New paper on SLM evaluation🚨
We present SALMon🍣 which is a suite of benchmarks for evaluating how much Speech Language Models model acoustic elements like sentiment or background noise.
Project: pages.cs.huji.ac.il/adiyoss-… 🧵👇🏻

Shoval Messica retweeted
Which is better, running a 70B model once, or a 7B model 10 times? The answer might be surprising!
Presenting our new @COLM_conf paper: "The Larger the Better? Improved LLM Code-Generation via Budget Reallocation"
arxiv.org/abs/2404.00725
1/n

Shoval Messica retweeted

I am excited to share my first work: "Dataset Size Recovery from LoRA Weights".
Ever wondered if you could find out how many samples was a model trained on using just its weights? Well now you can!
Project: vision.huji.ac.il/dsire/
👇
Shoval Messica retweeted

Speech tokenizers are fundamental in building speech LMs. In a recent study we show the common tokenization method (a.k.a “semantic tokens”) is not robust to different signal variations. We then present NAST! a noise aware speech tokenizer
w. @ShovalMessica
Code and models 👇

🚨I’m excited to share our #INTERSPEECH2024 paper "NAST: Noise Aware Speech Tokenization for Speech Language Models” 🥳 W/ @adiyossLC
Paper-arxiv.org/abs/2406.11037
Code-github.com/ShovalMessica/NAS…
Shoval Messica retweeted

1/ Commonsense reasoning needs multimodal knowledge, yet current LLMs focus mostly on text, limiting their integration of crucial visual information.
We introduce vLMIG, a method that enhances LLMs' visual commonsense by integrating images into the decision-making process

Shoval Messica retweeted

NAST: Noise Aware Speech Tokenization for Speech Language Models. arxiv.org/abs/2406.11037
Shoval Messica retweeted

``Joint Audio and Symbolic Conditioning for Temporally Controlled Text-to-Music Generation,'' Or Tal, Alon Ziv, Itai Gat, Felix Kreuk, Yossi Adi, ift.tt/tP4Hua8
Shoval Messica retweeted

Today we released JASCO 🥁🎵🪇!
JASCO uses time-aligned conditions (e.g. drums, melody) as guiding controls for text-to-music generation.
📜Full Paper: arxiv.org/abs/2406.10970
🔊Samples: pages.cs.huji.ac.il/adiyoss-…
@lonziks @itai_gat @FelixKreuk @adiyossLC
Stay tuned for updates.
Shoval Messica retweeted
``NAST: Noise Aware Speech Tokenization for Speech Language Models,'' Shoval Messica, Yossi Adi, ift.tt/TwrHMcg