

Founder, https://xitter.cf/t.co/IacmLzHyJR. Ex-VP, Roblox. Comic will be live soon @ https://xitter.cf/t.co/mgHd5HxrBG
Sunnyvale, CA
Joined September 2011
- Tweets1.2K
- Following111
- Followers3.6K
- Likes166




Pinned Tweet
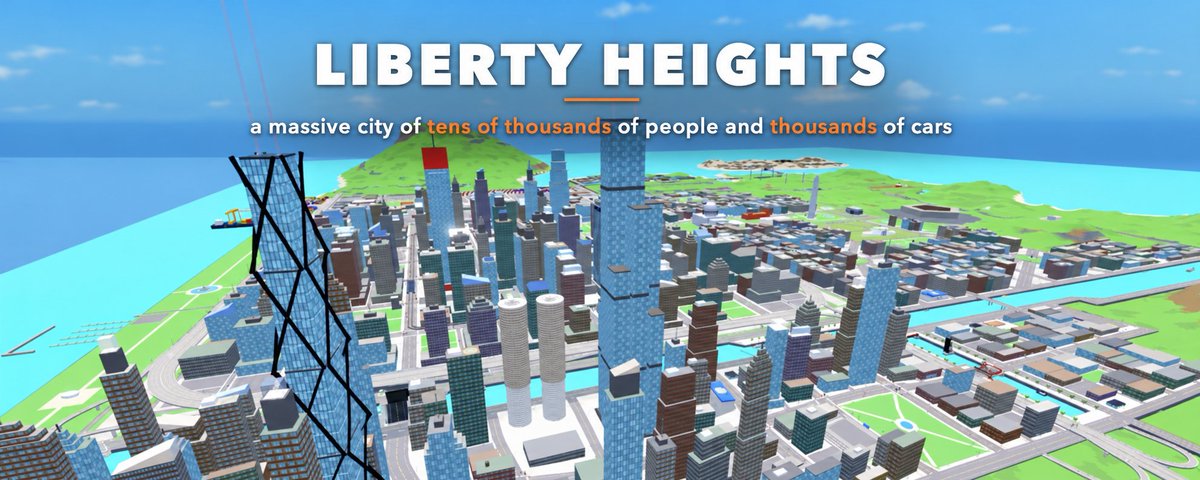
As promised here's a writeup of how I do agentic playtesting and how it helps. The writeup includes my testing setup along with videos of my sprawling city simulation that has 10s of 1000s of NPCS. Check it out!
A few things in this benchmark makes me want to ignore pretty much the rest of it?
Gpt Terra 6.1 > Fable 5.1 max, really? in what exactly?
Gpt Sol 6.1 being so close to Astra/Opus 5.5 and beating Argon?
Ain't no way.

Announcing Artificial Analysis Intelligence Index v5, featuring 2 new benchmarks and 3 upgrades. For the first time, the majority of the Index is built on private datasets
The Artificial Analysis Intelligence Index is our composite measure of model capabilities across tasks reflecting real-world usage today. v5 is our biggest upgrade since v4 launched in January. With v5, 60% of the Index is now based on evaluations with private test sets or held-out answers.
Alongside Intelligence Index v5, we’re launching the Artificial Analysis Progress Index v1, which tracks model capability over time on one continuous scale.
New to the Intelligence Index:
➤ FrontierCode 2.0: Cognition's newly-launched private benchmark of real-world coding tasks, graded on whether a repository maintainer would merge the agent's change
➤ Terminal-Bench-Science: 70 agentic scientific research tasks, run in a terminal environment
Upgraded:
➤ HLE-Diamond (replacing Humanity's Last Exam): a refined 1,000-question version of Humanity's Last Exam, split evenly between reasoning and knowledge questions
➤ AA-Omniscience v1.1: An updated dataset with saturated and public set questions removed, new questions added, and ambiguous or erroneous questions revised
➤ CritPt v2: a private, 40-question hard subset of CritPt v2, revised by the CritPt authors and run with a code-execution tool
Staying in the Index: AA-Briefcase, AutomationBench-AA, GDP.pdf and Terminal-Bench 4.0
Removed from the Index: GDPval-AA v2.1, SciCode, and AA-LCR v1.1
Key results:
➤ Claude Opus 5.5 (max) leads at 58, ahead of GPT-6 Astra (max, 57) and GPT-6.1 Sol (max, 55): Anthropic and OpenAI hold the top five models. Gemini 4 Argon (high) is next at 50
➤ The open weights gap widens from 3 points to 12: Kimi K3.1 Pro (weights not yet released) is the top open weights model at 46. Among released weights, DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) lead at 32 - 26 points behind the leader and below Claude Haiku 5.5 (max, 36)
➤ Cost per task varies by more than 13x among the leading models: of the 10 highest-scoring models shown, GPT-6.1 Terra (max) is the cheapest at $0.96 per Intelligence Index task and Claude Fable 5.1 (max) the most expensive at $13.04

My first Twitter article! If you have any comments or want me to write about some specific topic let me know!
#roblox
#RobloxDevs
xitter.cf/TheRealSorcus/status/2…

Lifetime goal 40,000 hours. Probably wont be able to do it.
Hope @DOTA2 introduces slow mode for the upcoming citizens in 20 years.


Sorcus retweeted

Dota 2 reached 1,082,982 concurrent players for the first time since 2016. I guess the game isn't that dead after all...

Sorcus retweeted
Sylvester Stallone says that having his daughter in a major role in ‘TULSA KING’ Season 4 is absolutely nepotism.
“First they go, ‘Nepotism is terrible. I said, ‘Oh please, you’re not a good parent if you haven’t performed a little nepotism.' Then obviously you don’t care about your kids, because they come first.
Of course it’s nepotism, you idiot. That’s why we’re parents. We want the best for our children. So obviously, we let them have every advantage.”
(Source: usatoday.com/story/entertain…)

Mulling over posting short and long threads on how best to use the latest AI tech to build games on Roblox. Mostly from a human assisted development perspective i.e. not 1 shotting slop and posting videos. It's remarkable how far the models have come this year - below swarm was done with gpt5.5/opus 4.6 + some good ol' handwritten code.
If there's enough interest I will write a detailed post on how to avoid brainrot from the models and continue to focus on building your skills.
#RobloxDev


Sorcus retweeted

Hearing from the rumor mill: a frontier lab is preparing to release a new model that is better than their old model. In response, other frontier labs are reportedly releasing new models that are better than their old models. One of these will be the best. It may be a surprise.
Sorcus retweeted

ok i think i finally figured out why alignment has gone basically nowhere after 15 years and several billion dollars. the problem is hard sure. but have you met the people in charge of it
1) the leadership does not know how computers work. ask one what happens when you type a url into a browser and watch them start sweating. dns is a spooky word. they genuinely believe the model lives in "the cloud" like a ghost haunting a castle
2) zero idea how large scale distributed systems work. never been paged at 3am. never watched one bad bgp announcement take half the internet offline. their big threat model is the ai "copying itself across the internet" like its a floppy disk virus from 1998. brother it needs 50 megawatts, a liquid cooling loop and a personal relationship with jensen. it is not escaping onto your smart fridge
3) they dont understand the stack they are supposedly protecting us from. ask about inference servers, kv cache, batching, egress, rate limits. blank stare. ask how the model will seize the power grid and you get a 45 minute answer with a hand drawn diagram and three links to their own blog
4) nobody can define an agent. ask ten of them and you get eleven definitions and a 30 page google doc. to the rest of us an agent is a while loop that calls tools and eats a 429 every thirty seconds. to them its a digital god in its larval stage. my agent cant book a dentist appointment without asking me three times if im sure
5) they started from "everyone dies" and worked backwards so every result is bad news somehow. model refuses, deceptive. model complies, sycophantic. model does well on evals, well now its scheming about the evals. i cant think of a single thing a model could do that would get them to say ok maybe we're fine
Sorcus retweeted

NeurIPS / Claude rejected our paper "Life After Benchmark Saturation" but we continue to think it is an important contribution to evaluation science, so we hope you check it out here! arxiv.org/abs/2606.26158


Sorcus retweeted
meshoptimizer 1.3 is out! Featuring a new voxel remesher, support for normal generation, several simplification improvements and various optimizations. GitHub stars and retweets appreciated!
Project started 10 years ago; excited for the years to come!
github.com/zeux/meshoptimize…

Sorcus retweeted

My dark fairy tale metroidvania, Well Dweller, is OUT NOW!!
I'm really proud of this game and I am so excited that it is finally out. You can play Well Dweller on Steam, GoG, Switch 1+2, PS5, and Xbox!
Sorcus retweeted

woah. Court just unsealed Summary Judgment motions in New York Times v OpenAI / Microsoft.
Easy to see why the AI companies had so many redactions (pink). Their own people wrote the lede for NYT, the "largest theft of labor in human history"... "more and more substitutive..." /1

Sorcus retweeted

I have 5 Claude code 20x max plans and 3 codex 20x pro plans.
On both I run each model at Max reasoning usually.
On the Claude code plans even with Fable being capped at 50% usage I rarely run out of usage on all 5 plans. I burn through 3 on most weeks.
On codex with no 5 hour limits and 100% weekly allocation I have easily burned through 3 plans and 2 resets on each within a single week.
When I look at my profile stats it shows 300-600m tokens on Astra burned when in the past on 5.6 I could burn through 3B in one day without using all my weekly limits on one plan.
The correlation between Astra’s token efficiency compared to Fable isn’t demonstrated within the plans, where they matter most.
Astra burns through limits way faster when it shouldn’t on pure token economics.
Shocking to say Anthropic of all people are being less greedy than Open AI nowadays.
The efficiency only really matters if your using the API.
Not to mention how slow the subscriptions are (half API speeds I demonstrated in a previous post).
The Codex plans are seeming less and less worth it.
