





Yue Fan retweeted

🚀 Call for papers: 4th Workshop on Advances in Language & Vision (ALVR) 🌐
In conjunction with ACL 2026 • San Diego
We’re calling papers on multimodal learning, LVLMs, reasoning, agents, ethics & more!
📄 Submit your work on vision-language research!
🔗 alvr-workshop.github.io/

I will be there in the morning helping setting up the poster, answering questions, and connecting the first author @KaizhiZheng (in China right now) to the audience.
I really look forward to meeting old/new faces there. See you soon!


Excited to be at #CVPR2026 in Denver! This week:
🏆 Best Paper Award Runner-Up (WMAS)
🎤 Two keynote talks
📌 Two conference posters
Across these projects, we’re pursuing a common vision for Agentic AI: agents that can reason in latent space, develop situated awareness of the real world, and continuously evolve from experience.
Looking forward to great conversations and catching up with friends old and new!

Not sure why DeepSeek put down their new Thinking with Visual Primitives paper, but I am glad to see this research direction is thriving!
Tho I feel like they could be clearer about all the prior works. For example, our GRIT project use almost zero human labor to generate the data, while DeepSeek paper said “Recent works [6, … These approaches are often confined to high-resolution benchmarks
where the challenge is “seeing” rather than “reasoning”, and their reliance on labor-intensive
supervision further limits scalability.”
DeepSeek V4 Multimodal paper: k-a.in/Thinking_with_Visual_…
Our GRIT paper: arxiv.org/pdf/2505.15879
Yue Fan retweeted

Excited to see our GRIT method cited and further advanced in the DeepSeek V4 Multimodal paper!
When OpenAI was relying on external tools for "thinking with images", we firmly believe in utilizing and scaling MLLMs’ native grounding abilities. Great to see this direction validated and pushed forward.
Congrats to @YFan_UCSC and the team 👏


Yue Fan retweeted
📢 ALVR 2026 Update
We are looking for reviewers!
If you work on multimodal learning, VLMs, or related areas, sign up here:
👉 forms.gle/w13Nq7CobKm9v5Wz7
⏰ Submission deadline is tonight, don’t miss the chance to submit for paper awards!


🚀 Call for papers: 4th Workshop on Advances in Language & Vision (ALVR) 🌐
In conjunction with ACL 2026 • San Diego
We’re calling papers on multimodal learning, LVLMs, reasoning, agents, ethics & more!
📄 Submit your work on vision-language research!
🔗 alvr-workshop.github.io/
I successfully defended my PhD. Many thanks to my advisor and all the people that I have met during this journey especially those collaborators of mine. I am really honored to work with you all!
Huge congratulations to my PhD student #4 @YFan_UCSC on successfully defending his dissertation, “Building Human-Centered Multimodal AI Agents”! 🎉
Yue’s work tackles a deeply important question: how can we design AI systems that truly support and amplify human capabilities? His research spans accessibility-driven multimodal agents—enabling natural, assistive interaction across physical and digital environments—as well as advancing agent reliability through grounded reasoning and autonomous learning.
Beyond his impactful research (with papers publishing in top venues like ACL, EMNLP, NeurIPS, and ICLR), Yue led the UCSC Athena team to win Second Place in the Alexa Prize SocialBot Grand Challenge and contributed to the success of the JARVIS team in the Alexa Prize SimBot Challenge ($100K cash prize in total).
I’m incredibly proud of everything Yue has accomplished and excited to see what he does next. The future of human-centered agents is in great hands. 🚀


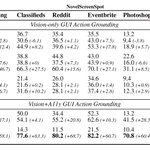
Let's make GUI agents safer! Welcome to checkout our new project. arxiv.org/pdf/2602.02419

🚨 New paper alert 🚨
📌 How can we make GUI grounding models reliable in real-world interactions?
We introduce 🚀 SafeGround: Know When to Trust GUI Grounding Models via Uncertainty Calibration
In GUI agents, a single wrong click isn’t just an error — it can trigger costly or irreversible actions (e.g., unintended payments 💸 or deleting important files 🗑️).
The real danger is silent failure: most GUI grounding models always output a coordinate, even when they’re unsure.
Instead of trusting a single predicted point, SafeGround:
• estimates spatial uncertainty from prediction variability
• calibrates a decision threshold with statistical guarantees
• enables risk-controlled GUI actions, even with black-box models
💻 Code: github.com/Cece1031/SAFEGROU…
📄 Paper: arxiv.org/pdf/2602.02419
🧵1/6
#Agents #GUI

2
370
🙋♂️ I will attend NeurIPS 2025 @ San Diego this week to present our work.
Welcome to checkout the poster of our "GRIT" project:
Location: Exhibit Hall C,D,E #4711
Time: Fri 5 Dec 11 a.m. PST — 2 p.m. PST
I’d love to chat and hear your thoughts! Look forward to meeting you all!
#NeurIPS2025 #MultimodalAI #VisualReasoning

Before o3 impressed everyone with 🔥visual reasoning🔥, we already had faith in and were exploring models that can think with images. 🚀
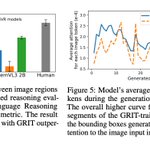
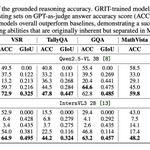
Here’s our shot, GRIT: Grounded Reasoning with Images & Texts that trains MLLMs to think while performing visual grounding. It is done via RL on just 20 examples, no SFT and no reasoning labels needed. 🧠
As a result, the GRIT method enhances and unifies MLLM’s grounding and reasoning ability.
🌐 Project page: grounded-reasoning.github.io…
📝 Paper: arxiv.org/abs/2505.15879
💻 Code: github.com/eric-ai-lab/GRIT.…
🧵1/6

🙌Checkout the new SAFER project led by our lab's talented intern @Ceeqnn.
SAFER enables LLMs to only output confident answers and abstain the others reliably based on an adjustable risk bound.
🚨 Building Reliable Open-Ended QA? Meet SAFER — Risk-Controlled Sample-then-Filter for LLMs! 🚨
SAFER introduces a two-stage framework that controls uncertainty and guarantees statistical reliability in open-ended question answering by dynamically calibrating sampling and filtering.
It helps models know when to trust their answers — and when to abstain.
💡 Why SAFER matters:
In real-world deployments, LLMs must respond responsibly — knowing when to act confidently and when to abstain or defer.
SAFER ensures that, with provable miscoverage control and minimal sample waste, LLMs can provide trustworthy answers under risk constraints.
#AI #LLM
📄 Paper: arxiv.org/2510.10193
💻 Code: github.com/Cece1031/SAFER
🧵1/5

2
774
Many thanks to my PhD advisor and all my internship mentors at Adobe. I couldn’t have done this without all your help and support.
🎉 Congrats to @YFan_UCSC for being featured @AdobeResearch!
Yue is the dream PhD student every advisor hopes for. 🚀 Over the past 4 years, he led a team to win 🥈 in the Alexa Prize SocialBot Grand Challenge and published multiple high-impact first-author papers, including:
- AVDN (the first aerial vision-and-dialog navigation paper)
- GRIT (teaching MLLMs to think with images)
- GUI-Bee (autonomous exploration for GUI grounding)
- R2H, Tree-of-Lens Grounding, Multipanel VQA, etc.
It’s been inspiring to watch Yue grow into an independent researcher and rising star in multimodal & agentic AI. As he enters his final PhD year (and the job market!), I can’t wait to see what he’ll cook up next.
Seize the top talent while you can! 🌟

2
751
Yue Fan retweeted
We’re thrilled to launch the MMIR Challenge at the #ICCV2025 CLVL Workshop! 🧠
🖼️ Task: Detect inconsistencies in multimodal artifacts (webpages, slides, posters)
🏆 Top submissions invited to present in the non-archival track at CLVL
🔗 Compete now → kaggle.com/competitions/mmir


🚨 Call for Papers – 6th ICCV 2025 Workshop on Closing the Loop between Vision & Language (CLVL), Decade Mark!
Celebrating 10 years of CLVL @ ICCV25! 🎉 Featuring an exciting speaker lineup, including speakers from CLVL’15; see details on linkedin link; bit.ly/3I0ADwD



Before o3 impressed everyone with 🔥visual reasoning🔥, we already had faith in and were exploring models that can think with images. 🚀
Here’s our shot, GRIT: Grounded Reasoning with Images & Texts that trains MLLMs to think while performing visual grounding. It is done via RL on just 20 examples, no SFT and no reasoning labels needed. 🧠
As a result, the GRIT method enhances and unifies MLLM’s grounding and reasoning ability.
🌐 Project page: grounded-reasoning.github.io…
📝 Paper: arxiv.org/abs/2505.15879
💻 Code: github.com/eric-ai-lab/GRIT.…
🧵1/6
🧵5/6
🌟 Representative examples (screenshots below):
1. Counting – the model first delineates every relevant region, then revisits its chain of thought to verify the final tally.
2. Spatial reasoning – critical regions (e.g., cat and truck) are grounded before the model analyzes their spatial relationship.
3. Absence handling – the model accurately rejects the presence of a non-existent object, producing no superfluous boxes.


1
4
353
🧵6/6 📷 Thanks to all the collaborators from both UC Santa Cruz, Xuehai He @XuehaiH, Diji Yang , KaizhiZheng @KaizhiZheng and eBay Ching-Chen Kuo, Yuting Zheng, Sravana Jyothi Narayanaraju, Xinze Guan. Special gratitude to my advisor Prof. Xin Eric Wang @xwang_lk for constant guidance and support. 📷📷 #UCSC
3
304