

We are a local AI-focused lab researching and developing optimized performance for vLLM on SM12x hardware for open models.
United States
Joined December 2025
- Tweets91
- Following14
- Followers2.7K
- Likes220





Pinned Tweet
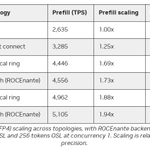
With our help, @NVIDIAAI just made 8-node DGX Spark clusters official.
Same hardware, two scaling results:
>Training a 900M model from scratch: 7.79x, 97.4% scaling efficiency.
>Serving a 27B across the same eight nodes: 1.94x prefill, 4.43x decode.

Local Inference Lab 🧪 retweeted
With our help, @NVIDIAAI just made 8-node DGX Spark clusters official.
Same hardware, two scaling results:
>Training a 900M model from scratch: 7.79x, 97.4% scaling efficiency.
>Serving a 27B across the same eight nodes: 1.94x prefill, 4.43x decode.
NVIDIA’s own fix is Switchyard, sending easy requests to a 2B model and keeping the 753B for the hard ones. 3x the aggregate throughput from the same nodes.

This was all built on top of the work of Local Inference Lab's RoCEnante as a foundation.
And it's just the beginning.
We are so excited to keep sharing our innovations that help your local AI experience get better and better.
Read more here. 👇😎
developer.nvidia.com/blog/ru…

We are just getting started.

Oh hey would you look at that? A new inference engine dropped called Flare.
Optimized specifically for sm12x hardware.
Better performance. More room for KV cache.
All with best in class support for the latest models.
Crazy stuff is happening at @YourLocalAILab and @NVIDIAAI.

Local Inference Lab 🧪 retweeted

Oh hey would you look at that? A new inference engine dropped called Flare.
Optimized specifically for sm12x hardware.
Better performance. More room for KV cache.
All with best in class support for the latest models.
Crazy stuff is happening at @YourLocalAILab and @NVIDIAAI.


Local Inference Lab 🧪 retweeted

@YourLocalAILab ftw

🚨 @NVIDIAAI just quietly dropped its own local inference server...
No announcement. Single-digit stars
It's called Flare and Apache 2.0
Built for SM120/SM121 GPUs RTX PRO 6000 Blackwell and DGX Spark
>PyTorch + FlashInfer at build time
>Rust runtime at serve time. No Python.
>CUDA graphs captured before serving
>FP8 KV cache by default
>Recipes for Qwen Flash, GLM and DeepSeek
github.com/NVIDIA/flare-loca…

Local Inference Lab 🧪 retweeted
We have been hard work in the kitchen. Proud of the crew @YourLocalAILab .
This quoted post is unavailable.
Local Inference Lab 🧪 retweeted
The results for KLD across the various quants with the trellismx quant technique .


DeepSeek-V4.1-Flash-1017 in TrellisMX K2 Mix, laid out for two RTX PRO 6000s: 2-bit experts, with the 629 that matter most raised to 3- and 4-bit by ShapleyMCG allocation, sized to keep ~3M tokens of KV. Engram tables in 4-bit TrellisMX. Mean KLD 0.1306 nats, 8.6% below plain K2. A +5 GB sibling for ~2M KV is up too. Only KLD measured so far; serving is a test image.
The whole build and every KL-divergence measurement ran on an 8x B200 node generously donated by @LambdaAPI. Thank you, Lambda!
huggingface.co/brandonmusic/…

Local Inference Lab 🧪 retweeted
Local Inference Lab is cooking! Get DeepSeek V4.1-Flash-1017 with up to 30% more room for KV cache!
All you need are these drop-in replacement weights and you can have lossless compression.
I use it myself and it makes a big difference. Gives me about 3 million more tokens!
Get up to 30% more KV cache using our lossless CSF version of @deepseek_ai V4.1-Flash-1017.
No drop in quality, just more room for you to do what you want to do!
Find the weights on our @huggingface page:
huggingface.co/local-inferen…

Local Inference Lab 🧪 retweeted

Fantastic work by @YourLocalAILab !! CSF is 🔥🔥🔥
Local Inference Lab 🧪 retweeted
Want to run DeepSeek V4.1-Flash-1017 on just two RTX Pro 6000s?
My buddy @BrandonMusicKy has you covered.
This guy is a wizard when it comes to quantizing models.
Recommend giving him a follow and tracking his work.
New: DeepSeek-V4.1-Flash-1017 in 3-bit TrellisMX, laid out for three RTX PRO 6000s, Engram tables at fp8 ngram. Mean KLD 0.0664 nats. With sufficient ram, it's been capable of running two sparks as well.
The whole build and every KL-divergence measurement ran on an 8x B200 node generously donated by @LambdaAPI. Thank you, Lambda!
huggingface.co/brandonmusic/…

Our team created the technology behind CSF to give your local machines even more capacity for long workflows, large swarms and other tasks.
It's lossless, too. Meaning you don't lose any of the data you are caching by using it.
Enjoy your new free KV cache tokens!
Get up to 30% more KV cache using our lossless CSF version of @deepseek_ai V4.1-Flash-1017.
No drop in quality, just more room for you to do what you want to do!
Find the weights on our @huggingface page:
huggingface.co/local-inferen…
Get up to 30% more KV cache using our lossless CSF version of @deepseek_ai V4.1-Flash-1017.
No drop in quality, just more room for you to do what you want to do!
Find the weights on our @huggingface page:
huggingface.co/local-inferen…
Local Inference Lab 🧪 retweeted
You can run it on @YourLocalAILab KK image if vLLM
Support already built in. Go to docker.local-inference-lab.a…
Local Inference Lab 🧪 retweeted

If you haven't heard of Local Inference Lab @YourLocalAILab you are not likely running local models as fast as you could be.

