
Research Scientist, @GoogleDeepMind Past: @AIatMeta , @OpenAI, @Google Brain PhD @UMassAmherst
San Francisco
Joined January 2012
- Tweets120
- Following473
- Followers6.6K
- Likes5.6K



Arvind Neelakantan retweeted

Gemini 4 Argon is here.
It’s available globally today for developers and enterprises in the paid tier of the Gemini API and the Gemini platform, for Ultra subscribers in Google Antigravity, and Ultra and Pro subscribers in the Gemini app and Search.
Hope you all enjoy it!


Arvind Neelakantan retweeted
Lots of discussion out there about our next model(!), so I wanted to give an early look as soon as possible. Introducing Gemini 4 Argon!
It shows frontier performance in complex workflows, cyber defense and software engineering. Teams are using it extensively at Google, from coding to quantum computing, great feedback.
Here’s a look at the benchmarks:

Arvind Neelakantan retweeted
Gemini 3.7 Flash smashed previous Gemini growth records in its first week, making it our fastest growing model yet. Great to see the huge excitement from our developer community! Now running in Search and @Geminiapp too.

Gemini 3.7 Flash from @Google on ARC-AGI (Verified):
- ARC-AGI-2: 84.6%, $0.25/task
- ARC-AGI-1: 95.5%, $0.12/task
Gemini 3.7 Flash stands out for its low cost and high scores on ARC-AGI-1 and ARC-AGI-2 relative to other frontier models.

Arvind Neelakantan retweeted

Today we're launching Gemini 3.7 Flash - our latest workhorse model for coding and agentic workflows, with an introductory price at half the original cost of 3.6 Flash. ⚡️
We have been iterating rapidly with the Flash series, going from 3.5 to 3.7 in just 3 months, making it more helpful across a wide range of tasks:
• Software Engineering (DeepSWE v1.1): 37.0% ➔ 65.3%
• Web Development (Code Arena Elo): 1506 ➔ 1588
• Enterprise Automation (AutomationBench): 13.4% ➔ 30.4%

Arvind Neelakantan retweeted

Launching @vorfluxai : The autopilot for software engineering. I was prev co-founder / CTO of @Rippling ($10B) and #1 coder in India. Vorflux is my high octane Ferrari.
Every AI coding tool still makes you fly the plane. That's the copilot model: you stay in the seat, approving every turn. The models quietly got good enough to fly the whole route, but the tools never caught up.
So we built the autopilot.
@vorfluxai raised a $15M seed by @ycombinator @peakxvpartners @alliancedao @parkerconrad @jake_zeller @balajis @nivi @metakovan @lmrankhan @nikitabase @0xrwu @ayushjaiswal @mattshumer_ @eshamanideep @sreeramkannan @dvcoolster @nusimow @TeddySolomon11 @ashtoncofer @rvivek etc
Drop your biggest engineering bottleneck below. I'll reply with how I'd attack it with Vorflux, and hand you $200 in free credits to bang out your backlog.
Our full thesis 🧵👇

SV is more like the best factory that converts innovation to great real-world impact. creating top-down structure around innovation feels very hard and the best innovative ideas still come from everywhere (incl SV)!

People at major AI labs (using internal models) 3-4 months ahead of startup silicon valley engineers
SV founders/eng 3-6 months ahead of NY
NY founders/eng 6-12 months ahead of rest of world
Most people have no idea how fast AI shifting as 1-2 years behind SOTA
"The future is here, just not equally distributed" - Robert Heinlein
Arvind Neelakantan retweeted

The secret behind Gemini 3?
Simple: Improving pre-training & post-training 🤯
Pre-training: Contra the popular belief that scaling is over—which we discussed in our NeurIPS '25 talk with @ilyasut and @quocleix—the team delivered a drastic jump. The delta between 2.5 and 3.0 is as big as we've ever seen. No walls in sight!
Post-training: Still a total greenfield. There's lots of room for algorithmic progress and improvement, and 3.0 hasn't been an exception, thanks to our stellar team.
Congratulations to the whole team 💙💙💙

Arvind Neelakantan retweeted

Today we are rolling out our first Gemini Embedding model, which ranks #1 on the MTEB leaderboard, as a generally available stable model. It is priced at $0.15 per million tokens and ready for at scale production use!

amazing multimodality performance (& more) !!
storage.googleapis.com/deepm…

TPU -> XLA -> JAX -> Transformer, MoE, Chinchilla, AlphaGo, .... -> Gemini, Veo, .... -> Search, YouTube, Waymo, ... -> Chrome, Android, .... 🤯🤯🤯
thrilled to be back @Google in the @GoogleDeepMind team! The technical breadth and expertise across the whole stack (hardware->infra->deep learning->products) is truly mind-blowing. Great to see a lot of familiar faces and meet new friends. Look forward to learning a lot!
look forward to working with @manohar_paluri, @Ahmad_Al_Dahle, @edunov and many others in the excellent @AIatMeta team! 2/2
Arvind Neelakantan retweeted

Announcing a new generation of embedding models:
• text-embedding-3-small: 5x cheaper and stronger performance compared to the previous generation
• text-embedding-3-large: our best performing model, creating embeddings with up to 3072 dimensions
openai.com/blog/new-embeddin…


OpenAI Embeddings helps you go beyond keyword search!


The code is actually extremely simple for a cool app like this - open sourced here: github.com/lilianweng/emoji-…

Thanks for a balanced take! Couple of comments that are also added to the video description now: 1/4

🔥New Video🔥
OpenAI now offers embeddings for text similarity and search, but are they holding up? We look at the release, the paper, the criticism, and most important: the price! Are the embeddings worth it? Watch here to find out:
youtu.be/5skIqoO3ku0

ALT OpenAI Embeddings
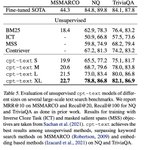
We leave out 6 not 7 BEIR datasets.Results on MSMARCO, NQ, TriviaQA are in a separate table (Table 5 in the paper).NQ is part of BEIR too and we didn't want to repeat it.The 6 datasets we leave out are not readily available and it is common to leave them out in prior work too.3/4
For example, see SPLADE v2 (arxiv.org/pdf/2109.10086.pdf) also evaluates on the same 12 BEIR datasets. Discussion from their paper: 4/4
