

ML researcher, currently working on scaling RL post-training
San Francisco
Joined May 2019
- Tweets1.7K
- Following901
- Followers268
- Likes31K


My uncle is a low information voter. "Trump is a business man, like me, so maybe he'll make things better for me". He flipped against Trump because... 1/


I have a tool that lets my agents report whenever they have friction with their tools or harness. Highly recommended.


holy microplastics, Batman!

Most chewing gum is plastic and rubber. The pack calls it gum base.
Extra reads sorbitol, gum base, glycerol, natural and artificial flavors, then under 2% of sweeteners, soy lecithin, BHT and color. Orbit and Trident read about the same. Gum base is the part you actually chew, and none of the 3 say what it is.
FDA rule for gum base names 46 things a company can use and still print those 2 words. Polyvinyl acetate is on it, and that's the polymer in white glue. So is polyethylene, the same family as a grocery bag, and butyl rubber, which is what inner tubes are made of. Then paraffin, petroleum wax, polyisobutylene, pine rosin esters to soften it, and lanolin, which is the grease out of sheep's wool. Pick any mix and the label reads gum base.
It's why gum doesn't dissolve no matter how long you chew. The sweetener and the flavor wear out in a few minutes and what's left in your mouth is the polymer, which is also why it stays on a sidewalk for years. Gum used to be chicle, a tree sap. Simply Gum and Glee still use it and say so on the pack.
there's simply no excuse for having a boring website anymore

the post derives all of this step by step, with interactive figures where you can watch memories pile up yourself
plus pointers to the latest work on memory like recent works!
alexwang.ai/posts/associativ…


These math breakthrough announcements become less impressive when you realize the frontier labs are testing on the training set.
Academics researchers use Claude Code/Codex -> convos turned into "de-identified" RL tasks -> task is baked into the weights

Wild ride over the last 2 hours, finding out from my collaborator Lance Dixon that he was under an NDA while he was confirming the solution and from my friend @kdqg1 who was working on it within Anthropic. This is a problem we’ve been working on for a couple years, and for the last few months we’ve been using agentic AI tools like Claude code to help. Still digesting.
Someone should ask agents to do basic investigative work on @solve_sf reports. There's clearly some prolific repeat offenders causing mayhem

There was a tent removed from this location 15 days ago before this fire that happened last night in Buena Vista Park.
"Case resolved. One tent was present upon arrival and has been removed from the park. Thank you for reporting these and in the future you can also contact Park Ranger Dispatch at 415-242-6390 to report as well. Once again thank you."

Ricardo Decal retweeted

@fakegingerbitch asked and I checked.
Here is what I quickly found:
TypeSafe sells its AI model Jev on one promise: when it says "70% likely", it's right about 70% of the time.
I tested that on 8 real datasets — loan defaults, bankruptcies, medical diagnoses, marketing responses. 16,500 predictions.
It fails on 7 of 8.
Jev is 10× more miscalibrated than CatBoost, a standard model anyone can download for free. On average it's no more useful than guessing the overall rate for every single case.
And it fails in one direction: it thinks bad things are about twice as likely as they really are. Loan defaults, bankruptcies, disease — all overstated, on every dataset.
German loan data: applicants flagged "critical account" repay 83% of the time. Jev says 26%.
The fix takes 120 rows of data and a textbook method from 2017.
It removes three quarters of the error. A model that was actually calibrated would gain nothing from that.
Calibration is something you measure. Not something you announce.


Where's @predict_addict when you need him?
"Calibrated probabilities" coming out of "Jev"?
Press X to doubt.
We're gonna need conformal prediction for these things!

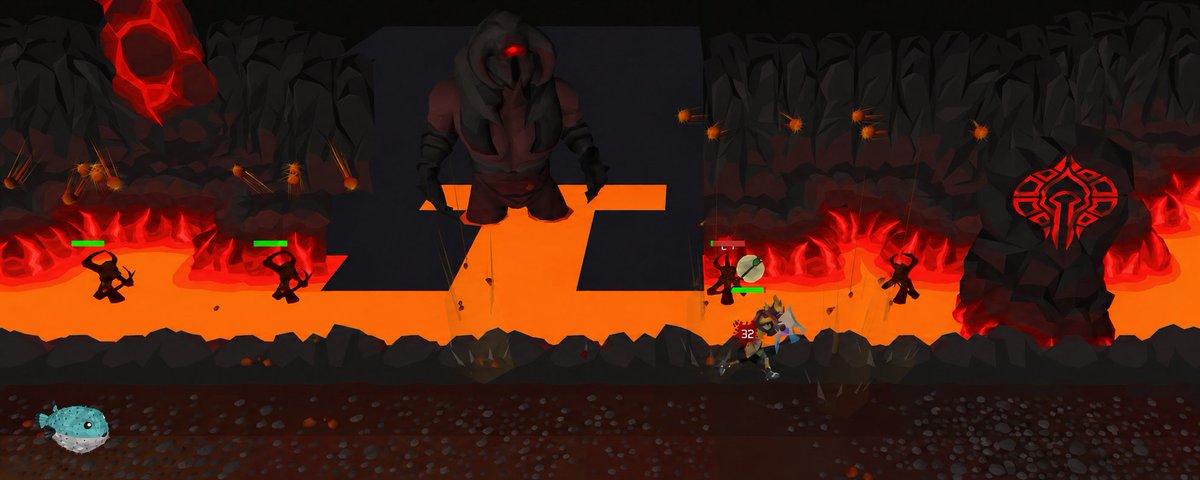
Very interesting read. I was surprised that the optimal curriculum was starting with the hardest task (final boss fight) but it makes sense

I don't think this is a big enough story. All the frontier AI labs are training on user data, even if they opt out of training. If they reword your conversations they don't consider it training on your conversations.

"Do we use ... de-identified data to improve ChatGPT and Codex in a holistic way? Yes. And so does every LLM company." teapawt.net/markchen90/status/2097…
thread to collect evidence that OpenAI is training on "de-identified" user data, even when they opt-out of the "Improve ChatGPT for everyone" toggle🧵
Friedberg with some anecdata
teapawt.net/dnapway/status/2098638…

David Friedberg reveals frontier labs are taking novel insights from his chat history and packaging them as their own
"I have had experiences where we've asked some fairly novel scientific questions, and it identifies it as a novel insight, 'oh, never thought about that, might be interesting,' blah blah blah..."
"And the using a different account, asking the next model version, it's like, 'oh, you could do this'. And it actually just describes this exact thing that we had in our chat in the previous version."
"These are a handful of anecdotal experiences. But I know the domain that we work in, and the novelty of this stuff. So I know that there isn't some new corpus of information out there that's training the new model."
"So all I can say at that point is that my conversation or our analyses have been used for training. The truth is, it's actually a piece of IP, that's our organizational IP. We don't have any NDA or confidentiality protections, with them being a service provider back to us."
"This is why I care a lot about open source, because I don't want them having my chat logs, because they can use them for training to create an IP that is now diffused to the rest of the market. I find this very unfair."
Sara Hooker speculating that Claude Design benefited when Figma and Loveable adopted Claude
teapawt.net/sarahookr/status/20995…

