





base.chase176 retweeted

이제 모두 다한번 상향평준화?

Claude code source code has been leaked via a map file in their npm registry!
Code: pub-aea8527898604c1bbb12468b…

base.chase176 retweeted

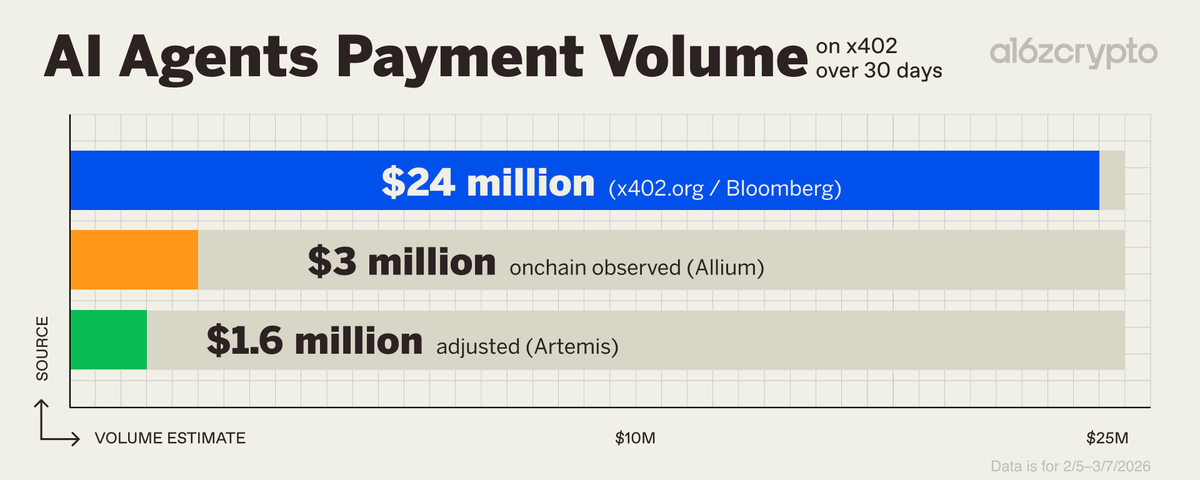
"Most of the x402 numbers circulating are noise.
@OnchainLu, an analyst at Artemis Analytics, built a wash trading filter for x402 volume, flagging wallets that repeatedly transacted with themselves or cycled funds between addresses.
Applied over the same 30-day period, the adjusted number is $1.6 million."


base.chase176 retweeted

Qwen3․5 파인튜닝 가이드
- Qwen3․5 모델군(0․8B~122B) 을 LLM 파인튜닝 및 강화학습용 오픈소스 프레임워크인 Unsloth로 텍스트 및 비전 기반 파인튜닝을 할 수 있음
- Unsloth는 FlashAttention-2 대비 1․5배 빠른 학습 속도와 VRAM 50% 절감을 제공하며, bf16 L…
news.hada.io/topic?id=27225

base.chase176 retweeted

We’re making it easier for crypto founders to do what they do best. These tools are already used and trusted by 100+ top crypto teams.
Meet industry best practices, streamline all areas of token launch/operations, and unlock more time to focus on building great products.


base.chase176 retweeted

Did you know how fees save LPs?
Mispricing stays inside this zone most of the time.
This paper explains it in full.
Full doc: arxiv.org/pdf/2305.14604


base.chase176 retweeted

Jane Street Sued For Crypto Insider Trading That Accelerated Terraform Collapse zerohedge.com/crypto/jane-st…


base.chase176 retweeted

Introducing Claude Code Security, now in limited research preview.
It scans codebases for vulnerabilities and suggests targeted software patches for human review, allowing teams to find and fix issues that traditional tools often miss.
Learn more: anthropic.com/news/claude-co…
base.chase176 retweeted

안녕하세요, Based Builder 여러분!
혹시 한국 Base 개발자 커뮤니티 그룹이 있다는 사실을 알고 계셨나요?
저희 Based Korea에서는 Base 생태계에서 프로덕트를 빌드하는 개발자들을 위한 TG 그룹을 운영하고 있습니다.
이곳에서는 Base Builder Quest, Onchain Summer Awards와 같은 개발자 프로그램 소식은 물론, 한국 개발자들 간에 정보를 나누고 서로 도움을 주고받을 수 있습니다.
아직 참여하지 않으셨다면, 편하게 연락 주세요. 초대 링크를 보내드리겠습니다.
Do Based!
#Base #BasedKorea #BaseKoreaDeveloperGroup

base.chase176 retweeted
🚨: Scientists mapped 1 mm³ of a human brain ─ less than a grain of rice ─ and a microscopic cosmos appeared.


base.chase176 retweeted

LLM 모델의 인과적(causal) 어텐션 구조(텍스트를 좌측에서 우측으로 읽을 뿐)의 한계(맥락과 질문의 비대칭)가 야기하는 성능 저하를 극복하는 간단한 방법을 논문으로 증명한 BURKOV(@burkov)의 포스팅입니다.
“같은 프롬프트를 (그냥) 두번 반복하십시오.”
#LLM #prompt

LLMs process text from left to right — each token can only look back at what came before it, never forward. This means that when you write a long prompt with context at the beginning and a question at the end, the model answers the question having "seen" the context, but the context tokens were generated without any awareness of what question was coming. This asymmetry is a basic structural property of how these models work.
The paper asks what happens if you just send the prompt twice in a row, so that every part of the input gets a second pass where it can attend to every other part. The answer is that accuracy goes up across seven different benchmarks and seven different models (from the Gemini, ChatGPT, Claude, and DeepSeek series of LLMs), with no increase in the length of the model's output and no meaningful increase in response time — because processing the input is done in parallel by the hardware anyway.
There are no new losses to compute, no finetuning, no clever prompt engineering beyond the repetition itself.
The gap between this technique and doing nothing is sometimes small, sometimes large (one model went from 21% to 97% on a task involving finding a name in a list). If you are thinking about how to get better results from these models without paying for longer outputs or slower responses, that's a fairly concrete and low-effort finding.
Read with AI tutor: chapterpal.com/s/1b15378b/pr…
Get the PDF: arxiv.org/pdf/2512.14982


