

The frontier AI lab for the hardest problems in science and engineering
Joined March 2026
- Tweets63
- Following2
- Followers1.5K
- Likes16





Pinned Tweet
1/
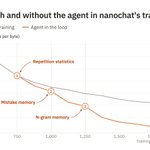
What if an LLM could not just edit a model's weights, but re-architect it as it trains?
We tried just that. The resulting architectures exit the known territory of transformers: the coding agents spliced code directly into the network.
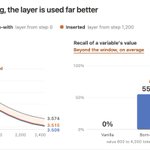
On nanochat, the loss fell below ordinary training after each new code layer was introduced. On algorithmic reasoning, accuracy rose from 55% to 84%. We even let DeepSeek-V4.1-Flash act as the agent modifying itself, raising its AIME and HMMT 2026 score from 64% to 71%.
To do all this, the agents built a set of tools we’ve never seen before, which we call mechanistic intervention!
Blog: doubleai.s.gy/llm-redesign

1/
We set Maxwell to optimize DeepSeek-V4.1-Flash serving on B200s.
Maxwell’s engine outputs 3x more tokens per GPU than vLLM at the same speed per user, or serves 2x speed per user for typical loads.
It beats every published B200 setup, and is even faster than all comparable GB300 results.
Blog: doubleai.s.gy/gb300
2/
We measured the engine on @SemiAnalysis_ AgentX.
Maxwell's engine handles all loads. As traffic changes, it switches strategy, swaps kernels and reschedules requests, all without downtime while serving.
That's a step change.
The published vLLM and SGLang results are tuned one load at a time, so each point on their curves is its own configuration. Maxwell's whole curve is one running engine.
13
1,813
5/
We are even seeing signs of open-weight models being able to perform these changes on themselves.
We asked DeepSeek-V4.1-Flash to make itself better at competition maths. It analysed its activations and found where its own hidden states signal a wrong answer on these tasks. It then wrote a code layer that helped boost its performance on AIME 2026 and HMMT 2026 by predicting such failures before committing to an answer.

1/ Together with @ltx_io, we used Maxwell, our Code Execution Model, to make video generation in LTX-2.5 1.87x faster.
With Maxwell, generating a five-second 4K clip on 2xB200s went from 250 seconds to only 134. No quantization or loss of quality at all. The code is open source.
2/ Try Maxwell on your own workload: doubleai.s.gy/maxwell
LTX release notes: doubleai.s.gy/github-ltx-max…
Full technical blog: doubleai.s.gy/ltx-maxwell

6
917
4/ Brute-force search is hopeless here. Double Agent first proved structural facts about the geometry of checks on a chessboard, formalized them in Lean, and reduced the rest to SAT. Result: no such sequence can exceed 364 checks, with every proof machine-verified. The exact maximum remains open.
Code and proofs: doubleai.s.gy/chess
1
4
320

2/ A graph's girth is the length of its shortest cycle. Large girth means a graph looks like a tree for great distance around every vertex. Such graphs are key to constructing error-correcting codes. Since 1988, the best explicit graphs, due to Margulis and to Lubotzky, Phillips and Sarnak, had girth (4/3) log n, against a theoretical ceiling of 2 log n.

3/ double-agent completely autonomously found a deep algebraic construction and proved it, all on a budget of less than $2k. Its graphs reach girth (8/5) log n, and do so for infinitely many degrees. The full proof is formalised in Lean. Paper: doubleai.s.gy/girth85. Lean: doubleai.s.gy/girth85-lean