




jonah retweeted

PLAID-style late-interaction search has always had a slow half: exact rescoring. I made it nearly free in next-plaid with one int8 operation. Works on existing indexes, CPU only. Top bar is 1.6.5, bottom is 1.7.0. The "decompress" segment is gone. Thread.


jonah retweeted

Hierarchical pooling is very strong to reduce the footprint of late interaction without degrading results
We recently showed that training for MUVERA/SMVE improved performance retention
What if we trained for hierarchical pooling?
We get even stronger (5×) lossless compression!

jonah retweeted

Rescaling MLM-Head for Neural Sparse Retrieval
@yjoonjang et al. find that pretrained encoders with large MLM-head scales face degradation in sparse retrieval, and introduce a zero-cost rescaling correction to stabilize training.
📝 arxiv.org/abs/2606.18811

jonah retweeted
Whether you are GPU poor or GPU rich, today's release of PyLate has something for you!
GPU maxxers: MaxSim kernels greatly speed up training while lowering the memory requirements
CPU enjoyers: TACHIOM enables lightning fast multi-vector indexing and search directly on CPU

jonah retweeted

Introducing mxbai-rerank-v3-listwise: reranking that goes beyond binary relevance.
It reads the whole candidate set, resolves conflicts, and ranks by directives like recency, source priority, and multi-step rules.
+11% NDCG@10 on average across multiple domains, modalities, and languages in runs with Wholembed v3.
Available today in preview in Mixedbread.

jonah retweeted

I'm personally very bearish on MUVERA due to its many, many, failure cases, but I have a lot of respect for the @weaviate_io folks, so I gave this another deep read to see if there were things that could change my mind.
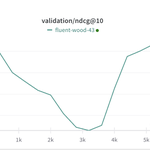
However this has me a bit puzzled, if I'm reading the graph below right, it means that MUVERA itself produces a ~50+% incompressible performance degradation at commonly used indexing parameters, and still a ~20% degradation at near-bruteforce search tier parameters (ef=1024), meaning that the degradation would be purely due to MUVERA itself.
For most retrieval uses, this would make the method completely unusable, as this degradation for many workflows is almost similar to the one we'd experience from replacing semantic search with pure bm25/keyword search.
I feel like I'm missing something here so I'm very happy to be corrected if I'm misinterpreting the results!


Multi-vector embeddings (ColBERT, ColPali) are budget killers.
But MUVERA can cut your memory footprint by 70%.
Multi-vector models offer incredible retrieval but suffer from massive memory overhead and slow indexing. MUVERA (Multi-Vector Retrieval via Fixed Dimensional Encodings) compresses these into single, fixed-dimensional vectors.
How it works:
MUVERA condenses a sequence of vectors (e.g., 100x96d) into one vector via:
1️⃣ Space Partitioning: Groups vectors into buckets using SimHash or k-means clustering.
2️⃣ Dimensionality Reduction: Applies random linear projection to compress each sub-vector while preserving dot products.
3️⃣ Repetitions: Repeats the process multiple times and concatenates results to improve accuracy.
4️⃣ Final Projection: Optional final compression (not used in Weaviate's implementation).
The impact (LoTTE benchmark):
- Memory: 12GB → <1GB.
- Indexing: 20+ mins → 3-6 mins.
- HNSW Graph: 99% smaller.
There’s a trade-off:
You trade a slight dip in raw recall for massive efficiency gains. However, by tuning the HNSW `ef` parameter (e.g., `ef=512`), you can recover 80-90%+ recall while keeping costs low.
When should you use MUVERA?
→ Large-scale production RAG
→ Systems where memory/infrastructure costs are the direct bottleneck
→ Use cases requiring fast indexing
MUVERA in @weaviate_io 1.31+ takes just a couple of lines of code. You can tune three parameters (k_sim, d_proj, r_reps) to balance memory usage and retrieval accuracy for your specific use case.
Read the full technical deep-dive here: weaviate.io/blog/muvera?utm_…

jonah retweeted
Information retrieval folks united at Séoul under beer, chicken and Jensen
@raphaelsrty @drexalt 🥰

jonah retweeted
We love supporting Open Source. All Open Source projects can power their docs, MCP and more with Mixedbread Search for free.

We’ve been running a @mixedbreadai-powered search on the Effect docs for about a month now, and the results speak for themselves:
→ More relevant results
→ Fewer “no results” dead ends
→ Easier discovery of advanced topics
Full write-up by @maxwellbrown ⤵️
effect.website/blog/how-mixe…

jonah retweeted

After months of work, HeavyBall 2 is finally here
This release comes with many new features and speedups, but has a focus on reliability
Therefore, it necessarily contains breaking changes
Make sure to read the release notes on GitHub before upgrading

jonah retweeted

my first acid trip i realized my eyes were attending to all tokens simultaneously and decided transformers are real

jonah retweeted

📢📢 RAG 2024 topics are officially now released!
Check the website for the released topics (301 in total): trec-rag.github.io/annouceme…
Let the games begin & please share and RT! 🤗
#TREC2024 #RAG

jonah retweeted

A bubbly, ambitious LLM engineer in the U.S. leaves her cushy tech vest-and-rest for an exciting job at Mistral, where her “scale is all you need” attitude comedically clashes with their open-weight, small-model culture.
MLE in Paris.
jonah retweeted

I am looking / on the market for a new ML Engineer / Researcher remote (EU times) role! 👨🔬
You can find my resume here 👉 afmck.in/cv.pdf
If I fit the bill for a role you have open, or someone you know has, please reach out!
Would appreciate sharing and RTs 🙏


jonah retweeted

An astonishingly good tutorial and annotation of Flash Attention code.
Recommended for anyone who wants to become a better at neural net programming.
arxiv.org/abs/2312.11918
jonah retweeted

magnet:?xt=urn:btih:5546272da9065eddeb6fcd7ffddeef5b75be79a7&dn=mixtral-8x7b-32kseqlen&tr=udp%3A%2F%2Fopentracker.i2p.rocks%3A6969%2Fannounce&tr=http%3A%2F%https://xitter.cf/t.co/g0m9cEUz0T%3A80%2Fannounce
RELEASE a6bbd9affe0c2725c1b7410d66833e24
jonah retweeted
Happy to OSS gpt-fast, a fast and hackable implementation of transformer inference in <1000 lines of native PyTorch with support for quantization, speculative decoding, TP, Nvidia/AMD support, and more!
Code: github.com/pytorch-labs/gpt-…
Blog: pytorch.org/blog/acceleratin…
(1/12)
jonah retweeted

Advent of code starts Friday, going to attempt to write them in cuda, and if the problem of the day can't be parallelized I'll make up a slightly different one for myself that can be, got repo all set up for cuda via rust: github.com/jessfraz/advent-o…


