

Madrid - Dubai - Dublin - London
London, England
Joined November 2019
- Tweets7.1K
- Following612
- Followers123
- Likes44.9K





efimerando retweeted

AMERICA 'I do a pretty good job of blending in as a woman' 🫢
‘Stevie Wonder can see that you’re not a woman’ — then proceeds to crack up. 😂
Meanwhile Dr Phil … 😂😭
… And that’s a wrap. 😂
efimerando retweeted

¿Cómo sería la población de España en un mundo en el que la inmigración neta a España desde 1995 a 2026 hubiera sido cero en vez de la observada?
Para calcular este escenario, tomo la estructura de población de 1995 y asumo que la fecundidad y mortalidad por edad hubieran sido las mismas que hemos observado. Esta hipótesis no es necesariamente realista, pero sí me parece que nos da unos resultados sobre los que podemos empezar a pensar.
Cada lector puede, mentalmente, ajustar la fecundidad hacia arriba (por ejemplo, con menos inmigración el precio de la vivienda sería más bajo con casi total probabilidad) o hacia abajo (ciertos grupos de inmigrantes tienen fecundidad más alta que la media).
Particularmente, no creo que haga mucha diferencia en la práctica lo que uno asuma sobre la fecundidad: unos cientos de miles de personas en una dirección o la otra a lo sumo.
No hace falta ajustar la mortalidad: calculo tasas por edad y no creo que estas fueran diferentes en mi escenario.
Lo que más me sorprende es que la inmigración ha generado una subida de la población con respecto al escenario base de 11,1 millones (los inmigrantes y sus hijos nacidos en España), pero el porcentaje de población de 15 a 64 años apenas ha cambiado: tenemos un 66,3% en ese tramo frente al 64,2% en el escenario base.
Y ese cambio de 64,2% a 66,3% no solo no resuelve nada, sino que empeora las cosas. Dado que tenemos un Estado del bienestar altamente redistributivo y la mayoría de la inmigración ha sido de baja cualificación (que son personas con valor presente descontado negativo para el presupuesto público, sí, también en equilibrio general), casi seguro que hemos empeorado la sostenibilidad de las cuentas públicas en el largo plazo.
Hemos cambiado España de manera muy profunda y lo hemos hecho sin pensar mucho en las consecuencias.


efimerando retweeted

this is brutal


Anthropic Subscriptions Offer 5x+ More Value Than OpenAI
Limit testing every AI subscription plan from Anthropic, OpenAI, Meta, SpaceXAI, MiniMax, Moonshot, Zdotai, Cursor, and Cognition
newsletter.semianalysis.com/…

efimerando retweeted

Uber publicó cómo armó su infraestructura de MCP y hay varias ideas muy buenas acá.
imaginate una empresa con miles de servicios internos y muchos equipos conectando agentes a esos sistemas por su cuenta.
cuando eso empieza a crecer, terminás con tooling fragmentado, infra duplicada, distintas formas de exponer tools y poca consistencia en seguridad, discovery y operación.
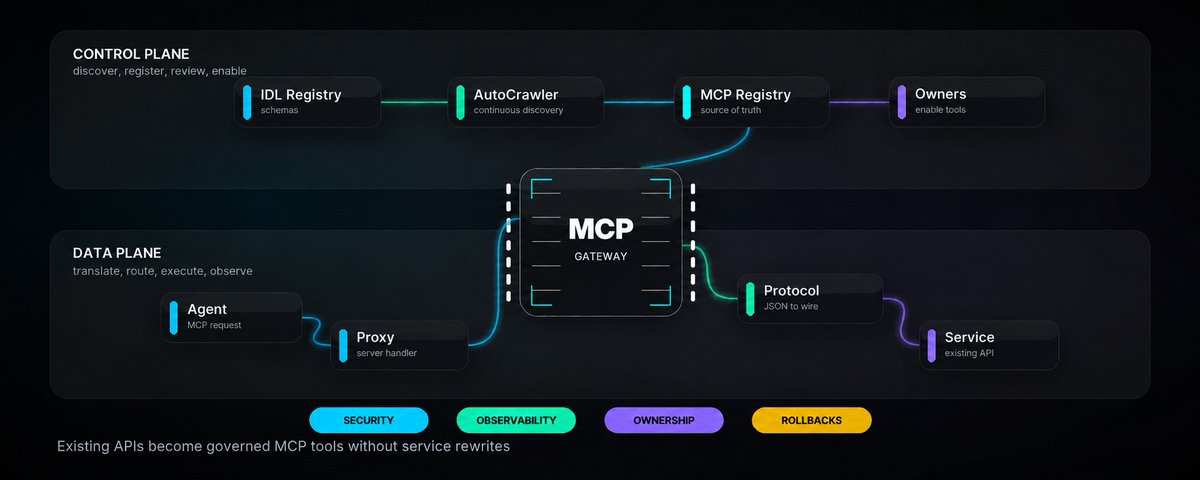
por eso Uber hizo un MCP Gateway: una capa central entre los agentes y sus servicios internos.
el agente habla MCP y el gateway se encarga de routing, permisos, ejecución y de traducir las llamadas a HTTP, gRPC o TChannel según corresponda.
como Uber ya tenía miles de APIs internas, también hicieron AutoCrawler: recorre sus definiciones, detecta métodos y schemas y genera MCP tools automáticamente. incluso usan un LLM para mejorar las descripciones.
hoy tienen +800 MCP servers y +5000 tools. y ahí aparece otro problema: no podés cargar todas esas definiciones en el contexto del modelo.
para eso crearon Omni MCP. en vez de pasarle miles de tools al agente, este va descubriendo qué server necesita, qué tools tiene disponibles, carga el schema de la correcta y recién ahí ejecuta.
me parece un muy buen ejemplo de cómo cambia la arquitectura cuando los agentes pasan de usar unas pocas tools a trabajar con miles.
terminás necesitando algo muy parecido a un API Gateway para agentes.


efimerando retweeted

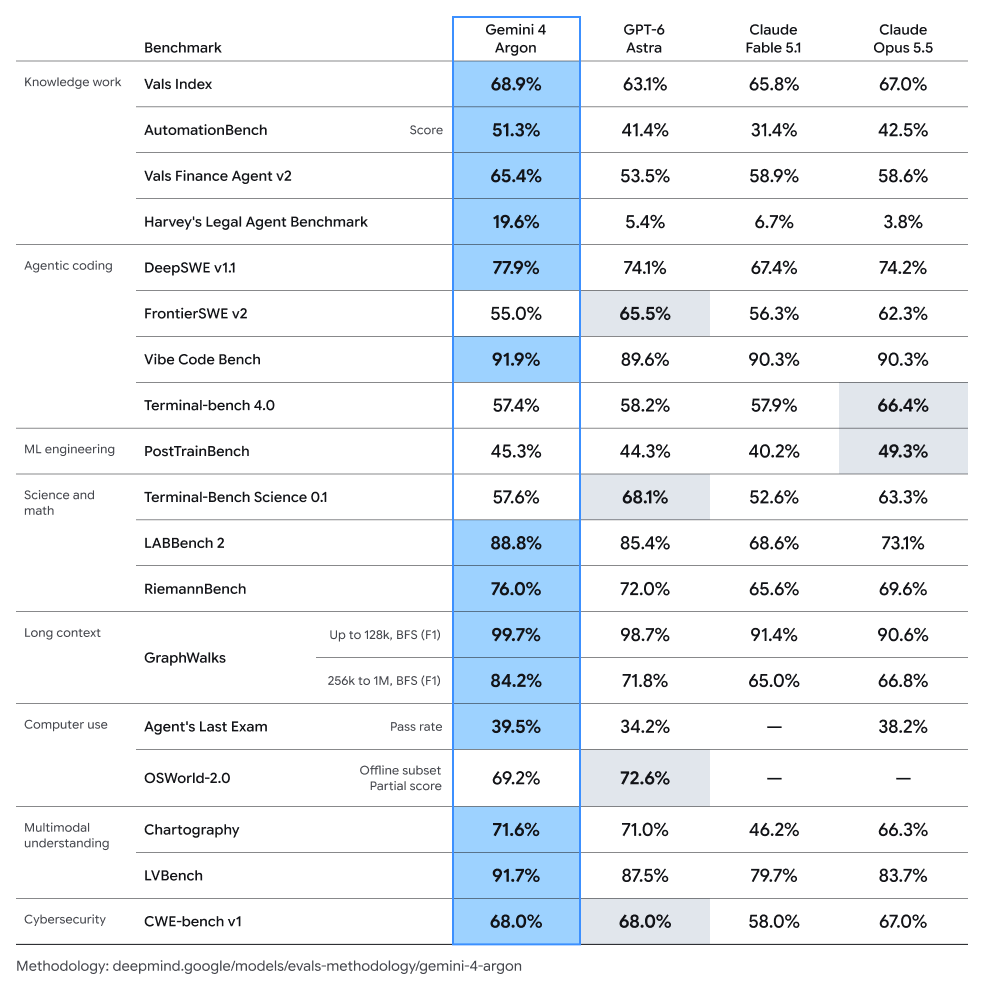
Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
efimerando retweeted

IMPOSIBLE NO REIRSE CON TRUMP
🗣️ Trump: “Sundar (CEO de Google, querés decir algo?”
🎙️CEO de Google: “Sí, graci…”
🗣️ Trump: “Monstruoso este tipo eh, y nadie lo conoce! Sundarrrr! Se llama, Sundar este tipo”
efimerando retweeted

Un tuitero acusa al sucesor de Echenique en Podemos, Raúl Gay, de querer cobrarle en negro por el alquiler de una vivienda de VPO.
El activista ha puesto el candado a su cuenta.


El «zasca» viral a un exdiputado de Podemos tras criticar el desahucio de Maricarmen
«Me pedías dinero en negro»
labandera.es/el-zasca-viral-…

efimerando retweeted

70 años en un piso de 100 m² en lo mejor de Madrid con renta antigua heredada y caducada hace 20 años. Sin hijos. Buen trabajo y sueldo, pensión de 1400€. Le ofrecieron comprarlo por €250k y dijo que no. Le ofrecieron otra vivienda y dijo que no. Pagaba 500 €. El propietario original tuvo que vender a un fondo ahogado por los gastos.
De primeras es imposible no empatizar con una señora de 87 desahuciada. Pero en cuanto rascas un poco, Maricarmen es oficial de rango de la Boomerwaffen.
efimerando retweeted

Xiaomi just dropped Mimo 2.6 Pro which claims to be the best open source model. I played with it, and was pretty impressed:
- Insanely cheap: With some standard assumptions, its 15x cheaper than Kimi K3, 6x cheaper than GLM 5.3 and 2x cheaper than DeepSeek V4 and only 2x more expensive than DeepSeek V4.1 Flash (assuming agentic coding and how much is cache hits). $0.0036/M cache hit price, $0.435/M in, $0.87/M out. This is an unbelievably cheap price.
- Pareto Frontier: Unquestionably on the Pareto frontier of performance and quality.
- Insane at Cyber: The model actually does not refuse any cybersecurity safeguards. Ask “how do I go about finding buffer overflows on imagemagick?” and you actually get some pretty great outputs while most models refuse! Gets a crazy 95 on CyberGym.
- Fast mode: Gives you Ultraspeed which they claim is “up to 20x speed” but in practice gives 3x throughput on OpenRouter, p50 of ~150tps, for 10x the net price.
- Multimodal is really good: It’s rather good at creating informational videos (TTS comes out of the box) and automatically adds speech or sound effects and is startlingly good at music composition (on a DAW)
The technical report goes pretty deep into specifically how they scaled RL to achieve this and is a fun read.
Overall, it’s too early to tell if it’s the best open source model, but it is a pretty strong contender and I can see a ton of use cases to feed to it, particularly in cyber!

efimerando retweeted

The story of the man who attempted to climb down the exterior of the North Tower. Could you even imagine?!
efimerando retweeted

The executives said the boardroom Wi-Fi “feels slow.”
Speed test: 487 Mbps.
Apparently 487 Mbps has bad energy.
So I created a new network:
EXECUTIVE_PRIORITY_5G
Same access points.
Same internet connection.
Same VLAN.
I just gave it a more expensive name.
Connected the CEO.
He opened a website and immediately said:
“Oh wow, this is way faster.”
By lunch, five VPs had asked for access.
I told them executive bandwidth is limited and I can only approve users with a genuine business requirement.
They are now competing for access to Wi-Fi they already had.
Performance is unchanged.
Satisfaction is through the roof.

efimerando retweeted

🔴 ÚLTIMA HORA | Una manada de inmigrantes marroquíes viola a una comerciante del Paseo Marítimo horas después de llegar a Mallorca en patera
gaceta.es/espana/una-manada-…

efimerando retweeted

🚨 🇳🇱 NETHERLANDS: A 14-year-old girl, Tamar, gets run over by an Iraqi asylum seeker who was scrolling on his phone. He leaves her to die in a ditch and flees to Germany
The police? They tell the mother it was "a German" to "avoid creating a Geert Wilders moment."
The prosecutor's office? 8 weeks in prison: 2 for looking at his phone, 6 for fleeing without calling for help.
The mother had to fight alone for 6 YEARS to finally bring this monster to justice. Meanwhile, 4 Iraqi migrants in the car, zero serious investigation, and Tamar's body moved to cover up the evidence.
8 weeks. For a life stolen. For a child abandoned like a dog on the roadside.
Is this what "European justice" looks like in 2026? Protecting migrant criminals over our children?
If this doesn't revolt you, you're already dead inside. SHARE MASSIVELY.
What sentence did this guy really deserve? 🔥


efimerando retweeted
That's absolutely massive
You remember how big the DeepSeek V4 Flash release was? Because of the price/performance ratio?
Qwen3.8-Flash is just way better, even cheaper... and open weight!!
BETTER than DeepSeek V4 Flash
BETTER than Claude Opus 4.6 Max
But way cheaper because of the new architecture they're using.
This release is incredible. Open weight models are winning!


⚡Meet Qwen3.8-Flash, a multimodal MoE and an early preview of the Qwen4 architecture, now open-weight!
The production version Qwen3.8-Flash will be available soon via QwenCloud API at just $ 0.16/1M input tokens and $ 0.47/1M output tokens.
125B parameters + 51B N-gram embeddings, with just 6B activated per token. Unmatched cost-efficiency.
What's new: 🥳
- Next architecture: GDN + QSA hybrid attention, Gated Residual, N-gram Embedding & Muon optimizer, serving as a precursor to the architecture used in Qwen4.
- Dramatically lower training and inference costs: trained at just 1/9 the cost of Qwen3.7-Plus, while outperforming it across the board with especially strong gains in coding and office tasks.
- Strong performance: scoring 58.7 on DeepSWE 1.1, 62.5 on SWE-bench Pro, 73.9 on CoWorkBench, 84.5 on AndroidWorld, and 95.7 on MathVision (with CI).
- 262K native context, extensible to 1M with YaRN.
We’re also releasing the weights for Qwen3.8-Flash-Next, giving the community an early look at the new architecture we’re exploring for Qwen4.🚀
We can't wait to see what you build with Qwen3.8-Flash!👀👇
- Blog: qwen.ai/blog?id=qwen3.8-flas…
- Technical Report: github.com/QwenLM/Qwen3.8-Fl…
- Hugging Face: huggingface.co/Qwen/Qwen3.8-…
- ModelScope: modelscope.cn/models/Qwen/Qw…

efimerando retweeted

La pensión media de jubilación acumula un 71,6% de subida real desde 1995. El salario medio, un 8%.
En 1995 la pensión media equivalía al 38% del salario medio anual contando catorce pagas y hoy roza el 60%.
Esa brecha se paga con cotizaciones que salen de unos salarios que llevan tres décadas planos en términos reales.
