




We studied Claude, GPT, Gemini, GLM, Kimi, DeepSeek and LongCat on 36 AI R&D tasks, looking beyond final scores to how they research.
Takeaway: agents act more like engineering optimizers than autonomous researchers. Only 3 of 252 best solutions were novel.
arxiv.org/abs/2608.13417
#SelfEvolving #AutoResearch #AIResearch


An agent runs experiments for hours and improves a score. But did it actually do research, or just optimize?
We evaluate 7 frontier models on 36 long-horizon tasks, looking beyond outcomes into process, experience, novelty, and harness effects.
arxiv.org/abs/2608.13417

AI may not be reliable enough to review papers, but it is increasingly good at checking code.
Code agents could make academic artifacts genuinely testable: does the code run, do results reproduce, and does the implementation match the method?
That could be a real boost for #reproducibility.
1
79
🚀 Our paper “Fine-Tuning Done Right in Model Editing” is accepted to @iclr_conf 2026! Huge congrats to @10k_miles_yang
Fine-tuning is NOT weak for model editing. The pipeline was suboptimal. Implementation matters more than we thought.
We show that standard breadth-first fine-tuning + localized tuning beats SOTA, scales to 100K edits and 72B models.
📄 Paper: arxiv.org/abs/2509.22072
💻 Code: github.com/WanliYoung/FT4Edi…
#ModelEditing #KnowledgeEditing #finetuning #ICLR2026


This is @10k_miles_yang’s 4th paper so far, in his 2nd year of PhD. Really impressive progress.
89
📢 Excited to present our EMNLP 2025 paper “Too Consistent to Detect: A Study of Self-Consistent Errors in LLMs”!
🗓 Wed, Nov 5 · 16:30–18:00
📍 Hall C
#EMNLP2025 #LLMs #AISafety #Hallucination #Uncertainty

2
3
487
🎉 Our paper "AuditAgent: LLM Agent for Risks Auditing in Recommender Systems" has been accepted to the AAAI 2026 Demo Track!
AuditAgent uses LLM-powered GUI agents to audit platforms for filter bubbles, unfairness, and data misuse.
#AAAI2026 #LLM #guiagent #algorithm_auditing #GUIAgent
THX for sharing our work!😀

Another great @GoogleDeepMind paper.
Shows how to speed up LLM agents while cutting cost and keeping answers unchanged.
30% lower total cost and 60% less wasted cost at comparable acceleration.
Agents plan step by step, so each call waits for the previous one, which drags latency.
Speculative planning fixes that by having a cheap draft agent guess next steps while a stronger agent checks them in parallel.
Fixed guess lengths backfire, small guesses barely help, big guesses waste tokens when a check disagrees.
Dynamic Speculative Planning learns how far to guess, then stops early to avoid wasted calls.
A tiny online predictor learns how many steps will be right using reinforcement learning.
1 knob lets teams bias for speed or cost, either by skewing training or adding a small offset.
If a guess is wrong, extra threads stop and execution resumes from the verified step.
Across OpenAGI and TravelPlanner, the dynamic policy matches the fastest fixed policy while spending fewer tokens
The result is clear, faster responses, lower bills, and 0 loss in task quality.

105
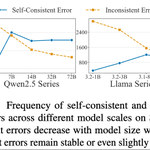
If you sample an LLM 15× and get the same answer, should you trust it? 🚨Not always!
⚠️ Consistency ≠ correctness.
🚫Scaling doesn’t help: self-consistent errors stay stable—or even increase—in larger models.
Our #EMNLP25 main paper (Too Consistent to Detect: A Study of Self-Consistent Errors in LLMs) formalizes self-consistent errors, shows mainstream detectors miss them, and introduces a simple cross-model probe that consistently improves AUROC across datasets and model families.
preprint: arxiv.org/abs/2505.17656
#Hallucination #LLM_uncertainty #HallucinationDetection #LLM

4
354
📍 Find us at ACL 2025 – Hall 5X, Poster #83
🌐 More details & resources: yangwl.site/revisit-editing-…
See you there!
#ACL2025 #ModelEditing #KnowledgeEditing

🛑 Stop using teacher forcing to evaluate model editing!
Our ACL 2025 poster shows why past evaluations mislead progress & how to test editing in the wild.
📍 July 30, 11:00 AM – come chat!
#ModelEditing #LLM #ACL2025NLP

4
304
🛑 Stop using teacher forcing to evaluate model editing!
Our ACL 2025 poster shows why past evaluations mislead progress & how to test editing in the wild.
📍 July 30, 11:00 AM – come chat!
#ModelEditing #LLM #ACL2025NLP

🎉 Excited to share that our work "The Mirage of Model Editing" has been accepted as a main conference paper at #ACL2025! Many thanks to my supervisor @fei__sun, our collaborators, and special thanks to @HuaWenyue31539 for insightful discussions!

Great post! Thanks for featuring the figure from our #ACL2025 paper “The Mirage of Model Editing.”arxiv.org/abs/2502.11177 Glad to see the community's attention to evaluation challenges in knowledge editing. #LLMs #ModelEditing #KnowledgeEditing

🚨 New Blog Drop!
🚀 "Reflection on Knowledge Editing: Charting the Next Steps" is live!
💡 Ever wondered why knowledge editing in LLMs still feels more like a lab experiment than a real-world solution? In this post, we dive deep into where the research is thriving — and where it's falling short. From foundational breakthroughs to the practical roadblocks no one’s talking about, we connect the dots and propose what’s needed to move forward. Join the conversation! #KnowledgeEditing #LLMs #AI #ModelEditing
📌 If you're working on LLMs, model updates, or mechanism interpretability, you don’t want to miss this.
👉 Read the full post: yyzcowtodd.cn/rethinkedit
Key insights from our analysis:
0⃣ Current evaluation metrics and benchmarks inadequately assess knowledge updates in LRMs, highlighting the need for more comprehensive evaluation frameworks.
1⃣ Scaling challenges persist, with significant memory and computational constraints limiting the practical application of editing methods for larger or quantized local models.
🎁 Resource Release: To support the research community, we release covariance matrices for Qwen2.5-32B & QwQ-32B models for the current locate-and-edit methods.
2⃣ We outline promising research directions for developing language models that can effectively learn, adapt, and evolve their knowledge base.
Huge thanks to the brilliant collaborators who made this deep dive into #ModelEditing possible! @uclanlp @CanyuChen3 @Jiachen_Gu @dsmall2apple1 @ManlingLi_ @VioletNPeng
1
2
371


Your evaluation of model editing might be wrong !! Great work! 🎉 @aclmeeting #ACL2025 (main) #ModelEditing

Congrats! answer for our acl paper aclanthology.org/2024.findin…
🎉 Thrilled to share that our paper "The Fall of ROME: Understanding the Collapse of LLMs in Model Editing", has been accepted at Findings of #EMNLP2024! Many thanks to my supervisor @fei__sun and our collaborators @xinyuma8!
📑 Paper: arxiv.org/abs/2406.11263

3
110
semanticscholar.org/venue?na… 挺好玩,可以指定年份区间,看paper impact/citation rank,也可以看看自己的paper,在历史上的位置😂

2
89
Congrats to @HexiangTan ! The camera-ready version is on the way, which has undergone heavy revision.

🎉 Thrilled to share our latest work accepted at #ACL2024 with @fei__sun! We delve into how LLMs merge generated and retrieved contexts in open-domain QA tasks.
📄 Read our full paper here: arxiv.org/pdf/2401.11911
1
3
272
Glad to share that our paper “LoRec: Combating Poisons with Large Language Model for Robust Sequential Recommendation” has been accepted to #SIGIR2024 as a full paper! joint work w/ @KaikeZhang99 and at al. Hope to see you guys in DC! arXiv version: arxiv.org/abs/2401.17723

Excited to share that TEA is is accepted to #CVPR2024 . preprint version: arxiv.org/abs/2402.15390v1 and the code github.com/yuanyige/tea
4
387