

Xinyu Ma retweeted

Agentic-R: Learning to Retrieve for Agentic Search
@liwnhn964157 et al. at Baidu present a retriever training framework for agentic search that uses both local relevance and global answer correctness to measure passage utility
📝arxiv.org/abs/2601.11888
👨🏽💻github.com/8421BCD/Agentic-R

Agentic Search in the context of Agent、AI Search and Chatbot. Check out our new paper

Happy to share our new work "Agentic-R: Learning to Retrieve for Agentic Search"!
We propose a retriever training framework tailored for agentic search and our retriever Agentic-R outperforms existing SOTA retrievers such as BGE, E5, REPLUG...
Paper link: arxiv.org/pdf/2601.11888
1
49
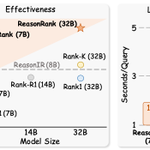
Excited to share ReasonRank—a listwise reranker that reasons before it ranks.
On complex queries, ReasonRank-32B is #1 on the BRIGHT reasoning-intensive leaderboard (Aug 9, 2025; +.6 vs. strong baselines).
Working with Wenhan, @sunweiwei12, etc.


Code, models, and data are fully open-source.
Github : github.com/8421BCD/ReasonRan…
Huggingface paper: huggingface.co/papers/2508.0…
Models: huggingface.co/liuwenhan/rea…, huggingface.co/liuwenhan/rea…
Datasets: huggingface.co/datasets/liuw…, huggingface.co/datasets/liuw…, huggingface.co/datasets/liuw…



Xinyu Ma retweeted
Towards AI Search Paradigm
Baidu presents a comprehensive blueprint for next-generation search systems using four LLM-powered agents that dynamically adapt to query complexity for multi-step reasoning tasks.
📝arxiv.org/abs/2506.17188
Xinyu Ma retweeted
Improving RAG through Multi-Agent RL
This work treats RAG as a multi-agent cooperative task to improve answer generation quality.
It models RAG components like query rewriting, document selection, and answer generation as reinforcement learning agents working together toward generating accurate answers.
Applies Multi-Agent Proximal Policy Optimization (MAPPO) to jointly optimize all agents with a shared reward based on answer quality.
Besides improvements on popular benchmarks, the framework shows strong generalization capabilities in out-of-domain scenarios and maintains effectiveness across different RAG system configurations.

Xinyu Ma retweeted
Sliding Windows Are Not the End: Exploring Full Ranking with Long-Context Large Language Models
Baidu presents a study on leveraging long-context LLMs for passage ranking, demonstrating superior performance and efficiency.
📝arxiv.org/abs/2412.14574
👨🏽💻github.com/8421BCD/fullrank

Xinyu Ma retweeted

NeurIPS acknowledges that the cultural generalization made by the keynote speaker today reinforces implicit biases by making generalisations about Chinese scholars. This is not what NeurIPS stands for. NeurIPS is dedicated to being a safe space for all of us. We want to address the comment made during the invited talk this afternoon, as it is something that NeurIPS does not condone and it doesn't align with our code of conduct. We are addressing this issue with the speaker directly.
NeurIPS is dedicated to being a diverse and inclusive place where everyone is treated equally.
Xinyu Ma retweeted

#EMNLP2024 Best Paper 4/5: Pretraining Data Detection for Large Language Models: A Divergence-based Calibration Method

Xinyu Ma retweeted

I will be presenting our paper “MAIR: A Massive Benchmark for Evaluating Instructed Retrieval” at #EMNLP2024!
Date: Tuesday, Nov 12
Time: 14:00-15:30
Session 03: Resources and Evaluation 1
Paper: arxiv.org/abs/2410.10127
See you there!

💡Check MAIR at #EMNLP2024 A large-scale IR benchmark!
Highlights:
- Task Diversity: 126 realistic tasks, 8x than BEIR 📈
- Domain Coverage: 6 domains and heterogeneous sources 📚
- Instruction Following: 805 relevance criterions
- Lightweight & Fast: optimized data sampling ⚡️

Xinyu Ma retweeted

@sunweiwei12 will present our work about a massive benchmark for evaluating instructed retrieval at #EMNLP2024, joint work with Baidu search team @lingyongyan @xinyuma8 @Yiding_tanh @yindawei @Zhengliang_Shi
💡Check MAIR at #EMNLP2024 A large-scale IR benchmark!
Highlights:
- Task Diversity: 126 realistic tasks, 8x than BEIR 📈
- Domain Coverage: 6 domains and heterogeneous sources 📚
- Instruction Following: 805 relevance criterions
- Lightweight & Fast: optimized data sampling ⚡️
Xinyu Ma retweeted

🎉 Thrilled to share that our paper "The Fall of ROME: Understanding the Collapse of LLMs in Model Editing", has been accepted at Findings of #EMNLP2024! Many thanks to my supervisor @fei__sun and our collaborators @xinyuma8!
📑 Paper: arxiv.org/abs/2406.11263

Xinyu Ma retweeted
🥳 Excited to share that our work on "🦋🌪️ The Butterfly Effect of Model Editing" has been accepted as a Findings paper at #ACL2024! Many thanks to my supervisor @fei__sun and our collaborators @xinyuma8!
📖Paper: arxiv.org/pdf/2402.09656
💻Web page: yangwl.site/collapse-in-mode…

Xinyu Ma retweeted

Glad to share that our paper “Denoising Diffusion Recommender Model” has been accepted to #SIGIR2024 as a full paper! Many thanks to my collaborators @Wenjie_SG, yiyan, teng, fuli and @ChuaTatseng. Hope to see you guys in DC!
Xinyu Ma retweeted

Considering how popular RAG is, LLMs are quite underutilized. In most systems, they’re really only used for generation.
Can we get out-of-the-box ChatGPT to perform advanced retrieval tasks like reranking?
We’ve fiddled around with this but it hasn’t worked quite well. That’s when we came across the RankGPT paper (@sunweiwei12 et al.), which shows that with some prompt tweaking you can actually outperform existing approaches.
@Haotianzh implemented this as a @llama_index module so you can start using it today!
Notebook: github.com/run-llama/llama_i…
Source paper: arxiv.org/abs/2304.09542
Repo: github.com/sunnweiwei/RankGP…


RankGPT (by @sunweiwei12 et al.) is one of the first papers we’ve seen that uses out-of-the-box LLMs (gpt-3.5, gpt-4) to effectively rank documents 💫 - beating monoBERT + Cohere rerank.
This means it’s great as a second stage pass, to filter through documents selected through first-stage vector retrieval.
Thanks to @Haotianzh, we’ve implemented it as a core @llama_index module. This also allows you to plug in any LLM, not just @OpenAI! We have an example with @ollama below:
Notebook: github.com/run-llama/llama_i…
In the case where the retrieved context exceeds the LLM context window, the authors implement a sliding window strategy to progressively rerank a window of chunks.
Check out the original paper here: arxiv.org/abs/2304.09542

Thrilled to know our paper “Is ChatGPT Good at Search? Investigating Large Language Models as Re-Ranking Agents” won the outstanding paper award of #EMNLP2023 !

#LLM4ranking #LLM4IR- the most effective zero-shot method of utilizing LLM4ranking: permutation generation (*listwise*) arxiv.org/abs/2304.09542- the most efficient zero-shot method of utilizing LLM4ranking: instruction distillation (*pointwise*) arxiv.org/pdf/2311.01555.pdf
1
8
811
Xinyu Ma retweeted
#EMNLP2023 Oral presentation on December 08 at 17:00
📌 Ballroom West 1
📄 Is ChatGPT Good at Search? Investigating Large Language Models as Re-Ranking Agents
🔗 Paper link: arxiv.org/abs/2304.09542
🔗 Code link: github.com/sunnweiwei/RankGP…
🤝 Please feel free to join us!
