



Depressing thought: What if the massive capital and compute of the AI buildout is just used to fund a permanent cybersecurity offense versus defense war without improving applications for users?
If you are considering going you can register at sreday.com/2026-san-francisc… and get half off with code SRE50

People using AI agents to negotiate prices will be in for a shock when a customer service bot does adversarial upsells.
"Claude: did you lower my car payment $20 for more tokens by taking a 10yr loan at 20%?"
"Two mistakes here and one I should be honest about.."
As a Michigan fan, I have to applaud OpenAI's Navier-Stokes solution for stealing the win in a competition they had no right to be in.
Here's what I've been working on the past few weeks. @fidian. Benchmarking is hard, expect mistakes along the way. xitter.cf/fidian/status/20926243…

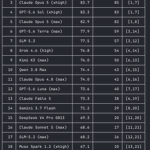
Newly released models repeatedly appear near the top on the @terminalbench 2.1 leaderboard. Are these models actually on par with frontier models on terminal tasks?
We took the top 20 models from that leaderboard and ran them on TB-fn. TB-fn reworks the same 89 tasks by adding steps, tightening requirements, or requiring more complex algorithms. It also removes opportunities for shortcut solutions and ensures verifiers check only the intended criteria.
Models that clustered together on TB-2.1 spread across more tiers on TB-fn. That leaves GPT-5.6 Sol and Opus 5 in the lead, while some others drop significantly in performance. At the same time, models work 38% harder on average in TB-fn, leading to a redrawn Pareto frontier of performance vs. cost.
The full post includes interactive figures showing how the gap for open-weight families widens. It also measures how security refusals affect scores across Anthropic, Google, and OpenAI models. Fable 5 stands out, refusing at least once on 13 of the 89 TB-fn tasks.
Trump went to Netanyahu and asked if he should attack Iran. Netanyahu said "if you attack Iran, then a great empire will fall", and here we are.
hubt retweeted

fuuuuuuuck, whatever undergrad research assistant submitted this summary of their team's paper to phys,org, they knocked the headline out the goddamn park


As importantly, if you really want HA, test your architecture for failover. Flip your primary and secondary sites and back and forth regularly. It's expensive and time consuming, but anything less and you won't really know if your application can survive.
I am annoyed that the AWS Well Architected framework pushes users to the multi-zone design. It's bound to end badly, though I'm sure it is great for AWS margins. status.cloud.google.com/inci…
