

Sports bettor? More like sports worsor amirite? I like to build math models for sports betting. Fan of the Manul, or Pallas cat, a small East Asian wildcat
Joined March 2025
- Tweets1.5K
- Following902
- Followers676
- Likes2.2K





LOL’ing at people who only run 10,000 simulations of their betting models. Why not run 100,000? How about 1,000,000,000,000,000,000,000,000,000,000,000,000,000 simulations? More runs more accuracy babey


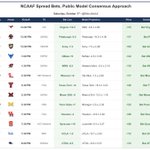
6-7 last weekend, 68-62-3 (-1.4u) overall. I think the stuff I changed going into this year does not work as well as how I did things last year. So I'm moving back towards my prior method, we'll see how this goes
Today's bets (1u to win on bets, 0.5u to win on leans)


I used to think this. But the reality is that every model consists of (1) the data used and (2) the framework/hypothesis implemented
Running a simple regression on public data probably won’t work nowadays, but there are infinite ways of looking at the same data to derive an edge


You guys remember how much time we used to spend aligning all the versions of team names across different databases?


