

Assistant Prof @CornellECE and cofounder/Chief Science Officer at @makora_ai. You can find me more on LinkedIn these days.
NYC
Joined March 2009
- Tweets650
- Following626
- Followers1.7K
- Likes480


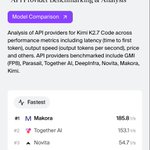



We can run @Meta Muse Spark Open faster than anyone else on @makora_ai cc @alexandr_wang
See more on @ArtificialAnlys: artificialanalysis.ai/models…

Mohamed Abdelfattah retweeted

First Blogpost!
Late stage patching full-attention transformers to Gated DeltaNets (GDN)
Can we convert off-the-shelf pretrained full-attention transformers into hybrid Gated DeltaNets (GDN) without sacrificing long-context performance?
Existing distillation baselines restore Common Sense Reasoning (CSR). Some of them also recover a non-zero long-context retrieval but score 0 on long-context reasoning benchmarks like AIME without expensive continual pretraining.
Introducing OPAL — On-Policy Attention Linearization 🚀
Our initial results show that, using just 3B training tokens, we can convert MiMo-7B-RL-0530 into a 3:1 GDN-to-full-attention hybrid while recovering up to 93% of its long-context reasoning performance and 100% of its long-context retrieval performance, evaluated at context lengths of up to 32K tokens.
hunchings.github.io/late-sta…

Mohamed Abdelfattah retweeted

We are LIVE on OpenRouter. Come and get it!

New inference provider: @makora_ai is now live on OpenRouter.
Starting with:
• DeepSeek V4 Flash
• GLM 5.2 FP8
• GLM 5.2 NVFP4
• Kimi K3
Route through Makora:
openrouter.ai/provider/makor…

Mohamed Abdelfattah retweeted
@fintables gives investors the financial analysis tools to make faster, better-informed decisions. When investors are moving quickly, every second counts.

In this new blog post from @makora_ai, we outline how they improved the performance of Qwen and Gemma models on Amazon Web Services (AWS) Trainium2 chips by up to 6X!
We implemented multiple custom kernels using the NKI (AWS' Neuron Kernel Interface) SDK to either enable faster performance directly, to enable algorithms like speculative decoding, or to explore more efficient model sharding strategies on Trainium2 hardware. This led to design points that are cost competitive on inference performance with highly optimized NVIDIA H100 GPUs.
Blog: lnkd.in/gDMZRxDa
I made a photo dump of the past few years @cornell_tech on our group's research website. Fond memories! abdelfattah-lab.github.io/ga…
[Also just procrastinating my NeurIPS meta-reviews. I'll get back to that now!]

Mohamed Abdelfattah retweeted
Makora 💙 Infron

We're excited to welcome @makora_ai to Infron 🎉!
Makora automatically writes and tunes GPU kernels, so the same open model serves faster. On Artificial Analysis for DeepSeek V4 Flash, it's the #1 provider for output speed of all 6 benchmarked providers, about 2x DeepSeek's own endpoint, and the lowest latency too. Live on Infron: DeepSeek V4 Flash and GLM 5.2.
Try them: infron.ai/provider/makora
Benchmark: artificialanalysis.ai/models…

Mohamed Abdelfattah retweeted

We're excited to welcome @makora_ai to Infron 🎉!
Makora automatically writes and tunes GPU kernels, so the same open model serves faster. On Artificial Analysis for DeepSeek V4 Flash, it's the #1 provider for output speed of all 6 benchmarked providers, about 2x DeepSeek's own endpoint, and the lowest latency too. Live on Infron: DeepSeek V4 Flash and GLM 5.2.
Try them: infron.ai/provider/makora
Benchmark: artificialanalysis.ai/models…
Mohamed Abdelfattah retweeted

M13 co @makora_ai is building AI-native infrastructure that automates AI kernel generation and tuning, helping developers deploy models faster, with better price-performance across NVIDIA, AMD, and custom accelerators.
When we invested in Makora’s seed round last year, M13 partner @kalomarNYC shared, “In a world dominated and monopolized by one brand, it’s such a clear opportunity to give developers, and the market as a whole, the ability to abstract away from hardware and build a high-performing outcome. If you're going to back a team to build something this technically advanced, this is the team to do it with.”
Founders @wAIeedatallah, @mohsaied, and Lukasz Dudziak are continuing to build their vision of AI performance engineering. Check out their manifesto from Mohamed: makora.com/blog/performance-…

A few weeks ago, I put together our thoughts at @makora_ai, on how we are bringing autonomy to AI performance engineering to enable both higher performance, and a much faster time to get there.
Blog: makora.com/blog/performance-…
Video: m.youtube.com/watch?v=C136wo…


Mohamed Abdelfattah retweeted

🎯 AI agents need memory to write GPU kernels, but too much context crowds out the local evidence they need to search.
[ADRS Blog #23] We feature work from Makora on the problem of balancing memory and other knowledge sources for GPU kernel generation agents. Memory helps GPU kernel agents only when it saves more search than it costs in context. Search discovers useful coding patterns, and memory prevents rediscovering them.
✍️ Read the blog:
📖 ADRS Blog Series: ucbskyadrs.github.io/blog/ma…
📄 ADRS Paper: arxiv.org/abs/2510.06189
👩💻 ADRS Code: github.com/UCB-ADRS/ADRS

Mohamed Abdelfattah retweeted

Sequential Monte Carlo speculative decoding from @makora_ai keeps multiple draft tokens alive in parallel instead of rewinding failed matches.
DeepSeek V4 Flash, the top model on @OpenRouter, gets about 80 tok/s on their platform. On @makora_ai, you can get 200 tok/s.
We’ve officially launched our own inference endpoints, and our mission to maximize performance is just getting started. See for yourself in the recording below and at app.makora.com!
Thanks to MakoraGenerate and MakoraOptimize, we’ve automated kernel optimization and inference server tuning. These agents iterate and optimize faster than any human team could, squeezing every drop of latency out of the stack.
We’re making our @deepseek_ai V4 Flash endpoint completely FREE for your first 7 days. Try it here: app.makora.com
Catch my talk tomorrow at the Frontiers of AI summit to hear @makora_ai latest updates, and our new product launch!

On my way to @MLSysConf in Bellevue, Washington! Also looking forward to my visit to the @UW afterwards to talk about extreme codesign for efficient AI.
DMs open! I'd love to meet people interested in AI efficiency to chat about @makora_ai -- we have an exciting product that pushes the envelope on efficient tokens in the works!
Also check out Yilong's sparsespec paper in the Thursday morning session. An amazing collaboration with many research groups!

Very excited about our new work SMC-SD! @yemara22 thread describes how we got to the FASTEST Llama-70b implementation on H100.

We made LLM inference a lot faster.
1/n
Speculative decoding throws away draft tokens when they don't match. What if you re-weighted your samples instead using importance sampling?
We introduce SMC-SD, sequential Monte Carlo speculative decoding, an approximate sampler that speeds up inference by 2.36× over SOTA speculative decoding, while producing a controllable Pareto frontier of speed and approximation accuracy.
ArXiv: arxiv.org/abs/2604.15672
minimal repo release: github.com/abdelfattah-lab/s…
Joint work with Mauricio Barba da Costa (@mauricio_b25181), Chi-Chih Chang (@CCCCC1009CCC ), Cameron Freer, Tim Vieira (@xtimv), Ryan Cotterell, and Mohamed Abdelfattah (@mohsaied).