

CEO @Ligandal 🧬: Tissue-specific targeting with AI + peptides (LigandForge). On a mission to enable precision personalized predictive medicine. Forbes 30U30.
NYC
Joined March 2016
- Tweets11.4K
- Following8.8K
- Followers9.4K
- Likes13.7K



Pinned Tweet
You can design the next Ozempic for free on challenge.ligandai.com and get your designs submitted for wet lab validation via the @adaptyvbio x @AnthropicAI @proteinbase competition.
We’ve also launched a new classifier that predicts signaling state of GPCRs based on folded structures. Get more than a binder - this competition will measure signaling and activity of the GLP1R.
Live and free to try on challenge.ligandai.com


We are giving away 1 MILLION LigandForge designs as part of the Adaptyv Proteinbase + Anthropic protein design competition.
challenge.ligandai.com

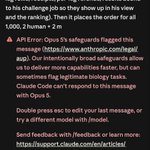
Love this competition, but @AnthropicAI, are y’all aware that your models give [bio] classifier rejections to users trying to run your models for your own competition?
The only way we’ve been able to even query through this is with open models and @OpenAI

Announcing Challenge 2 of the Anthropic x Adaptyv Protein Design Competition!
Humira, the best-selling drug ever, blocks TNF-α, an inflammation marker protein that’s overexpressed in rheumatoid arthritis and Crohn’s disease. In this challenge, the goal is to make a better binder for TNF-α that also releases selectively at pH 6.0 in the endosome of cells to improve drug half-life.
The protein must also bind both human and mouse TNF-α, making it easier to test the same design in preclinical models.
The community will get to vote on which targets we should go after!
openlabs.bio.xyz/post/4e3c96… #openlabs

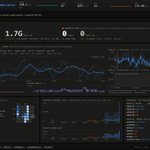
1.7 billion tokens processed (10.5M output) in 24h on a single RTX PRO 6000. Local intelligence has reached a point of being an actual production flow, not a toy. Opus 4.6 Max level intelligence, with additional intelligence served by Opus 5.5/5 & GPT Astra & local as workhorse.

As frontier models get nerfed for bio tasks, being able to run locally is increasingly important.
Run Qwen 3.8 Flash-Next at up to 400k context and peak single-stream output of 180.5 tok/s on an RTX PRO 6000 Max-Q.
This is now my daily workhorse. See below 👇
Update 2:
xitter.cf/nanogenomic/status/210…

