

PhD student @Oxford and very slow ultrarunner :)
Oxford/Malta
Joined April 2023
- Tweets57
- Following90
- Followers168
- Likes87
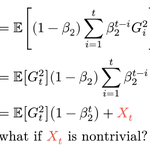




Jason Rader retweeted

Looking forward to presenting this work at #NeurIPS2024 !
Come find us on Thursday from 11-2 @ West Ballroom A-D #6907

Want to know why Mamba beats other state-space models—and where it falls short?
Then check out our #NeurIPS 2024 paper: "Theoretical Foundations of Deep Selective State-Space Models."
🔗 Read the paper: arxiv.org/abs/2402.19047 💻 Access the code: github.com/Benjamin-Walker/s…
🧵1/6

I am genuinely interested! Empirical research around how well our ad-hoc estimates (of gradients, variances, and Fisher information for example) perform is surprisingly limited, since it needs to be constantly reevaluated as SOTA changes
Should we be trying to detect distribution shift and correct it (eg. by taking more samples at the same set of parameters)? Does this matter in some models and not others?
The exponential decay mollifies the severity of distribution shifts, even sudden ones, over many iterations. But what nature do we expect this distribution shift to take?
Adam depends on the gradient distribution during training, which, as far as I know, we don't understand well?
Here, adapted from the Adam paper, v_t is the var estimate, G_t is the gradient r.v. and X_t is an error r.v. for distribution shift.

Jason Rader retweeted

My first PhD paper!🎉We learn *diffusion* models for code generation that learn to directly *edit* syntax trees of programs. The result is a system that can incrementally write code, see the execution output, and debug it. 🧵1/n
Garner's usage dictionary calls these needless variants. Usage dictionaries outside of professional editing seem somewhat rare, but would be very useful in technical disciplines (if unrealistic to make.)
Probably not. I've generally found custom kernels to be less necessary when using JAX due to compilation (the benefit may be marginal compared to PyTorch.)
Cool stuff! Went ahead and implemented it in JAX as well using Optimistix:
github.com/packquickly/sched…
Screw it, here's a new JAX implementation in Optimsitix:
github.com/packquickly/sched…

Schedule-Free paper is up!
arxiv.org/abs/2405.15682
Joint work with collaborators @alicey_ang @HarshMeh1a @konstmish @akhaledv2 @AshokCutkosky
We have some strong small-scale experiments on Transformers, comparing to chinchilla-style cosine 10x reduction schedules.

Neat! Heuristics based on this crop up in stochastic optimisation. Often in the argument of stepsize * sum/sqrt(squared_sum) being "roughly" bounded by stepsize. Of course the independent and symmetric assumptions are both violated but that never stopped anyone...
Jason Rader retweeted

Jasmin Paris @JasminKParis finished loop five of the #BM100 in 59:58:21.
Ultimately I think the question is "who do we want getting into wser?" Optimising the lottery is not the hard part, it's agreeing on who we should be optimising for that is.
Finally, a million thanks to @PatrickKidger, who supervised this whole project.
If you’re following me, chances are good you already follow him. If not, go give him a follow! (right after installing Lineax of course 😉)
4/4
The paper describes out how we achieved many of these things (such as differentiation through all our solvers,) and outlines some of the design choices we made when creating Lineax.
arxiv.org/abs/2311.17283
Lineax offers numerous features over core JAX, such as:
* stable gradients through least-squares solves;
* compile times nearly twice as fast for iterative solvers;
* a consistent API;
* PyTree-valued vectors & operators;
* structured matrices;
* new solvers;
and more! 💥
⭐ Lineax is now on arXiv! ⭐
If you’re doing linear solves or linear least-squares in JAX, give it a shot today!
Lineax
is fast ⚡️,
has new solvers (eg. QR, tridiagonal),
supports general linear Operators.
github: github.com/google/lineax
arXiv: arxiv.org/abs/2311.17283
1/n

They mentioned the choice between these two model functions made little difference in practice.
While this is believable, and indeed proved to be true, it struck me as an example of a claim which is very difficult to verify using existing optimisation software.
12/12