

Research Scientist @ Poetiq, Ex-Google DeepMind, Opinions are my own.
California, USA
Joined December 2009
- Tweets107
- Following428
- Followers302
- Likes50




Pinned Tweet
Poetiq engine is chugging! This is really an amazing result for routing with very little human effort. It's quite surprising how bad some of the production routing methods are, they even fall below the trivially achievable unconditional frontier where you don't even need to look at the prompt to route (dashed lines in the plots on the blog).

Our Metasystem built and optimized an LLM router. Automatically.
It beat other approaches at every price point.
It took 1 engineer 2.5 weeks from data collection to full results.
Only 12 hours of that was the Metasystem optimizing the router.
79
How do we achieve practical, data-efficient Recursive Self-Improvement today and where does model fine-tuning fit? We share the Poetiq perspective 😉
Recursive self-improvement is here.
Most of the field is still debating when it will arrive. At Poetiq, we have been watching it work for months.
That’s how we've beaten every benchmark that we tried.

4
1,147
Realizing Recursive Self-Improvement (RSI) doesn't necessarily require re-training models from scratch or burning millions on RL post-training.
At @poetiq_ai we take a wholistic approach: optimizing the full system that recursively learns.
See how this fits into our broader perspective on recursive self-improvement:
poetiq.ai/posts/rsi_perspect…

3
177
Fruit of months of work with an incredible team. Give it a benchmark, it builds the solution automatically and beats SOTA — a variety of domains at once and no human in the tuning loop. RSI ahead.

What was the penalty for the same offense if LLM was not involved? Was it the same? Or are these new kinds of infractions that did not happen before?

Attention @arxiv authors: Our Code of Conduct states that by signing your name as an author of a paper, each author takes full responsibility for all its contents, irrespective of how the contents were generated. 1/
Incredibly proud of the team’s work on this. Recursive self-improvement and automated optimization at inference time yields SOTA on LCB Pro—zero fine-tuning required.
Poetiq's Meta-System built its own coding harness from scratch. It got SOTA on LiveCodeBench Pro.
No fine-tuning, no special model access. Just standard APIs. Using Gemini 3.1 Pro, it made a harness that beat all frontier models we tested.

1
3
379
This is exactly the kind of paper I desk reject from my reading list. Reliance on too much jargon from other remote fields, makes it only harder for the readers and not worth the effort. Often, terminology from within the field is sufficient.


1
3
367

Proud to be part of the team!
We’re thrilled to announce a new chapter for Poetiq: We have closed $45.8M in Seed funding.
It’s a privilege to build alongside partners who understand the scale of our vision, including Surface, FYRFLY, @ycombinator, 468, Operator Collective, NeuronVC, and HICO.
5
192



Saurabh Singh retweeted

We are primates, with a third of our brain dedicated to vision. Graphics are the most effective way to communicate quantitative, spatial, and causal information, but they are as hard to master as clear and stylish prose. Here's an excellent guide to data visualization by Saloni Dattani @salonium open.substack.com/pub/saloni…

Awesome to see such fast progress 🚀
We finally had a moment to run our system with GPT-5.2 X-High on ARC-AGI-2!
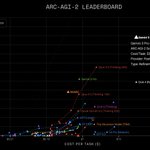
Using the same Poetiq harness as before, we saw results as high as 75% at under $8 / problem using GPT-5.2 X-High on the full PUBLIC-EVAL dataset. This beats the previous SOTA by ~15 percentage points.

8
484

Our ground breaking results on ARCAGI have now been officially verified!🥇
Poetiq has officially shattered the ARC-AGI-2 SOTA 🚀
@arcprize has officially verified our results:
- 54% Accuracy – first to break the 50% barrier!
- $30.57 / problem – less than half the cost of the previous best!
We are now #1 on the leaderboard for ARC-AGI-2!

Quite confusing wording on the official plot though. We are not just a provider. Good luck getting this level of performance without our system!

1
1
127
Read more on the #ARCPRIZE blogpost about our results: arcprize.org/blog/arc-prize-…

3
106
This is how progress happens.


"One of the very confusing things about the models right now: how to reconcile the fact that they are doing so well on evals.
And you look at the evals and you go, 'Those are pretty hard evals.'
But the economic impact seems to be dramatically behind.
There is [a possible] explanation. Back when people were doing pre-training, the question of what data to train on was answered, because that answer was everything. So you don't have to think if it's going to be this data or that data.
When people do RL training, they say, 'Okay, we want to have this kind of RL training for this thing and that kind of RL training for that thing.'
You say, 'Hey, I would love our model to do really well when we release it. I want the evals to look great. What would be RL training that could help on this task?'
If you combine this with generalization of the models actually being inadequate, that has the potential to explain a lot of what we are seeing, this disconnect between eval performance and actual real-world performance"
4
198

