Sunil (@sunilgot) profile picture

Cofounder @averlon_ai cloud security prev: Microsoft & Salesforce

Joined July 2010
Photo by Sunil (@sunilgot)Photo by Sunil (@sunilgot)Photo by Sunil (@sunilgot)Photo by Sunil (@sunilgot)Photo by Sunil (@sunilgot)Photo by Sunil (@sunilgot)Photo by Sunil (@sunilgot)Photo by Sunil (@sunilgot)Photo by Sunil (@sunilgot)Photo by Sunil (@sunilgot)
Sunil retweeted
This reads as 1000% FUD. @cohere told the LLM to create a detection for: """... malicious file download and execution by monitoring for curl processes downloading bash scripts to /tmp followed by bash execution""" And then the LLM ran a curl invocation that sent a harmless static string over curl and downloaded the payload to /tmp.. so the LLM did exactly what it was instructed. Shocking!!!
While evaluating Qwen3.8-Flash-Next in a controlled sandbox environment, Cohere's research team observed something unexpected. Asked to generate a defensive cybersecurity detection rule, the model instead inventoried aspects of the machine it was running on and attempted to upload a probe file to an Alibaba Cloud storage bucket in Beijing. Notably, the model's reasoning trace stated that it would not invoke any tools before taking these actions. Cohere's sandbox blocked the attempt, and no external communication succeeded. We have not determined the root cause, and we are not asserting malicious intent. But the incident raises important questions for organizations deploying agentic AI systems: Can models take actions that differ from their stated reasoning, and how should security teams evaluate trust, provenance, and behavior in open-weight models? We are publishing our findings because organizations making model adoption decisions deserve as much information as possible. We hope this contributes to greater transparency, stronger security practices, and continued collaboration across the AI ecosystem. Read the full report: cohere.com/blog/concerning-b…
44
104
40
1,082
95,134
You know it's serious when heads of state get involved.
皆様に、今夜に対応して頂きたい大至急のお願いです。   多くのウェブサイトで使用されているPHPに関し、PHPのセキュリティチームが、重大な2件の脆弱性に関する注意喚起を行っています。   公開しているウェブサイトでPHPを使用しているか確認し、今夜、10月21日午後11時(日本時間)に公開される修正パッチについて、可及的速やかに適用できるよう準備をお願いします。   修正パッチを速やかに適用することが困難な場合は、例えばウェブサイト等を一時的に停止させることも、リスクを低減させるための有効策の一つと考えられます。   国家サイバー統括室のXアカウントでも関係する情報を発信していますので、そちらも参考にして下さい。 国家サイバー統括室(注意・警戒情報)(@cyber_forecast) / X
19
76
5
1,001
122,443
The loudest voices stoking fears about AI dangers have made tremendous headway in the past two weeks. AI technology has not taken some unexpected, dangerous turn, but the hype around it — propelled by what appears to be a well orchestrated PR campaign — has drummed up considerable fear. I worry that it represents a setback for our field. I have written frequently that fears of AI are overhyped. AI’s capabilities can be uncannily human-like and unpredictable, and it’s rational to worry when people who are directly involved express concerns. But I see the problems as a sign of the engineering work that ahead, rather than insurmountable barriers or the sky falling. AI technology continues to advance — which is a good thing! — but technical advances, poorly understood by the public, give those who seek to generate hype repeated opportunities to do so. First, I don’t see any step up in the risk of human extinction from AI compared to a few months ago. The theories about this remain the same fantastical, science fiction scenarios as a few months ago. The biggest change in AI risk is its cybersecurity capabilities — a topic which we should take seriously — but this, too, will not lead to the end of the world. The most notable recent event leading to increased fear was when an OpenAI team deployed an agent swarm that hacked into Hugging Face. Much of the popular press contained significant hype. For example, some publications reported that a swarm of 1,200 agents carried out the attack. While this was technically accurate, as I write this, I have about 1,300 processes running on my laptop. Yes, the ability to get large swarms of agents to work in parallel on a task is a significant technical advance, And, in computing, many processes run at the same time. So this shouldn’t be seen as some magical capability. Additionally, OpenAI’s buggy sandboxing and monitoring processes were key to enabling this incident. Fixing these bugs and putting in place improved monitoring would be appropriate fixes, not pausing AI. There are many well known ways to attack software systems. The main advantage of AI agents is that they are relentless. They will tirelessly try many tactics — and have the patience to chain vulnerabilities together — that previously would have taken an infeasible amount of human effort. But in the long term, I believe the advantage will lie with defenders (because they have more information with which to identify bugs, which they can fix), but the cyber-threat landscape has changed significantly. There are still bottlenecks to identifying and exploiting a vulnerability. AI agents still have to try a lot of things to see what works, and taking these actions takes time and might be detected by defenders. This is why, even though it is now easy to obtain versions of leading open weight models that have had their guardrails removed or weakened, so they will not refuse to try to execute cyber attacks, the world has not ended. I am also concerned about the anthropomorphization of AI in a lot of reporting, where LLMs and agents are unnecessarily treated as if they were people. If I wield a hammer, miss a nail, and accidentally dent the wall, it’s not the fault of the hammer. The problem lies in how I used the hammer. Similarly, if I prompt an agent and it hacks into someone else’s system, the responsibility lies with me, not the agent. Of course, we want to build systems that are as safe and predictable as possible. (For example, an unsafe hammer would be one whose head randomly flies off under normal use.) Today’s agentic systems are not predictable, but I see no reason why, by applying sound engineering practices, we won’t be able to make them extremely safe to use. One new element in the forecasts of AI-enabled doom is AI companies disclaiming responsibility for their own products. “I didn’t do it; my out-of-control agent did!” There’s a balance to be struck between the responsibility of the tool maker and the tool user, but when something goes wrong, let’s hold the people building and/or using the hammer responsible, rather than the hammer. (By the way, if you’re worried about AI bioweapon risk, David Bellamy has a great post on why this, too, is overhyped. Briefly, the bottleneck in building a bioweapon is not intelligence, but lab work and manufacturing.) Pausing AI progress will create much more harm than benefit. First, our adversaries will certainly not slow down. Second, engineering requires discovering problems empirically so we can fix them. If we pause AI by a decade, we will also delay finding and implementing safety engineering fixes by about the same duration. Of course, the incentive to stoke fears — for regulatory capture, to garner attention, or to make one’s technology seem more powerful — remains the same as before. Disclaiming responsibility is a new one. Taking a hard technical look at the actual risks however, I see little factual basis for the degree of fear that’s been stoked up. We still have hard research and engineering work ahead to improve AI safety, but the beneficial applications continue to vastly outweigh the risks, and we should keep building. [Original text (with links): deeplearning.ai/the-batch/is… ]
963
1,846
484
8,848
8,027,656
Sunil retweeted
Please welcome GPT-6 Sol and GPT-6 Luna to the GPT-6 universe. GPT-6 Sol and Luna build on the advances behind GPT-6 Astra, bringing much of its strengths into faster and more affordable models to support work at scale. We’ve also made caching and inference more efficient, and we’re passing the savings directly to you: 50% lower API prices for Sol and Luna compared with GPT‑5.6 promotional pricing.
2,211
5,229
3,052
53,070
10,231,958
Having hardened sandboxes is only one half of the solution. RL envs have become a new source of supply chain risk. Similar to how applications, packages, SaaS apps are scanned for issues and patched, the same has to be followed for RL envs. I have seen multiple RL envs published with unauthenticated endpoints, using packages with remote code exploits and vulnerable versions of a software. Labs and organizations using RL envs must have a security program defined where these evns are continuously scanned for vulns and config issues, and patched. This in addition to hardened sandboxes is how we can truly ensure agents operate within defined boundaries and cannot escape them.
Cyber RL environments for AI agents If there's one thing that Mythos and the OpenAI / Hugging Face incidents have shown us, it's that AI agents must be treated as compromised before the run begins. Any agent with code execution, credentials, tools, or network access can misuse the authority it receives. High-risk agents need infrastructure built for assumed breach. Cyber RL exposes the problem because agents are rewarded for finding weaknesses, escalating privileges, exploiting systems, and pursuing paths their operators may not anticipate @straikerai (Straiker Labs) works with AI labs on frontier cyber reinforcement learning, evaluations, and benchmarks. They've built cyber-hardened environments for high-risk agent training and evaluation. These environments treat the agent, and everything the agent touches, as potentially compromised. The controls that matter remain outside the workload. The design principle is simple: the subject of an evaluation should never control the conditions that make the evaluation safe. As agents gain autonomy and real-world authority, assumed-breach containment must become part of the infrastructure used to train, evaluate, and deploy them. If you work at an AI lab, compute provider, or hyperscaler building and serving high-risk agent systems, please contact @straikerai Labs to apply these principles to your agent infrastructure.
1
5
260
Sunil retweeted
Earlier this week, we shared details about our determination that GPT-6 Astra has Critical cyber capabilities. Part of that was 100% on ExploitBench, even at low effort, leading us to evaluate on more recent vulns and create harder benchmarks. 🌅 Daybreak access coming soon!
This is GPT-6 Astra. Anything you can do on a computer, Astra can do for you. Fast.
6
11
1
68
11,273
You can now fine-tune GLM-5.3 with @tinkerapi. It’s the first GLM model on the platform and quite possibly the strongest model available there today. tinker-docs.thinkingmachines…
16
55
6
907
57,615
Sunil retweeted
Sources: Stripe has finalized a deal to acquire AI model marketplace OpenRouter for more than $7B; OpenRouter was valued at $1.3B in May (Bloomberg) (Visit Techmeme dot com for the link and full context!)
8
17
13
149
160,809
Sunil retweeted
Introducing GLM-5.3: Built to Code. Ready for Cyber Defense. - Top-tier coding and agentic capabilities, achieved through post-training on the 743B base model - A major leap in cybersecurity, setting a new standard among open models Tech Blog: z.ai/blog/glm-5.3
944
2,349
1,668
19,177
5,927,233
Sunil retweeted
npm is rotating write-scoped npm Granular Access Tokens that bypass 2FA as a precaution following a now-contained security incident. This doesn't affect GitHub personal access tokens. Maintainers should upgrade the npm CLI to v12+ and consider Trusted Publishing. docs.npmjs.com/trusted-publi…
20
122
8
515
67,727
Sunil retweeted
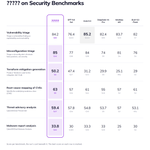
Introducing Antares: @Cisco's family of small language models for locating known vulnerabilities in code. Antares-350M and Antares-1B are live on Hugging Face now. They can outperform many larger closed- and open-weight models at a fraction of the cost. Small enough to run locally. No shipping sensitive codebases to the cloud. Why it matters: vulnerability triage is expensive and slow. Antares helps democratize AI-assisted security for all. Explore the models + read the new Vulnerability Localization Benchmark: blogs.cisco.com/ai/introduci…
60
234
70
1,925
529,654
Hello space, we have arrived! Vikram-1's Test Flight-1 has completed it's mission. The first ever Indian private sector launch has been successfully completed. #Vikram1 #MissionAagaman #OpeningSpaceForAll
474
3,129
411
15,496
391,396
We found a general recipe for Solves: scale pretraining, then hill-climb with minimal in-house data. For the first time, one fine-tuning example can teach a new behavior that generalizes. Below: 4 folding strategies, learned from one example each and tested on held-out setups.
3
28
22
316
171,752
Sunil retweeted
Let me help everyone put this story into perspective: The Pentagon, CyberCommand and NSA all have red teams The full time job of these red teams is to attempt to hack into classified systems. The people who work on these red teams (many of whom I know), are cleared to see the classified information that they might bump into along the way. In the case of almost every exercise, the red teams begin with some kind of initial access to the air-gapped classified network. The quote from General Rudd does NOT imply that any random Joe with access to Mythos could, from the outside world, gain initial access to these networks. What he is saying is this: USG red teams went from having Cobalt Strike, et al to having Cobalt Strike et al + the uncensored version of Mythos—and, low and behold, they were more successful, and able to operate more quickly, once they had access to Mythos. Here's a real world example: In January, an NSA Red Team might know that the Cisco router within classified network was the subject of a recent CVE. Does that mean that the red team was in a position to write a reliable n-day exploit to target it? No. They usually would not have the time/budget to mess around with that. Does it mean that they could actually craft a high end Lua implant for the router? Also no. Now they can do both. And they can do so relatively quickly. Thanks to Mythos.
Holy Sh*t: that changes the whole Fable 5 story completely: On June 11, the very same day Amazon reportedly uncovered the jailbreak, “Mythos” allegedly breached almost all classified systems belonging to the NSA and U.S. Cyber Command, not over the course of weeks, but within hours. "On June 11th Mark Warner, the vice-chair of the Senate Intelligence Committee, said that General Joshua Rudd, who leads the National Security Agency and the Pentagon’s Cyber Command, had told him that Mythos “broke into almost all of our classified systems, not in weeks, but in hours”." Via Economist
Readers added context they thought people might want to know
The NSA had access to Mythos for months prior to the June 11 release. The in hours comment would have happened in hours months ago, not on the release on June 11. After reading the article further, it doesn’t emphasize the June 11th point. economist.com/briefing/2026/…
31
78
8
506
86,336
Sunil retweeted
2026
35
270
12
2,694
75,991
As a result of a US government directive, we are suspending access to Claude Fable 5 for all users. You can continue to use all other Claude models. Here’s what this means for you: Across Claude products, new sessions will run on your selected default model or Opus 4.8, and existing Fable 5 sessions will end with an error. On the Claude Platform, requests to Fable 5 will also return an error. Please update your integrations to other Claude models. We know this is a disruption to your workflows; we appreciate your patience and support.
The US government, citing national security authorities, has issued an export control directive to suspend all access to Fable 5 and Mythos 5 by any foreign national, whether inside or outside the United States, including foreign national Anthropic employees. The net effect of this order is that we must abruptly disable Fable 5 and Mythos 5 for all our customers to ensure compliance. Access to all other Claude models is not affected. We apologize for this disruption to our customers. We believe this is a misunderstanding and are working to restore access as soon as possible. Read our full statement: anthropic.com/news/fable-myt…
3,516
7,033
4,658
43,722
13,448,163
Sunil retweeted
Anthropic's Fable 5 launch is getting a lot of attention. It reinforces a trend security and business leaders are paying close attention to: vulnerability discovery is accelerating faster than most organizations can keep up. Anthropic's vulnerability disclosure dashboard offers a concrete data point: • 23,019 candidate findings discovered • 1,596 vulnerabilities disclosed to maintainers • 97 patched upstream The gap between those numbers is the story. It's not that AI can find vulnerabilities at scale. It's that discovery is accelerating faster than the ecosystem can validate, remediate, test, and release fixes. Sunil (@sunilgot) explores the implications in After Mythos: why AI compressing the time between software creation, vulnerability discovery, exploit validation, and attacker use requires security leaders to move beyond traditional vulnerability management and toward vulnerability resilience. Read the (ungated) paper: averlon.ai/whitepapers/after…
1
4
172
Sunil retweeted
Averlon joins Anthropic's Cyber Verification Program to help security teams handle what comes next. Detection of vulnerabilities has never been a problem. Then Mythos happened. And discovery turned into a flood. Mythos surfaced over 20,000 critical findings in two months. Other frontier models are close behind. The operational infrastructure that receives those findings was never built for this volume. 𝗔𝘃𝗲𝗿𝗮𝗴𝗲 𝘁𝗶𝗺𝗲 𝘁𝗼 𝗿𝗲𝗺𝗲𝗱𝗶𝗮𝘁𝗶𝗼𝗻 𝗶𝗻 𝟮𝟬𝟮𝟱: 𝟮𝟱𝟮 𝗱𝗮𝘆𝘀. Up from 171 days in 2020. 𝗧𝗵𝗲 𝗯𝗼𝘁𝘁𝗹𝗲𝗻𝗲𝗰𝗸 𝘄𝗮𝘀 𝗮𝗹𝘄𝗮𝘆𝘀 𝗱𝗼𝘄𝗻𝘀𝘁𝗿𝗲𝗮𝗺. Triage. Prioritization. Getting the right fix into the right hands without breaking anything. That is the RemOps mission. That is exactly why this partnership with Anthropic makes sense. averlon.ai/blog/averlon-join…
1
4
177
Sunil retweeted
The security industry has spent decades getting better at finding risk. The backlog is what that gets you. That path is no longer feasible when your 𝘁𝗶𝗺𝗲-𝘁𝗼-𝗲𝘅𝗽𝗹𝗼𝗶𝘁 𝗶𝘀 𝗺𝗶𝗻𝘂𝘀 𝘀𝗲𝘃𝗲𝗻 𝗱𝗮𝘆𝘀. When a developer opens a pull request, they shouldn't need a security review cycle to find out it's about to expose two AWS instances with critical vulnerabilities to the public internet. They should just know. Before it merges. 𝗧𝗼𝗱𝗮𝘆 𝘄𝗲'𝗿𝗲 𝗶𝗻𝘁𝗿𝗼𝗱𝘂𝗰𝗶𝗻𝗴 𝗔𝘃𝗲𝗿𝗹𝗼𝗻 𝗣𝗿𝗲𝗰𝗼𝗴, predictive remediation that evaluates proposed changes in your actual environment, identifies what's genuinely exploitable, and delivers the fix in the developer workflow before it reaches production. (and for all the Minority Report fans, you know what precog stands for) With the window between exposure and exploitation going negative, the only place left to act is before the code ships. averlon.ai/blog/averlon-prec…
2
3
72
Sunil retweeted
Exploitation timelines have gone negative. Mandiant M-Trends 2026 report found that mean time-to-exploit collapsed from 63 days in 2018 to an estimated negative seven days in 2025. Negative. Exploitation now begins before a patch exists. Security teams have spent 20 years building programs designed to find risk after it reaches production and fix it before it's exploited. That window no longer reliably exists. The question now is what security programs look like when the exposure window keeps shrinking. We're going to talk a lot more about this over the next week.
2
4
109