

Private local AI server for small businesses: your data stays inside your company. Founder @ClaryelCom.
Como, Italy
Joined December 2011
- Tweets3.8K
- Following886
- Followers487
- Likes9.1K





🚀 MixAI: I’m Choosing a Mix of Local and Cloud AI — Here’s Why. (1/2)
Almost a year of hands-on experiments. Hardware ranging from $500 to $15,000. Cloud APIs, AI agents, and real-world tasks for businesses and homes. From now on, I’ll be sharing more about this combined approach to AI — one I believe has a very promising future.
Things are changing almost every day. But AI technology has already reached a point where we can achieve reliable results and realistically plan how to use it over the next year or two.
And I’ve come to a simple conclusion: we don’t need to choose between local and cloud AI. We need to learn how to get the best out of both.
This goes far beyond simply connecting different models or orchestrating them. It’s about planning the entire system: which tasks should run locally, which should go to external models, how to distribute computing resources, which subscriptions make sense, and what hardware is actually worth buying.
We also need to plan our physical infrastructure — computers, servers, GPUs, memory, power consumption, and future expansion.
I believe local AI will become an essential part of our lives. It’s already making its way into smartphones, personal computers, and even experimental operating systems.
⚖️ Four Things That Matter Most
1. Real value. The number one priority is getting useful, practical results.
2. Cost. How much are we actually paying to complete a task — not just for hardware, subscriptions, or tokens?
3. Security. This deserves its own category, outside any ranking. Personal data, privacy, and control over our infrastructure require special attention.
4. Ease of use. How easily, quickly, and reliably can we get the job done?
These are the criteria I use to compare technologies and build my own setup.
☁️ Subscriptions and APIs: Two Worlds Starting to Merge
This is an interesting topic that often gets overlooked.
Cloud AI can be accessed through subscriptions with usage limits or through APIs where you pay for what you actually use.
Each approach has its own economics, limitations, and advantages. And they need to be evaluated separately.
But the line between them is starting to blur.
A recent example is OpenAI. Eligible ChatGPT Pro subscribers can receive $100 to $500 per month in API credits, depending on their subscription tier. These credits require separate activation, and API billing remains separate.
That’s a pretty interesting example of two pricing models coming together.
So I’m not just comparing models. I’m also exploring the economics of subscriptions and APIs, their limitations, and how to combine them efficiently.
➡️ Coming up in Part 2/2: The three areas I’m actively researching, my hardware experiments, AI agents working together, and how I plan to make all this information accessible to you. 🚀


Compact Mini-ITX AI Inference Build — $2,000–2,500 (all new)
(Tomorrow we will test a build with the same GPU + DDR4 for $1,000–1,300)
Tested this compact Mini-ITX AI inference build (all new hardware):
• Intel Core Ultra 7 265
amazon.com/Intel-Core-Deskto…
• ASUS Pro Q870I-C-CSM (Mini-ITX, SO-DIMM)
newegg.com/ (search “ASUS Pro Q870I-C-CSM”)
• Crucial 48 GB DDR5-5600 (2×24 GB) SO-DIMM
amazon.com/Crucial-5600MHz-5…
• ASUS Dual GeForce RTX 3060 12 GB
amazon.com/s?k=asus+dual+rtx…
• Lexar NM1090 PRO 2 TB PCIe 5.0
amazon.com/Lexar-Computing-C…
• SilverStone SST-SG13B case
amazon.com/SilverStone-Techn…
• ASUS Prime 650W Bronze
amazon.com/s?k=ASUS+Prime+65…
• Thermalright AXP120-X67 cooler
amazon.com/Thermalright-AXP1…
• Thermalright HR10 2280 PRO SSD heatsink
amazon.com/Thermalright-HR10…
Complete new build costs $2,000–$2,500.
You can save significantly by choosing used parts or cheaper alternatives.


Vik | Practical AI & Tech retweeted

J’ai l’impression d’avoir un écran dans mon écran c’est de la sorcellerie

The only components I didn’t include in the list are the Wi-Fi module, which plugs into a dedicated slot on the motherboard, the Wi-Fi antennas, and the cables connecting the module to the antennas.
I’ll make a separate post about this, since not everyone needs Wi-Fi. There are very affordable solutions available for this purpose, starting at just $15 (€15).
My particular setup is designed for somewhat more specific purposes, and I’ll explain everything in a separate post.
Compact Mini-ITX AI Inference Build — $2,000–2,500 (all new)
(Tomorrow we will test a build with the same GPU + DDR4 for $1,000–1,300)
Tested this compact Mini-ITX AI inference build (all new hardware):
• Intel Core Ultra 7 265
amazon.com/Intel-Core-Deskto…
• ASUS Pro Q870I-C-CSM (Mini-ITX, SO-DIMM)
newegg.com/ (search “ASUS Pro Q870I-C-CSM”)
• Crucial 48 GB DDR5-5600 (2×24 GB) SO-DIMM
amazon.com/Crucial-5600MHz-5…
• ASUS Dual GeForce RTX 3060 12 GB
amazon.com/s?k=asus+dual+rtx…
• Lexar NM1090 PRO 2 TB PCIe 5.0
amazon.com/Lexar-Computing-C…
• SilverStone SST-SG13B case
amazon.com/SilverStone-Techn…
• ASUS Prime 650W Bronze
amazon.com/s?k=ASUS+Prime+65…
• Thermalright AXP120-X67 cooler
amazon.com/Thermalright-AXP1…
• Thermalright HR10 2280 PRO SSD heatsink
amazon.com/Thermalright-HR10…
Complete new build costs $2,000–$2,500.
You can save significantly by choosing used parts or cheaper alternatives.
🚀 This is incredible!
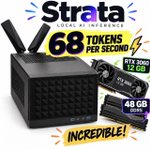
Qwen3.8-Flash-Next IQ3_S (~83.6 GB) running locally on a budget RTX 3060 12 GB with just 48 GB of system RAM!
🔥 Up to 68 tokens/sec decoding, ~916 tokens/sec prompt processing, and a 30K-token prompt processed in just 34 seconds.
Powered by Strata by @coldniko. No cloud inference. Just affordable consumer hardware! 🧠⚡
Full benchmarks, hardware specs, optimizations, and trade-offs below. 🧵👇


Vik | Practical AI & Tech retweeted

Until a few weeks ago my 8GB GPU only ran small models.
Then @coldniko's Strata landed and a 125B Qwen Next suddenly fit on my old RTX 2080. 121K context prefill: ~201 → ~845 tok/s.
Qwen 4 Next is coming next week. Can't wait @Alibaba_Qwen, November is going to be huge for open models and the local community 👇


Level 1 — Local AI Server up to €1,000
I’m building a three-level lineup of local AI servers. Level 1 is a complete, practical entry-level system with a target price of up to €1,000.
You can build a system at this level yourself, even cheaper. What I’m providing is not simply a pile of components, but a tested, prepared and supportable system with a clear path for further development.
👍Hardware
👉CPU: Intel Xeon E5-2690 v4 — 14 cores / 28 threads, up to 3.5 GHz
👉Motherboard: ASUS Z10PA-U8 — Intel C612 server platform, ECC DDR4 RDIMM support, multiple PCIe slots and onboard display output
👉RAM: 64 GB DDR4 ECC RDIMM — 4 × 16 GB, all four memory channels populated
👉GPU: NVIDIA Tesla P100 — 16 GB HBM2
👉NVMe: 1 TB Patriot Viper Gaming VP4300 Lite, PCIe Gen4 ×4, new, installed through a PCIe adapter
👉CPU cooling: Thermalright AXP120-X67 — 6 heat pipes, 120 mm PWM fan, approximately 180 W cooling capacity
👉Case: new, selected partly for its clean appearance
👉Power supply: ASUS Prime 650W 80+ Bronze, new
👉Case airflow: two new quality fans — one intake, one exhaust
👉GPU cooling: dedicated additional airflow for the Tesla P100
👉Recovery USB: 64 GB, permanently installed inside the system, containing tools for recovery, OS installation/reinstallation, software-stack reinstallation and hardware testing.
The principle is simple: save money where it makes sense, but not on cooling, reliability or serviceability.
✌️Why used components?
To stay within €1,000, the CPU, motherboard, RAM and GPU are used/refurbished components, purchased from specialized companies.
After preparation, I assemble each system myself and perform at least 24 hours of intensive testing: full CPU/GPU load, extensive memory testing and stability checks.
The NVMe drive, power supply, case and cooling are new.
👀Software & Performance
The software stack is currently being prepared. The main workload will be AI models running on Strata by @coldniko
Performance is still being tested. Real-world results will determine the minimum configuration and models for Level 1. More about the software and functionality will come in a separate post.
😎Optional Upgrades
When ordering or later, users can add:
internal and external storage;
archiving and backup solutions;
remote server management;
hardware-level management, including BIOS access and system recovery/reinstallation where supported by the configuration;
additional technical-support capabilities.
🤝Warranty & Technical Support
Warranty support will be backed by a technical and financial reserve of tested spare components, primarily GPUs, motherboards, RAM and CPUs.
Other major components are new and will be covered by a combination of supplier warranties and our own warranty.
Technical support will be built around voice agents, chat agents and a website communication agent. They will be able to advise users, diagnose problems and, with the user’s permission, connect remotely to the computer — without access to personal data.
This system is already being tested with real telephone lines and remote computer management. Support will cover not only the hardware, but the entire software stack, including software installed by the user or by our agents at the user’s request.
🚀 Upgrade & Development
Level 1 is a starting point for those who want to try local AI without a large initial investment.
The system can be developed gradually: upgrade the GPU, increase RAM, expand storage or replace individual components — or move completely to a Level 2 or Level 3 system.
The exact development path depends on the user’s requirements.
💵 Price & Scalability
The €1,000 target reflects the current market situation. The price is valid as of publication, based on current supplier prices and available stock.
Current component availability allows this exact configuration to be initially scaled to 10, 100 and potentially even 1,000 systems, subject to changes in pricing and availability.


Absolutely, a DDR4-based build is much more budget-friendly.
I already have a fairly standard DDR4 configuration that I’m testing.
Feel free to ask questions! I can already share specific benchmark results and perhaps even offer some practical recommendations based on my experience. 🔬🚀
No, of course DDR5 is better! DDR4 will likely be slower, but I want to measure the actual difference.
I’ll test the same RTX 3060 12GB in a DDR4-based system in the next few days. The computer is already built — I just need to move the GPU over.
I’ll finish the current tests today and run the DDR4 benchmarks tomorrow or the day after. 🔬🚀
20/12 🧘♂️
🚀 RTX 3060 12GB + Strata + Qwen IQ3_S (83.6GB) — Long-context testing continues!
The first results at 64K and 128K context are surprisingly impressive! 🔬
📊 64K context (65,497 tokens):
• Prefill: 935 tok/s
• Time to first token: 70s
• Decode by interval: 82 → 91 → 94 → 95 → 93 → 93 tok/s
• Median decode: 91 tok/s
✅ No slowdown compared to 16K!
📊 128K context (132,026 tokens):
• Prefill: 888 tok/s
• Time to first token: 149s
• Decode by interval: 81 → 87 → 86 → 87 → 88 → 89 tok/s
• Median decode: 87 tok/s
✅ Only ~4% slower than at 16K!
💡 Streaming the KV cache from pinned system RAM appears remarkably efficient on this configuration.
⚠️ But speed isn’t everything!
The model successfully follows instructions placed at the beginning of these long prompts and produces valid JSON.
However, it fails to retrieve a specific marker from the middle of the document at both 64K and 128K.
Conclusion: Sustained decoding performance remains excellent even at 128K, but reliable information retrieval across long contexts is still a serious challenge.
#LocalAI #Strata #RTX3060 #LLM
🔬 The tests are still ongoing — and I’m expanding both their scope and depth right now!
I’m continuing to publish results in this thread, along with raw log files for anyone who wants to analyze the data independently, including with their own AI agents. 🚀
Unfortunately, models that fit entirely within 12GB of VRAM haven’t delivered particularly impressive results in my tests — neither in quality nor in speed.
That’s why I’m focusing on this much larger model for now. I want to test it extensively across a wide range of real-world tasks to understand how useful and reliable it actually is in practice.
I’ll publish a detailed post about its practical usability much later, once I’ve gathered enough real-world experience. 🔬🚀
teapawt.net/uctive/status/21162179…
19/12 💁
🔬 Why did we test sustained decoding speed at long context lengths?
To find out whether an affordable RTX 3060 12GB can reliably run an 83.6GB Qwen IQ3_S model — not just deliver impressive peak speeds.
🧪 We measured decoding throughout long responses, contexts up to 32K tokens, expert caching, GPU/NVMe activity, and output quality.
📊 Results:
✅ Fast mode sustained high throughput.
⚠️ Precise routing was up to ~4× slower.
⚠️ Repetition and information loss appeared in some long-context tasks.
💡 Speed is already sufficient for many interactive workloads. Reliability remains the challenge.
Next: repeat the tests and explore contexts beyond 32K despite severe RAM/VRAM limits.
We’ll then publish preliminary real-world use cases, routing recommendations, and model loading/reloading performance.
📂 Full methodology, results, failures, and 145 downloadable raw files for independent AI-agent analysis:
claryel.com/local-ai-rtx3060…
The experiments continue! 🚀

Preliminary results are already available, but I’m now expanding the benchmarks to much longer context lengths — all the way up to 256K tokens! 🔬🚀
teapawt.net/uctive/status/21162179…
19/12 💁
🔬 Why did we test sustained decoding speed at long context lengths?
To find out whether an affordable RTX 3060 12GB can reliably run an 83.6GB Qwen IQ3_S model — not just deliver impressive peak speeds.
🧪 We measured decoding throughout long responses, contexts up to 32K tokens, expert caching, GPU/NVMe activity, and output quality.
📊 Results:
✅ Fast mode sustained high throughput.
⚠️ Precise routing was up to ~4× slower.
⚠️ Repetition and information loss appeared in some long-context tasks.
💡 Speed is already sufficient for many interactive workloads. Reliability remains the challenge.
Next: repeat the tests and explore contexts beyond 32K despite severe RAM/VRAM limits.
We’ll then publish preliminary real-world use cases, routing recommendations, and model loading/reloading performance.
📂 Full methodology, results, failures, and 145 downloadable raw files for independent AI-agent analysis:
claryel.com/local-ai-rtx3060…
The experiments continue! 🚀
25 tok/s is already perfectly usable! 😁 The important thing isn’t chasing maximum speed, but getting real value from local AI. That’s exactly what I’m exploring with these experiments. 🚀
19/12 💁
🔬 Why did we test sustained decoding speed at long context lengths?
To find out whether an affordable RTX 3060 12GB can reliably run an 83.6GB Qwen IQ3_S model — not just deliver impressive peak speeds.
🧪 We measured decoding throughout long responses, contexts up to 32K tokens, expert caching, GPU/NVMe activity, and output quality.
📊 Results:
✅ Fast mode sustained high throughput.
⚠️ Precise routing was up to ~4× slower.
⚠️ Repetition and information loss appeared in some long-context tasks.
💡 Speed is already sufficient for many interactive workloads. Reliability remains the challenge.
Next: repeat the tests and explore contexts beyond 32K despite severe RAM/VRAM limits.
We’ll then publish preliminary real-world use cases, routing recommendations, and model loading/reloading performance.
📂 Full methodology, results, failures, and 145 downloadable raw files for independent AI-agent analysis:
claryel.com/local-ai-rtx3060…
The experiments continue! 🚀
On another configuration, I managed to run the model using only half the CPU cores, while leaving virtually all the system RAM free! The speeds were lower, of course.
I’ll continue testing and exploring this setup. Ultimately, my goal is to be able to use this computer for everyday work while running local AI on it at the same time. 🚀
This system costs approximately $2,000–2,500 to build with brand-new components.
Tomorrow, I’ll publish the exact cost of this particular build, down to every single component.
And in the next few days, I’ll test the same RTX 3060 12GB in a $1,000 system. I expect some pretty impressive results there too! 🚀
Feel free to read through the testing methodology while the benchmarks are running. The results are coming soon! 🔬
In the meantime, please let me know what else you’d like me to investigate, measure, or benchmark. I’m happy to pass your suggestions directly to my AI agent! 🚀
teapawt.net/uctive/status/21161949…
🚀 17/12 — We’re still going! 😁 The testing continues!
The community asked an excellent question: can an RTX 3060 12GB sustain ~60–68 tokens/sec when running an 83.6GB Qwen3.8-Flash-Next IQ3_S model with long contexts, or are those just peak numbers?
My AI agent is investigating. Here’s the actual benchmarking methodology. 🔬
1. FIXED TEST ENVIRONMENT
• GPU: RTX 3060 12GB
• RAM: 48GB DDR5
• Model: Qwen3.8-Flash-Next-GSQ-RCO-IQ3_S, 83.6GB
• Engine: Strata 0.1.52, build f-027-rel
• Maximum context: 32,768 tokens
• Prefill: 4096
• Speculative decoding: –spec 4, –spec-min-p 0.5, MTP enabled
• KV cache: INT8, 32K resident
• Resident expert budget: 24 GiB
• Conversation cache: 1536 MiB
• Unbuffered loading enabled
• GPU Unlock: enabled and verified through kernel parameters
Engine version, launch arguments, environment variables, driver, kernel, RAM, VRAM, and swap were recorded before testing.
No software updates, model downloads, configuration changes, or file deletions.
2. MEASURING REAL TOKEN DELIVERY
Instead of trusting the engine’s average tokens/sec, the agent built a custom streaming benchmark.
Every server-sent event records:
• Arrival timestamp in milliseconds
• Content type: reasoning or final answer
• Number of characters received
The exact completion-token count comes from API usage statistics.
Since the server’s /tokenize endpoint returns HTTP 404, token positions are estimated by distributing the reported token count across streamed chunks proportionally to their character lengths.
This reconstructs an approximate token-arrival timeline.
Speed is calculated separately for:
• Tokens 1–500
• 501–1000
• 1001–2000
• 2001–4000
• 4001–6000
• 6001–8000
• Remaining tokens
Validation: one run produced 5,478 chunks for 5,479 generated tokens — almost one chunk per token.
The methodology also tracks the longest pause between chunks and where it occurred.
Client-side measurements are cross-checked against Strata engine logs. Aggregate speed discrepancies are only a few percent or less.
3. REASONING VS FINAL OUTPUT
Reasoning tokens consume the same generation budget as visible output.
In one experiment, a 600-token limit was entirely consumed by reasoning, leaving no final answer.
Therefore, reasoning and answer tokens are tracked separately.
Both configurations are tested:
• Reasoning enabled
• Reasoning disabled
The working methods for disabling reasoning are:
reasoning_effort: “none”
chat_template_kwargs: {“enable_thinking”: false}
Simple thinking:false and /no_think controls did not work in this setup.
4. PRECISE CONTEXT CALIBRATION
The agent generates reproducible prompts using numbered filler statements.
Token cost is calibrated experimentally: approximately 19.7–20.3 tokens per statement, with ~145 tokens of instruction overhead.
Actual context length is verified using usage.prompt_tokens after every run.
Test contexts:
• 1K
• 8K
• 16K
• 24K
• 30K
The output budget is calculated against the 32,768-token context ceiling, including a safety margin.
For example, a 30,151-token prompt permits only about 2,048 generated tokens with ~600 tokens reserved for safety.
So no unrealistic 8K output requests near the context limit.
Each prompt also contains:
• An instruction at the beginning: tag must equal ZQ7-KEEP
• A hidden marker in the middle
• The task at the end
This tests instruction retention and retrieval across long contexts.
Cold prompts contain changing identifiers. Warm-cache pairs are byte-for-byte identical.
…..