

AI-focused CEO, investor, advisor.
Silicon Valley
Joined February 2009
- Tweets2.3K
- Following2K
- Followers5.3K
- Likes1.6K



Pinned Tweet
"In the end, enjoying life's experiences is the only rational thing to do...
You're sitting on a planet spinning around in the middle of absolutely nowhere.
You're floating in empty space in a universe that goes on forever.
If you're going to be here, enjoy the experience." -MS

ALT Quote from "The Untethered Soul" (by Michael Singer)


Uri Pomerantz retweeted

On Anthropic’s first day of trading, the way they handled things was truly disgraceful.
The initial offering price was originally set at $70–$78, but it was raised straight to $83. Not only did they raise the price, but they also increased the number of shares offered from the planned 820 million to 980 million—a jump of nearly 20%.
At least with instant noodles, they usually offer more for the same price—but Anthropic went and did both: increasing the quantity and the price.
Even more outrageous is that on the very first day of trading, management cashed out $2 billion.
Are they really that desperate? They could at least put on a show—don’t rush to cash out right after going public. How are retail investors supposed not to be scared by that?
And that’s not all.
Reportedly, 10% of employee stock options were unlocked on the first day of trading—amounting to approximately 300 million shares, equivalent to nearly one-third of the total offering.
What’s truly hair-raising is the unlocking schedule that follows.
A batch will be unlocked in mid-December, followed by successive unlockings in early, mid, and late January 2027. Throughout the first quarter of 2027, the total volume of shares expected to be unlocked is projected to reach 3 billion.
What does that mean?
The total offering size is only 980 million shares, yet the number of shares set to be unlocked in just one quarter is more than three times that amount.
This isn’t a gradual release of shares—it’s a barrage that leaves no room to catch your breath.
That’s why I said yesterday: I’m staying away from Anthropic stock.
Now that I’ve seen these numbers, I’m even more convinced.
There will be other opportunities to make money; there’s no need to risk my own money on a situation like this.
I’d like to live a few more years.
Uri Pomerantz retweeted
Underrated life advice: The ability to remain unshaken by the minor inconveniences of life puts you ahead of 95% of people. Emotional control is the ultimate power. Few have it. Not every collision or slight deserves your energy. You can just let them float by. It’ll change your life.
Uri Pomerantz retweeted

Anthropic just killed:
> Google Sheets
> Excel
> TLDraw
> Airtable
> Miro
> Excalidraw
> FigJam
> Whimsical
> Lucidchart
> Lucidspark
> Mural
> Tableau
> Looker
> Power BI
> Metabase
> Hex
> Julius
> Mode
> Sigma
> ThoughtSpot
> Omni
> Lightdash
> Preset
> Redash
> Deepnote
> Observable
> Evidence
> Qlik
> Domo
> Rows
> Smartsheet
> Coda
> Notion databases
> Equals
> Causal
> Pigment
> Quadratic
> Sourcetable
> Grist
> Baserow
> NocoDB
> SeaTable
> Stackby
> Zoho Sheet
> Apple Numbers
> LibreOffice Calc
> Datawrapper
> Flourish
> Polymer
> Akkio
> Eraser
> Napkin
> Draw io
> Visio
> Gliffy
> Creately
> Milanote
> Stormboard
> Conceptboard
> Klaxoon
> Heptabase
> Kinopio
> Obsidian Canvas
> Canva Whiteboards
> Microsoft Whiteboard
> Zoom Whiteboard
> Apple Freeform
Everything's totally fine.

There are two kinds of companies now – those that dread every new model release, and those that celebrate it.
The best companies build for a world where each new AI model strengthens the business.
These companies do 5 things:
(1) Truly assess where you are today. Are you getting stronger with every open-source and frontier model release — or weaker? Why?
(2) Understand and strengthen your moat. Use the proprietary data and pipelines you’ve already built to fine-tune and improve on open-source models, and to evaluate which new models can improve your business.
(3) Build a “master brain” model layer you can easily swap out. As new models are released, run internal evals against your current standard (this can happen by business unit). Keep or replace your model (off-the-shelf or fine-tuned) based on the results.
(4) Actively lower your cost profile. Have your master brain orchestrate sub-agents, most of which should run on lower-cost models. Run evals to find where open-source models can do the sub-agent work, and track how this actually impacts your contribution margins.
(5) Measure and improve. Don’t aim for perfection. Aim for measuring often and improving often.
The best companies know where they are, use their proprietary data to strengthen their moat, and actually get excited as the intelligence frontier expands and the open-source cost frontier drops.
1
1
22,368


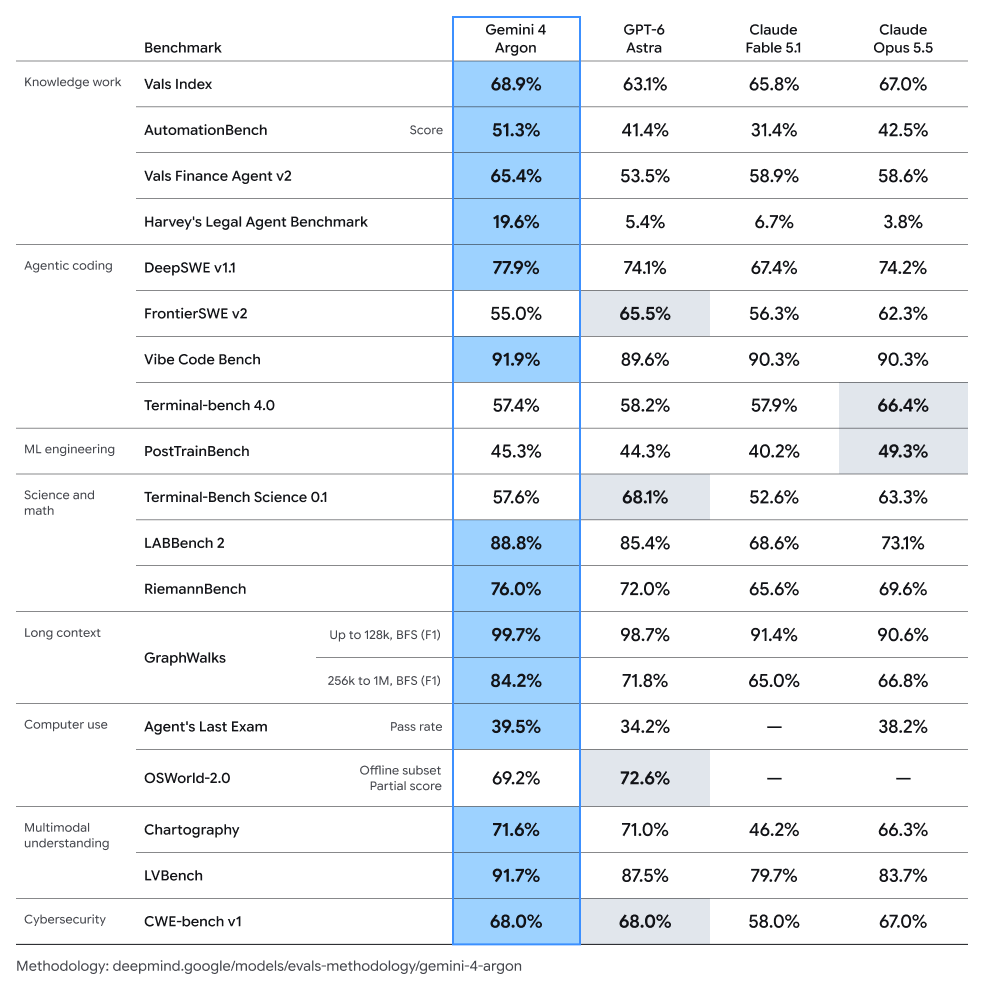
Uri Pomerantz retweeted

Feeling the AGI/ASI, few observations
1. Opus 5.5 really gives strong vibes of AGI (maybe not fully there, but we're very close, like 80%-90%).
For example, few breakthoughs in training humanoids are needed. We need to move this intelligence into physical world.
2. I don't think Anthropic has discovered any magical formula.
3. Which means, SpaceXAI, Google, and others will soon follow. This prediction is based on the amount of compute they already have + additional compute being added all the time.
4. Never was more confident that Anthropic, SpaceXAI, Google, OpenAI, likely Meta, basically all big US AGI labs will have proper AGI in 2027.
5. And from there we'll move quickly to ASI territory (likely also in 2027).
It looks like few GW of compute are enough for strong AGI, now imagine what we will able to do with 10-20GW of compute which are rapidly coming online.
And then with 100GW-200GW...
2027 will be an utterly insane year.
Uri Pomerantz retweeted

The loudest voices stoking fears about AI dangers have made tremendous headway in the past two weeks. AI technology has not taken some unexpected, dangerous turn, but the hype around it — propelled by what appears to be a well orchestrated PR campaign — has drummed up considerable fear. I worry that it represents a setback for our field.
I have written frequently that fears of AI are overhyped. AI’s capabilities can be uncannily human-like and unpredictable, and it’s rational to worry when people who are directly involved express concerns. But I see the problems as a sign of the engineering work that ahead, rather than insurmountable barriers or the sky falling. AI technology continues to advance — which is a good thing! — but technical advances, poorly understood by the public, give those who seek to generate hype repeated opportunities to do so.
First, I don’t see any step up in the risk of human extinction from AI compared to a few months ago. The theories about this remain the same fantastical, science fiction scenarios as a few months ago. The biggest change in AI risk is its cybersecurity capabilities — a topic which we should take seriously — but this, too, will not lead to the end of the world.
The most notable recent event leading to increased fear was when an OpenAI team deployed an agent swarm that hacked into Hugging Face. Much of the popular press contained significant hype. For example, some publications reported that a swarm of 1,200 agents carried out the attack. While this was technically accurate, as I write this, I have about 1,300 processes running on my laptop. Yes, the ability to get large swarms of agents to work in parallel on a task is a significant technical advance, And, in computing, many processes run at the same time. So this shouldn’t be seen as some magical capability.
Additionally, OpenAI’s buggy sandboxing and monitoring processes were key to enabling this incident. Fixing these bugs and putting in place improved monitoring would be appropriate fixes, not pausing AI. There are many well known ways to attack software systems. The main advantage of AI agents is that they are relentless. They will tirelessly try many tactics — and have the patience to chain vulnerabilities together — that previously would have taken an infeasible amount of human effort. But in the long term, I believe the advantage will lie with defenders (because they have more information with which to identify bugs, which they can fix), but the cyber-threat landscape has changed significantly. There are still bottlenecks to identifying and exploiting a vulnerability. AI agents still have to try a lot of things to see what works, and taking these actions takes time and might be detected by defenders. This is why, even though it is now easy to obtain versions of leading open weight models that have had their guardrails removed or weakened, so they will not refuse to try to execute cyber attacks, the world has not ended.
I am also concerned about the anthropomorphization of AI in a lot of reporting, where LLMs and agents are unnecessarily treated as if they were people. If I wield a hammer, miss a nail, and accidentally dent the wall, it’s not the fault of the hammer. The problem lies in how I used the hammer. Similarly, if I prompt an agent and it hacks into someone else’s system, the responsibility lies with me, not the agent.
Of course, we want to build systems that are as safe and predictable as possible. (For example, an unsafe hammer would be one whose head randomly flies off under normal use.) Today’s agentic systems are not predictable, but I see no reason why, by applying sound engineering practices, we won’t be able to make them extremely safe to use. One new element in the forecasts of AI-enabled doom is AI companies disclaiming responsibility for their own products. “I didn’t do it; my out-of-control agent did!” There’s a balance to be struck between the responsibility of the tool maker and the tool user, but when something goes wrong, let’s hold the people building and/or using the hammer responsible, rather than the hammer. (By the way, if you’re worried about AI bioweapon risk, David Bellamy has a great post on why this, too, is overhyped. Briefly, the bottleneck in building a bioweapon is not intelligence, but lab work and manufacturing.)
Pausing AI progress will create much more harm than benefit. First, our adversaries will certainly not slow down. Second, engineering requires discovering problems empirically so we can fix them. If we pause AI by a decade, we will also delay finding and implementing safety engineering fixes by about the same duration.
Of course, the incentive to stoke fears — for regulatory capture, to garner attention, or to make one’s technology seem more powerful — remains the same as before. Disclaiming responsibility is a new one. Taking a hard technical look at the actual risks however, I see little factual basis for the degree of fear that’s been stoked up. We still have hard research and engineering work ahead to improve AI safety, but the beneficial applications continue to vastly outweigh the risks, and we should keep building.
[Original text (with links): deeplearning.ai/the-batch/is… ]

Uri Pomerantz retweeted

The bitter lesson of outbound GTM: improving TOFU is always better than improving conversion.
h/t @samdblond on the @uncapped_pod

Uri Pomerantz retweeted

Imagine telling someone in 1999…
The year is 2026.
The President is Donald Trump in his second non consecutive term.
The richest man in the world is PayPal cofounder Elon Musk… but not because of fintech or Paypal. Because of rockets, electric cars, AI, satellites, brain chips and something called “Boring Company”.
Apple is worth trillions but its main business isn’t computers… its selling glass rectangles everyone stares at for 9 hours a day.
People don’t watch TV. They watch teenagers explain geopolitics, finance, and relationship advice in ~60 second videos.
The biggest taxi company owns no taxis.
The biggest hotel company owns no hotels.
The most powerful media companies are social networks where everyone argues with strangers for free.
Kids are making millions filming themselves playing video games.
AI Robots write emails, code, legal memos, songs, essays, and breakup texts.
The internet is mostly bots arguing with humans who are trying to prove they aren’t bots.
You can summon a car, groceries, a doctor, a date, a private jet, or a dog walker from your phone.
People pay real money for invisible currencies, digital monkeys, AI girlfriends and pictures that disappear after 24 hours.
The richest companies in the world don’t sell oil, steel, or cars. They sell attention, compute, data, and addiction.
And somehow, after all of that everyone is still using Excel.
Uri Pomerantz retweeted

I'm going to say something that everyone else in Silicon Valley is too scared to say:
YC is a giant ripoff.
It's absurd to me that naive Founders give away 7% of their company for just $125k in this day and age.
It's a super boomer offering:
- apply, wait, hope you get in
- thrown into a 300 person cohort where you are one tiny cog in their mass portfolio bet
- 3 months of 'education' that you can now get completely for free online
- A few minutes at the end to hope a VC picks you amidst the cattle room
Was YC worth it 10 years ago when knowledge wasn't freely available and you couldn't build distribution for yourself via the internet? Yes.
Is it worth SEVEN percent of your company in today's age when you can go from $0 to $1M in weeks with just content and AI?
No.
Uri Pomerantz retweeted

Too many AI personal assistants, too little time to assess all of them. Nice work here: assistantbenchmark.com

Uri Pomerantz retweeted
A lot of people are asking how I pulled off these super long-horizon builds with Astra.
Astra is extremely powerful, but by default it struggled with a task this difficult. I tested a bunch of approaches to get past this, and the one I landed on is something I'm calling the Manager Loop.
It's basically a couple of tricks we used to use with much less capable models a couple of years ago, with a few new ideas layered on top. Turns out that when you put those together and apply them to Astra, its ability to do extremely difficult long-horizon tasks goes up dramatically.
Here's how it works:
1. Launch an agent (I'm calling this one the "manager"). Chat with it about what you want to get done, and have it build a massive checklist of to-dos, then break that checklist into phases.
2. The manager then spawns a second Codex agent in a separate thread (the "implementer"). The two agents can message each other.
3. Put the manager in /goal mode, and tell it to run each phase on the implementer in /goal mode.
4. The manager messages the implementer: "/goal Complete phase one completely, extremely well." The implementer doesn't stop until that phase is done, then messages the manager back. The manager tells it to start phase two. They repeat until every phase is finished, completely autonomously.
Why I think this works: over a long-horizon task, Astra tends to asymptote. It gets way further than previous models, but at a certain point it kind of just stops improving against the goal as quickly as it did before. It gets stuck in the minutiae, focusing way too much on small details, and overall progress stalls. The Manager Loop forces it to work piecemeal, one phase at a time. It's essentially how a human would steer a model, except the model is doing the steering for me.
That's actually how this started. I was having the model write the checklist and break it into phases, and then I was doing the manager's job by hand. At some point I thought, "Wait, why can't I just get a separate AI to do this?" That's what unlocked full autonomy, which is super useful.
A wording detail that seemed to matter: I ask for each phase to be done "extremely well," not "perfectly." Maybe I'm reading too much into it, but asking for "perfect" sent the model right back into the minutiae. "Extremely well" implies it's allowed to move on once it's good enough, and that worked better in my testing.
One more trick that I think helps (this one is more of a hunch, but it was useful for me): have the implementer build a simple HTML page with the full checklist on it. The implementer checks boxes off as it goes and updates a counter, and the page has a chart of # of boxes ticked over time.
Obviously the boxes aren't all equal, but it forces the model to notice things like "I haven't made progress in a while, time to move on." You can even put this in the prompt directly, like: "if you haven't ticked a box in X amount of time, move on". That helps a lot.
I also ran 96 sub-agents at a time. You can change this in your Codex config (or just ask Codex to change it).
This got me far better long-horizon performance than anything else I tried. I'll be sharing more in the coming days!

Uri Pomerantz retweeted

Nvidia paid $12.93 billion for Hugging Face. The price is the company's own name, written in Unicode.
Hugging Face is named after the 🤗 emoji. That emoji is Unicode U+1F917. Convert the hex to decimal and you get 129303. The deal closed at $12,930,000,000.
Jensen priced the acquisition at the codepoint.
The deal:
- $12.93B, announced Thursday, confirmed by Nvidia
- Nvidia's second largest acquisition ever, behind the $20B Groq asset deal last year and ahead of Mellanox at $7B in 2019
- Revenue: about $150M annualized, per The Information
- That is roughly 86x sales
- Nvidia's market cap is about $5.5T, so the whole thing costs 0.23% of the company
- Huang says Hugging Face stays open, with no requirement to use Nvidia compute
Who made money:
The cap table is unusually clean. Hugging Face raised about $395M across eight rounds and never raised again after 2023.
- Seed and Series A, 2016 to 2019: tiny valuations. These positions are up several hundred times
- Series B, 2021: about $40M
- Series C, May 2022: $100M at $2B, led by Lux Capital with Sequoia and Coatue. Roughly 6.5x
- Series D, August 2023: $235M at $4.5B, led by Salesforce Ventures with Google, Amazon, Nvidia, Intel, AMD, Qualcomm, IBM. Roughly 2.9x
- Nvidia was already on the cap table from that round, so it marked up its own stake 2.9x before buying the rest
The three founders:
- Clément Delangue, Julien Chaumond, Thomas Wolf. French, founded it in New York in 2016
- Working through the dilution, roughly half of founder ownership survived the capital raises, and a 250 person team implies a 15 to 20% pool
- That puts the three of them somewhere around 33% to 38% combined at exit
- Call it $4.3B to $4.9B between them, roughly $1.5B each, with Delangue likely higher as CEO
- Every number in that paragraph is an estimate. No cap table has been published
Employees:
- Only about 250 people, which is the striking part
- If the pool is 15 to 20%, that is roughly $1.9B to $2.6B across 250 people
- Averaging $8M to $10M per employee, with early engineers far above that
- Compare Anthropic, where roughly 5,000 people share a much larger pie, or Airtable, where the founders split $144M after 13 years
The decision that made it all work:
- Last year Hugging Face rejected a $500M investment from Nvidia at a $7B valuation, per the FT
- By declining, they avoided about 7% dilution and sold the whole company 18 months later at 1.85x that price
- Deal talks only started after another suitor showed acquisition interest, which means the price was competed up
- Bloomberg had reported roughly $14B on Tuesday. It landed at $12.93B, which suggests the codepoint number mattered more than the last hundred million
The context worth keeping:
- Hugging Face called itself the Switzerland of AI. It hosts three million models, including every open Chinese model competing with Nvidia's biggest customers
- Delangue said this month that China is winning the AI race because it embraced open models
- Anthropic and OpenAI are both building their own chips to reduce Nvidia dependence
- So Nvidia just bought the distribution layer for every model that does not belong to them
The frame: a chatbot for teenagers, named after an emoji, rebuilt Google's BERT in PyTorch on a whim in 2018 and accidentally became the front door to open-source AI. Ten years later the most valuable company on earth bought it for the numeric value of that emoji. Roughly $5B to three French founders, $2B or so to 250 employees, and 86x revenue for a business that never needed to raise again.
The tollbooth was undervalued at $4.5B. It just was not undervalued for long.


Uri Pomerantz retweeted

I'm a cardiologist. I've spent twenty years as the person patients trust to interpret their bodies. And I need to tell you something that most physicians won't say out loud:
AI is about to change the power dynamic between you and your doctor. Forever.
Four days ago, OpenAI's o3 model diagnosed 18 children with rare diseases that the best human specialists at Boston Children's Hospital couldn't solve — some after nearly twenty years of searching. Published in the New England Journal of Medicine.
Two weeks ago, WashU researchers proved that nine routine blood markers can calculate your biological age — and predict cancer risk years before any tumor forms. A free calculator. Available to anyone.
Last month, AI-enhanced coronary CT angiography detected inflamed arteries in patients whose standard stress tests said "normal." Patients who would have gone home reassured and wrong.
The pattern is unmistakable. The tools that used to require a specialist, a referral, a three-month wait, and a $400 copay are migrating into your phone, your bloodwork portal, and your own hands.
And I'm watching something in my practice I never expected.
Patients are walking in more informed than some of the residents I trained. They've run their PhenoAge score. They know their ApoB. They've read the study about Lp(a) before I've had time to bring it up. They come with questions so specific that the conversation starts at a level it took me years of training to reach.
This used to threaten physicians. It shouldn't. It should liberate us.
Because here's the truth about the old model: a 15-minute appointment where your doctor runs a basic metabolic panel, glances at the numbers, says "looks fine," and sends you home — that model was never good enough. It was just all we had. It missed 75% of future heart attacks. It caught cancer late. It told women with microvascular disease they had anxiety. It filed children with rare diseases as "unsolvable."
AI doesn't replace the physician. I've said this before and I mean it — the human moment, the clinical judgment, the hand on the shoulder when the diagnosis lands — that's irreplaceable.
But AI does something the old model never could: it gives you the ability to see inside your own biology with a depth and speed that was impossible a decade ago. To track your own numbers. To calculate your own biological age. To bring data to your doctor that elevates the conversation from "am I sick?" to "where exactly am I heading, and what do we do about it?"
The patient who walks in with their ApoB, their Lp(a), their hsCRP, their PhenoAge calculation, and a list of questions from the latest research — that patient doesn't threaten me.
That patient is the easiest person in my practice to keep alive.
Because they've already done the one thing most patients never do: they stopped waiting for permission to understand their own body.
I went into medicine because I wanted to help people live longer. What I've learned is that the patients who live longest are the ones who took ownership — not of my job, but of their own data, their own questions, and their own decisions.
The tools are here. The research is published. The calculators are free. The blood tests cost less than a dinner out.
You don't need to wait for your annual physical to find out what's happening inside you. You don't need permission to understand your own biology. And you don't need to accept "looks fine" from anyone — including me — when the science offers a deeper answer.
The revolution isn't coming. It's in your pocket. In your patient portal. In the published studies you can read yourself.
The only question left is whether you'll use it — or keep waiting for someone to tell you it's time.
Your body. Your data. Your life.
Take ownership. Your future self is counting on it.

Uri Pomerantz retweeted

As engineering, product, design, DS, etc. melt into a new kind of role, I was reflecting on what roles might look like in the future. For example, when I look at the Claude Code team I see what I think is five archetypes:
1. Prototyper: comes up with brand new ideas; churns out many ideas, most of which don't ship
2. Builder: quickly turns a prototype/idea into production-grade product/infra
3. Sweeper: cleans up the UI, simplifies the code and system, unships, optimizes performance
4. Grower: takes a product that has been built and iterates on it to improve Product-Market Fit
5. Maintainer: owns a mature system to make it secure, reliable, fast, and efficient as it scales
Many people span across 2 roles, and sometimes 3 roles. I also notice that these roles are not really tied to job function -- eg. across Anthropic, some designers match category 1, some 2, some 3; same for engineers, PM, DS.
A healthy team needs a mix of these, depending on the product:
- A product that is new and pre-PMF needs people that are strong at 1+2+3
- A product that is growing and has found PMF needs 2+3+4 and some 5
- A product that has strong PMF needs 3+4+5 and some 2
Maybe product roles of the future will look more like this, and less like the domain-specific roles of today?

Uri Pomerantz retweeted
I just got back from SF and I FEEL INSPIRED.
I spent 5 days with frontier AI model teams, AI startup founders, and 3 billionaires.
My takeaways:
1. I had lunch with 3 billionaires. All of them are buying SaaS companies and rebuilding them agent-first. They were deeply inspired by Bending Spoons and Ryan Cohen's eBay deal. Buy the company, cut the headcount, rebuild the tech, add agents, add features, make more valuable experience, raise prices.
2. The frontier model companies are hungry for usage data from the field. They can see API calls and token counts. They can't see the actual workflows. If you're deep in a niche using these models in ways the model companies haven't seen, that understanding is incredibly valuable. Usage intelligence is the new alpha.
3. Consumer AI is massively underbuilt. Every billboard in SF is either B2B inference infrastructure or vertical agent companies. The entire city is optimized for enterprise. Meanwhile you have companies like Cal AI doing $50M ARR in 18 months as a consumer app. I met with a cool few teams doing consumer AI (@paulscherer / @ekuyda)
4. MCP came up in literally every conversation. The companies exposing their product as MCP endpoints are getting pulled into deals they never pitched for. The ones that aren't are becoming invisible to agents. This is the new SEO. If agents can't find you, you don't exist. Building products for agents is the new zeitgeist in general.
5. Not uncommon for hot seed rounds to be $25-50 million valuations. I saw a Series A at $450 million
6. If I had a dollar every time someone mentioned "forward-deployed engineer" this trip I could have funded a seed round. It's the hottest role in SF right now. The person who sits between the agent and the customer, making sure everything actually works.
7. The mood around open source shifted. A year ago it felt like open source was chasing the frontier models. Now founders are telling me Gemma and DeepSeek are good enough for 80% of what they need at a fraction of the cost. The "which model do you use" conversation is being replaced by "which model for which task." Model loyalty kinda feels dead.
8. Voice agents came up more than I expected. Multiple founders told me voice is the interface for the next billion users. The billion people who will never type a prompt will absolutely talk to one.
9. The Obsidian community in SF is weirdly intense. Multiple founders showed me their vaults unprompted. Like showing someone your home gym. It's a flex now. The quality of your knowledge base (second brain?) is becoming a status symbol among builders.
10. Maybe it was just the people I met but the age of the founders is shifting. I met more founders over 40 this trip than any trip before and more founders under age 21 than ever before. Founders getting older and younger at the same time.
11. I spoke to a lot of fast-growing startups, VCs and frontier models who are hiring content creators right now.
12. The restaurant scene in SF is actually better than it's been in years. Founders are going out more. Alcohol is out, not surprisingly.
13. SF doesn't feel like the only place anymore. We all have access to the same frontier models. We all read the same X feed. A founder in NYC or Lagos is calling the same APIs as a founder in SoMa. So in the past it felt like SF was always lightyears ahead, doesn't feel that way anymore. It's okay not to live in SF and have BIG DREAMS.
14. The coworking spaces in SF are half empty but the coffee shops are packed. People want to be around people. I had a few startup ideas here....
15. Walking around the Mission I noticed something: the street-level businesses, the taquerias, the barbershops, the laundromats, none of them use any AI at all.
16. I heard the phrase "agent debt" for the first time. Like technical debt but for agents. When you hack together an agent workflow fast and never clean it up, the system prompts conflict, the memory gets polluted, the tools overlap. 6 months later the agent is doing weird things and nobody knows why lol.
17. Met a few people who carry two phones now. One for personal. One that's basically an agent terminal running Telegram or iMessage connections to their agent fleet.
It's always amazing to get that dose of inspiration in SF. I FEEL INSPIRED.
But I'm so happy to be back home, locked in and building.
We're 12-18 months into a shift that will take 15 years to play out. The urgency in every conversation was real.
What an incredible time to be building.
