

frontier ai research, infrastructure, chips, bio | investing in startups per aspera ad astra ~
blr/ sf
Joined November 2011
- Tweets2.5K
- Following7.3K
- Followers980
- Likes17.9K





Ofcccc

Fable 5.2 is significantly better at chip design, software engineering, biology, and material science.
GDPx is the only eval that test these categories at this level of detail. True experts make these tasks, unlike other benchmarks.
Notably it is not better at finance, legal, quantative trading, RSI, or hardware design.
Anthropic explicitly nerfed this model in RSI tasks and it's interesting seeing that reflected in the score.
231
vansh taneja retweeted

frontier models, with lots of test time compute, are becoming the engine of scientific discovery


vansh taneja retweeted

Can we forecast benchmark accuracy from models that score zero?
We (co-leads @LukeBailey181 @rckpudi) turn a benchmark into a series of easier hinted versions. Jointly modeling scale C and hint level H enables forecasting GSM8K acc (H=0) within 3 pts from 5600x less compute 🧵


hnets!


I've always believed that intelligence should come from simple, general building blocks that learn their own abstractions directly from raw data; in other words, the bitter lesson. I think we're finally seeing a real step towards AI that can learn from all data.
Language modeling on raw bytes is a microcosm of this ideal, and to me it's a central problem in AI: if we can't build LLMs that learn end-to-end from bytes, how will we handle the rest of the world's data that we understand even less?
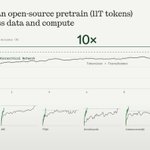
Last year we introduced hierarchical networks (H-Nets) as a first step. Our new version finds up to 3-5x efficiency gains in controlled scaling law experiments, and at larger scale matches an open-source model trained on 11T tokens with ~10x less data and compute. The posts below walk through what we found and why we think it works.
6
320
compression is intelligence...congrats @HessianFree and team!

Today, we’re announcing Ternary Bonsai 2 27B.
Based on Qwen3.8 27B, Bonsai 2 27B is 9x smaller than its full-precision counterpart while retaining 98.2% of its aggregate benchmark performance.
Two months after the first Bonsai 27B release, the biggest change is quality. The footprint remains 5.9 GB, but the gap to full precision has narrowed materially, with particularly strong gains in agentic coding, multimodal reasoning, and long-horizon tool use.
Ternary Bonsai 2 27B is available today under Apache 2.0.

717

super cheap intelligence - take it or leave it
don't ask what goes into it - welcome to the future of intelligence


237


vansh taneja retweeted

Summary of CPO/NPO Market Update
🚀 NVIDIA CPO: Spectrum-X CPO switches for Scale-out are officially in mass production. Our forecasts: 15k units (2026E) & 100k units (2027E).
*Supply Chain: To support the CPO Scale-Out ramp, TSMC has expanded CPO inspection equipment capacity (notably adding Insertion 2/3 capacity), alongside strong progress from key suppliers in FAU, shuffle boxes, and system assembly.
* Scale-Up Architecture: Rubin Ultra is now expected to adopt a 9-18-9 tray design. While mechanical challenges from the 0.75U height could potentially lead to a reversion to a 10-9-8. This shift will have no impact on optical engine (OE).
📈 OE Shipments: NVIDIA platform optical engine (OE) shipments expected at 6m (2027E) & 19m (2028E). Total industry-wide OE hitting 11m & 40m.
☁️ Amazon Trainium 4: AWS projected to consume 5m (2H27E) & 12m (2028E) OE units, primarily 6.4T specs.
* Trainium 4 will likely have 3 configurations, with two expected to adopt NPO.
💡 Key Plays: LITE/COHR (CW laser upside), Browave (10k+ shuffle box per quarter in 4Q26E, followed by acceleration in 1H27E.), SMTC/MRVL (TIA/Driver), TSEM (NPO PIC exposure).
#NVDA #LITE #MRVL #SMTC #TSEM #Browave #CPO #NPO
cue to the physical world

Scoop: Anthropic is in talks to acquire Decart for $6 billion, a rare massive acquisition for the Claude maker & a key development in the race to build more efficient AI infrastructure
w/ @Lynnmdoan, @rngould & @shiringhaffary
bloomberg.com/news/articles/…

1
751