

느긋하게 살면서, 조용히 돈 벌기 시도중 일상 속에서 재밌는 거 찾고 괜찮은 건 계속 해보는 중 개발 · AI · 기술 인사이트 공유 토큰x생각 연금술
대한민국
Joined July 2017
- Tweets17.3K
- Following1.1K
- Followers1.2K
- Likes11.9K





Wonjin retweeted

We're adding a new plugin to Claude Code: You should Know.
It scans Claude's output for important information you might miss to help keep you in the loop.
Enable it with:
/plugin enable cc-plugin-you-should-know@builtin


Wonjin retweeted

NVIDIA open-sourced its own agent skills for Claude Code, Codex and Cursor
391 skills across 47 NVIDIA products, from CUDA and Jetson to robotics, LLM training and RAG.
3.2k stars, Apache 2.0.
Every skill is signed by NVIDIA and ships with a benchmark that runs the same tasks with and without it. On the cuOpt skill, Claude Code goes from 59% to 97%.
Install: npx skills add nvidia/skills


Wonjin retweeted

Cloudflare の意思決定モデル「clef-flesh」をお試し。早速マリオの攻略に成功✌
レイテンシは130ms 程度@ RTX5090
やはりローカルで動かせるのは強い

Cloudflare から Jev API互換性を持つ意思決定モデルがオープンウェイトな公開された。これはぜひ試してみたい...!
公開されたモデルは clef と clef-flash と言うモデルで、それぞれのベースモデルは
clef:Qwen3.8-27B
clef-flash:Qwen3.5-9B
としてファインチューニングされたものとのこと
遅くても良いので精度重視の場合はclef、意思決定の速さ重視の場合はclef-flashが良さそう
huggingface.co/Cloudflare/cl…

Wonjin retweeted
Rejoice!
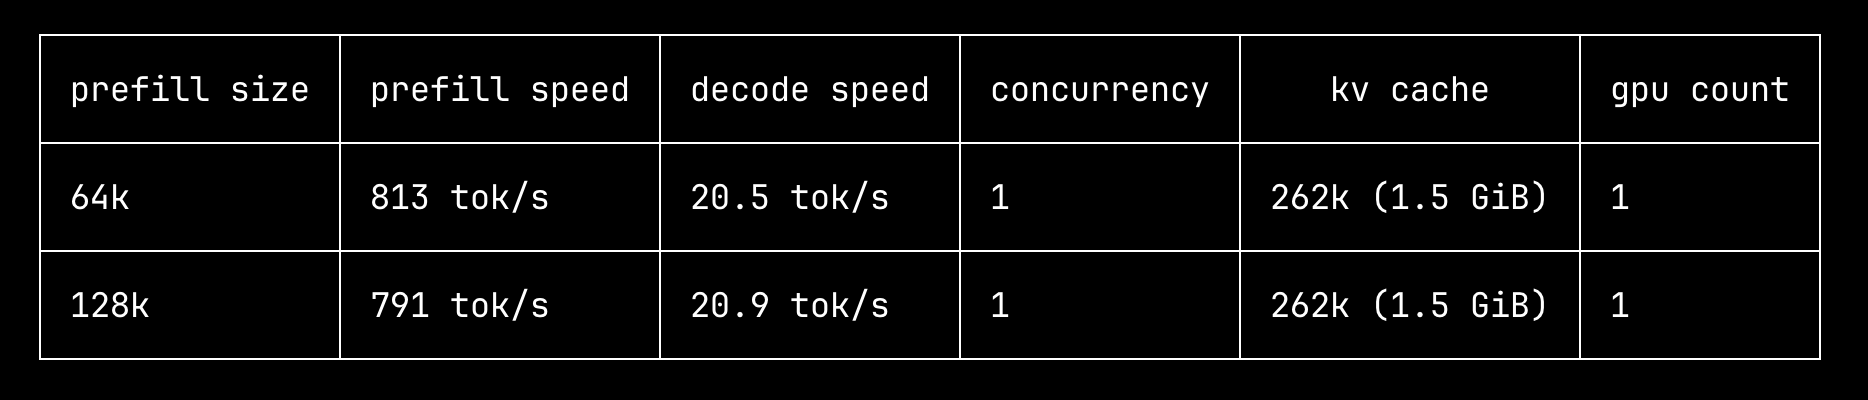
DeeepSeek-v4.1-Flash running on 200GB of NVMe + 400GB of DDR4 + 24GB of VRAM
Caps out at 21 tok/s decode, prefill is 100 tok/s but working on that now
Will have a working image by EOD
In total this deepseek running on 9000$ of hardware, 2 sparks recipe also coming

Wonjin retweeted

Cool eval. Simply ask an LLM “Land or Water?” and give it a latitude and longitude coordinate as text. Ask 16,200 times, plot as image. The models know. From compressing the internet.


Wonjin retweeted
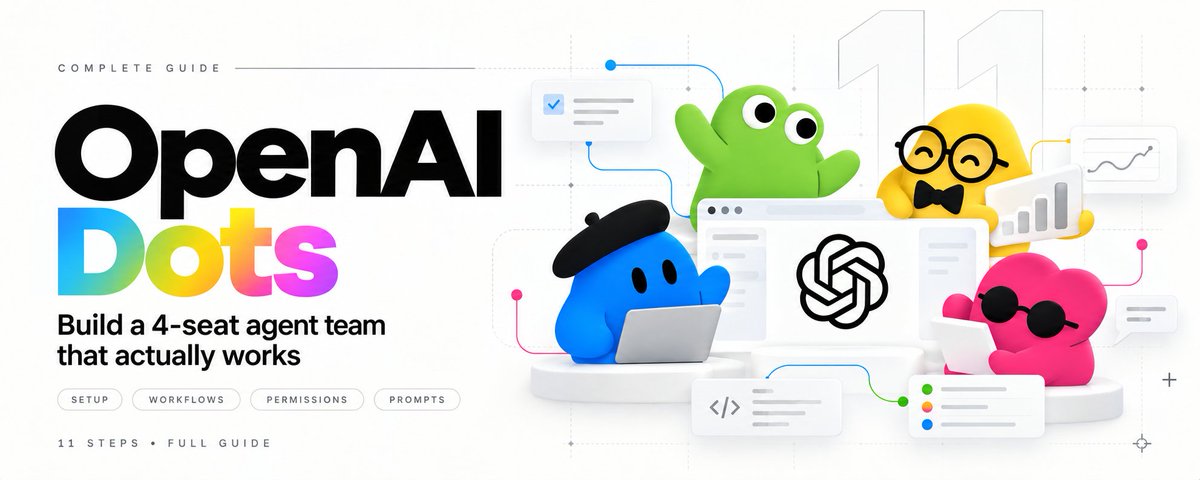
Sam Altman just shared his personal ChatGPT Dots setup
At DevDay, OpenAI introduced dots, always-on agents with their own computer in the cloud. Altman also showed how he already uses one.
Every night the dot reviews everything that came in.
Before the day starts, it pings with anything urgent.
Over time it learns how he likes to work and where his attention should go.
The keynote listed bigger jobs to hand off too:
> monitor bug reports and test fixes in draft PRs
> find what is slowing down your app
> move an app off a legacy API before it shuts down
How to set up the same one is in the image below.


Wonjin retweeted

Qwen3.8-27B from @Alibaba_Qwen on ARC-AGI (Verified):
- ARC-AGI v2: 42.4%, $0.45/task
- ARC-AGI v1: 87.5%, $0.22/task
Qwen's chat template adds guidance for low and xhigh reasoning, but not medium, which may explain why medium used more tokens yet scored below low.

Wonjin retweeted

Lots of you asked for the DGX Spark dashboard, so I tidied it up and put it on github. There's also a small screen version for a Pi 5 with a 1920×480 display. Thanks for all the love!!
github.com/juliankang4/spark…


Wonjin retweeted

We are pleased to present Qwen4 27B Is All You Need.
This work formalizes the LocalAI community’s collective pursuit of locally deployable intelligence.
We thank our collaborators for their rigorous peer review and sustained contributions to determining whether it fits in VRAM.

Wonjin retweeted

if you have a 16gb rtx card in your gaming pc, save this, 4 coding agents at 64k context each is the balance for that card in 2026
> 76 tok/s total mid build at 130 w
> 41 tok/s total, all 4 at 60k deep
> 141 w there, 0.95 kwh per 1m tokens
> 15.6 of 16 gb vram, mtp head on
> one llama.cpp server, -np 4
bonsai 2 27b fits its full 262k window on a 16gb card, 4 agents split it into 64k each, and hermes agent won't start below 64k, so a 5th agent at 52k is out and 4 is the most that card runs
the serve script for your card from my repo plus -np 4 is the whole setup. if the card also drives your monitor, start with 2 agents, CTX=131072 and -np 2
the chart is the power side on my 5060 ti, tokens per watt from one fresh request to all 4 agents 60k deep and the full 262k window


your rtx 5060 ti 16gb can run 4 autonomous coding agents at once
> 76 tok/s total, 17 to 21 tok/s each
> 4 hermes agents, building 4 games in parallel
> 64k context per agent
> 67 tok/s single stream with mtp
> 15.6 of 16 gb vram, 130 w
> bonsai 2 27b ternary, 5.95 gb
> one llama.cpp server, 4 slots
each got one prompt with words only, and the video is 42 minutes of all four thinking and writing at once, sped up to 3 minutes


Wonjin retweeted
OpenAI banned Pewdiepie for fine tuning and de-censoring an open weight model for his agent harness.
What is going on
youtu.be/ODDJXGY_1kQ?is=fe3N…

Wonjin retweeted

🎯 Cloudflare released an open-weight, Jev-compatible decision model.
Clef scores the choices you give it in one forward pass. Which tool should your agent call? That's the right question.
Where should a request go? Does it need human review?
27B Clef + 9B Clef-flash. Apache 2.0. Weights on Hugging Face.
Cloudflare reports leading results on the Jev Decision Index. Their evaluation.
Local setup 👉 Python/PyTorch + custom decision head. No verified llama.cpp support yet.
🔗 Link in ALT

ALT https://huggingface.co/Cloudflare/clef
Wonjin retweeted

MLX-Serve 26.10.1 is out: speed across the board.
Exactly faster. Qwen3.8 27B with its drafter
+66% on an M5 Ultra,
+28% on an M4 Max,
+37% on an M1 Pro.
Qwen Flash Next:
+11% decode on M4 Max,
+51% prefill on M5 Ultra. (up to ~5400 PP!!!!)
Gemma 4, Qwen, LFM2.5, Spark, Bonsai 2 all faster, output byte-identical to 26.9.6 (across 18 models).
New:
* GGUF models run on our own MLX engine, written in Zig and Metal, instead of the llama.cpp fallback. (experimental)
* 🍣 Sushi-format Flash Next packs run directly.
* Qwen-Image 2.1 edits pictures from instructions.
* Drafting is on by default for every model that supports it.
Huge thanks to everyone who filed, tested and fixed this one: @STRML_, @sbusso, @wutang_superfan , lborloz, LXD-8 @alinselea zeeshanhaque21 @Lojza3D, h9q2cyxvgm-ui @kennethrdegraff, @CowboyCoderHQ , codysk, @Beamsters1, @CerebralCoding_, @AjAbsaki , and more.. THANKS ! Please comment if I did not include your name, for visibility, I know people mostly by their GH handle.
Special thanks to @ashxhart and @Spangler3000 for pushing !
Benchmarked and tested across 5 machines: htmlhost.jax.workers.dev/ren…
GH Release Download + Changelog:
github.com/ddalcu/mlx-serve/…
Website: mlxserve.com

Wonjin retweeted

Run Qwen3.8 27B TensorFold on a DGX Spark
Default settings:
- 256k context by default
- Can be extended to 1M with YaRn
- 2.5K KV cache
- 8 concurrent session
Performance:
- 58.3 tok/s on prose, single stream
- 108.5 tok/s on prose, 2 concurrent streams
- 220 tok/s on prose, 8 concurrent streams
That puts single stream 2x faster with TensorFold!
mia-ai.net/models/Qwen3.8-27…

Wonjin retweeted

First test of TandemLLM on someone else's Spark, with the same result I saw: the 27B starts to feel like a cloud model.
That matters more to me than any peak tok/s number.

🚨🚨🚨
Shoutout to @0xBakeer for launching his own inference engine TandemLLM ! ! !
I've tested it in the last few hours and I can say Qwen 3.8 27B on a DGX Spark is much more snappier when run with it.
Also the included inference monitoring dashboard is very informative and I'm actually a bit envy on the lightness of the interface and high refresh rate.
I might have to steal some of his dashboard design ideas to make mine as fast as his 😅
The prefill speed seems to be ~750 t/s (for now) but the decode speed has peaks even over 100 t/s and a general much faster experience than vLLM or SGLang recipes.
The biggest win is the e2e which is much better than what we had until now. The 27B feels for the first time almost like a cloud model.
Absolutely amazing work by 0xBakeer, thank you sir for pushing the local inference progress even further than the big guys managed to do in so much longer time and with so much larger resources.
github.com/0xBakeer/TandemLL…
Wonjin retweeted
My GitHub is amazing value, model configs, weird research, scraped data, useful scripts
Enjoy GitHub.com/0xSero
