

Accelerating AI by Learning Optimal Datatypes
Canada
Joined October 2024
- Tweets40
- Following7
- Followers180
- Likes44



ByteShape is at #EMNLP2026 in Budapest!
Come see our Industry Track poster, "Displacement Is Not Direction", in Poster Session D!
📍 Hall H, HUNGEXPO
📅 Mon, October 26, 11:00–12:30
Can't make it? Find us anytime October 25–29!
📄 arxiv.org/abs/2606.19558
#NLProc #ByteShape

ByteShape is a Startup Sponsor at #PyTorchCon 2026!
Come visit us at Booth #52 for fun interactive demos, conversations about efficient AI, and a special surprise!
📸 Take a photo and bring home a printed keepsake!
📍 San Jose Convention Center
📅 October 20–21
See you there!


ByteShape retweeted

Trying out a handful of Qwen 3.8 27B quants tonight on my 4090 (custom lovelace runtime). Tests included HumanEval+ and a custom suite from my local harness sessions.
@ByteShape came out on top. Well done!🎉
Any other quants I should check out?

ByteShape retweeted

In the past week or so alone, ByteShape’s optimized AI models were downloaded more than one million times.
The pace is clearly accelerating.

ALT ByteShape Is Taking Off banner
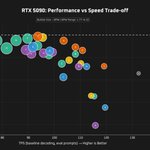
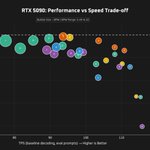
This is performance measured on llama.cpp and specifically on an RTX 5090 using llama-bench. It’s non-MTP performance. We have more benchmarks on more GPUs on our blog post: byteshape.com/blogs/Qwen3.8-…

3/3 Full results: byteshape.com/blogs/Qwen3.8-…
2/3 For Thinking benchmarks, we use medium thinking effort with the recommended sampling parameters.
Bonsai 2 reaches ~91.5% on our composite benchmark and shows a strong quality/throughput trade-off.
The goal is simply to provide a common reference point across Qwen3.8 quants

2/2 I’d start by trying Models 2 and 4 to get a feel for the tradeoff. If 4 still isn’t good enough quality-wise for your workload, go with 5.
If 2 already meets all your expectations, try 1 for the fastest option.
1/2 We haven’t benchmarked these models on Windows, but on cards like the RTX 4090 this model is extremely memory-bound, so the smaller the model, the faster it should generate tokens.
The real question is how much quality you’re willing to trade for speed.
It’s hard to tell without enough information to reproduce it. We didn’t notice this in our tests. You can also follow up on this Reddit post: reddit.com/r/LocalLLaMA/s/C0…. The community there would definitely be able to help troubleshoot it.

We released ShapeLearn-Lite days after Qwen 3.8 27B, and it already delivered some of the best quality/speed trade-offs we tested.
Now full ShapeLearn is even better: 99.63% of BF16’s aggregate benchmark score at just 3.84 bpw.
Models & results: byteshape.com/blogs/Qwen3.8-…

ShapeLearn has, in fact, been sicced 😄
We dropped a ShapeLearn-lite Qwen3.8 yesterday, and it’s looking pretty good.
Give it a spin and tell us what you think:
huggingface.co/byteshape/Qwe…

- GGUF: broadly compatible and easy to run across different hardware
- vLLM-Omni: around 2× faster, using our optimized backend on NVIDIA GPUs
Qwen-Image-2512:
byteshape.com/blogs/Qwen-Ima…
Krea-2-Turbo:
byteshape.com/blogs/Krea-2-T…

We recently released two optimized image-generation models: Qwen-Image-2512 and Krea-2-Turbo.
We pushed both into the ~3 bpw range while preserving their ability to generate high-quality images.
Each model comes in two flavors:
(1/2)

ByteShape retweeted

These @ByteShape models likely don't get enough attention (they don't seem to be loud like many others!). I've been running for a couple weeks, so well tested. Worth trying if you run Qwen3.6. Quite a lot faster for me, on my setup as well.
huggingface.co/byteshape

We released Qwen 3.6 35B A3B GGUF quants in both NTP and MTP.
The benchmark results made one thing clear: size, speed, and quality do not move in a straight line.
GPU-5 was hard to beat. If it fits, try it first.
Blog: byteshape.com/blogs/Qwen3.6-…
