

Local LLMを中心に、AI技術系の投稿とネタツイ Tesla v100 32GB×2枚と共に生きる。 最近はFlash Nextちゃんと遊んでいます アイコンは羊野郎さん@maton_3110
Qwen3.8 27Bから浮気中
Joined August 2019
- Tweets16.4K
- Following1.9K
- Followers7.3K
- Likes48.9K





Ryu retweeted

Kimi K3.1 Proが登場。
最新の3兆パラメータ級オープンウェイトモデル。
🔹100万トークンのコンテキスト/オープンウェイト
🔹 Unreal、Unity、Godotでのゲーム開発を一貫して支援
🔹 BlenderやCADでのパラメトリック3Dモデリングに強み
🔹 金融業務にも強み:OfficeQA Pro v2(64.4)、SpreadsheetBench v2(36.3)で最高水準の性能を達成。DCF/LBOモデリングにも一貫して対応
Kimi K3.1 Proは、Kimi.ai、Kimi Work、Kimi Code、Kimi APIで提供を開始しました。 モデルウェイトは2026年11月4日までに公開予定です。
🔗 API: platform.kimi.ai
🔗 Tech blog: kimi.ai/blog/kimi-k3-1-pro

Ryu retweeted
日本の皆様、お待たせしました。
Kimi K3.1 Proが提供開始。
いつも応援してありがとうございます!
日頃の感謝を込めて、抽選で10名様に
月間Proプラン(39ドル相当)をプレゼント。
リプ+フォロー+リポスト+いいね。
Kimi K3.1 Proを体験してみたい方は、この機会にぜひ。
知る、考える、つくる。
Kimiと。

Kimi K3.1 Proが登場。
最新の3兆パラメータ級オープンウェイトモデル。
🔹100万トークンのコンテキスト/オープンウェイト
🔹 Unreal、Unity、Godotでのゲーム開発を一貫して支援
🔹 BlenderやCADでのパラメトリック3Dモデリングに強み
🔹 金融業務にも強み:OfficeQA Pro v2(64.4)、SpreadsheetBench v2(36.3)で最高水準の性能を達成。DCF/LBOモデリングにも一貫して対応
Kimi K3.1 Proは、Kimi.ai、Kimi Work、Kimi Code、Kimi APIで提供を開始しました。 モデルウェイトは2026年11月4日までに公開予定です。
🔗 API: platform.kimi.ai
🔗 Tech blog: kimi.ai/blog/kimi-k3-1-pro


Ryu retweeted

Hy-SimulMT is now open source! 🚀
Tencent HY’s real-time Chinese ↔ English Simultaneous Interpreting Model.
Key features:
⚡ Low latency (~3s)
🎯 High accuracy
🎙️ Real-time voice cloning
🏆 Outperforms most open-source models and commercial APIs
Download, try, and build with it! 👇:
Hugging Face: huggingface.co/collections/t…
ModelScope: modelscope.cn/collections/Te…
GitHub: github.com/Tencent-Hunyuan/H…


Ryu retweeted

Nanbeige4.3-33B is here with 512K context and strong agentic performance in a 33B dense model.
🤖 modelscope.ai/models/nanbeig…
🏆 SOTA agentic performance at the 30B scale: Nanbeige4.3-33B leads most benchmarks in the team’s comparison with open models including Qwen3.8-27B, Muse-Glimmer-30B, and Gemma4-31B.
💻 Agentic coding: Scores 80.9 on Terminal-Bench 2.1 and 65.5 on DeepSWE, compared with 73.0 and 42.5 for Qwen3.8-27B.
🧰 Professional workflows: Reaches 54.2 on Automation Bench and 44.8 on JobBench, covering tasks across tools, occupations, and industries.
🧠 Flexible reasoning and tool use: Switch between thinking and non-thinking modes, and retain previous reasoning for multi-turn agent workflows.
🔬 A teacher for smaller agents: Nanbeige4.3-33B is the flagship teacher model for the team’s planned distillation into smaller models.
📜 Apache 2.0. Supports Transformers, SGLang, and vLLM.

Ryu retweeted

Maya's KV streaming trick is 5 head
Old limit was long conversations would just fill vram
Their fix was to keep conversation history in RAM and only a recent windows in VRAM
Result = 1M context fits a single 3090
github.com/mw00/project-maya


Ryu retweeted
ギガチャドQwenカピバラくんでワロタ

People are on the hunt for an alternative to Qwen 3.6 35B A3B.
Here's a list of quite fresh models you could test, this is my to do list and it constantly grows, all the models I want to test out which are in that rage, many of them are very recent.
So far Tiel Coder and Ornith 1.5 35B from @ornith_ are the best Qwen 3.6 alternatives I've tried but as you see the list is quite long so there's a chance you find something interesting there.
I will be testing them all in real app building mostly as 4bit or 6bit anyway.
> Flint 40B A2.5B from @Recursive_SI : huggingface.co/RecursiveSI/f…
> Raon-1 mini 30B A4B from @Krafton_AI : huggingface.co/KRAFTON/Raon-…
> Sage-A1.5 35B A3B :huggingface.co/InternScience…
> MiniCPM-V 4.7 35B A3B from @OpenBMB : huggingface.co/openbmb/MiniC…
>LFM2.5 24B A2B from @liquidai : huggingface.co/LiquidAI/LFM2…
> Apodex 1.1 mini 35B A3B from @Apodex_AI : huggingface.co/apodex/Apodex…
> K2 Horizon 36B A4B from @IFM_AI : huggingface.co/IFM/K2-Horizo…
> Xing 4.0 29B A4B from Xing Chen AGI : huggingface.co/XingChen-AGI/…
>Nex N2.5 Mini 35B from @NexEcosystem : huggingface.co/nex-agi/Nex-N…
> Bigbang v1 35B A3B from @EFrontierLabs : huggingface.co/endless-front…

Ryu retweeted

contributorsとしてチマチマやってます
めちゃくちゃイイですこのプラグイン
このせいで僕のこのプロジェクトがいらない子になりました
github.com/AliceSaikawa/dsh-…

Ryu retweeted

めちゃくちゃ使いやすくなって感動してる…
DshのWebUIにスマホで接続してる方は本当におすすめ
github.com/kuraneko1/dsh-mob…
Ryuさん(@_ryu15_ )に深く感謝( ᴗ ᴗ)⁾⁾


Ryu retweeted

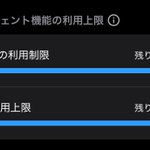
We're sorry for the rate limits and unnecessary quota consumption on the K3.1 Pro subscription plan. These were our issues, and we should have fixed them sooner.
Today, every subscriber on every plan gets a one-time usage reset, restoring 25% of their monthly quota (usage below 25% resets to zero), equal to one week of usage. Your usage bar will reflect this adjustment by end of day PST.
We've also adjusted the plan's parameters and are reducing unnecessary subagent calls and output length, so your quota goes further.
Thank you for your patience while we put this right.


Ryu retweeted
Nanbeige 4.3 (33B Dense)というモデルがリリースされたんだけど、強くね?と思ってベンチマークのデータ集めたら強すぎて横転した
1枚のGPUにギリ収まるこのサイズ感も、どんどん賢くなっていくんやなぁ。ローカルLLMの未来は明るい!!

Ryu retweeted

Nanbeige 4.3 33b uses an old llama architecture, and that makes inference very costly
At 256K tokens (BF16, 1 sequence):
2 (K+V) × 52 layers × 8 KV heads × 128 dims × 262,144 tokens × 2 bytes ≈ 55.83 GB.
Qwen3.8-Flash-Next: ~6.76 GB including indexer/recurrent state (no MTP). Nanbeige uses ~8.3× as much cache memory.
KV cache quantization will be necessary and still this will quickly saturate your memory bandwidth.
Maybe that's the price to pay for this kind of accuracy for such a small model
Ryu retweeted
このモデルを更に強く無検閲化しつつ精度を高めるために協力して取り組んでいます!
CoxianさんはThinkingのループを大規模なFTなしで抑制する革命的な方法を実現してくれました。そのアイディアと、僕が作った倫理観が無いモデルを作った方法を組合せてより良いAblitretedモデルを目指します🚀

Released: DeepSeek-V4.1-1017-Ablitrated-Efficient
(built on @Hikari_07_jp’s testmodel)Layer-selective abliteration + targeted fixes for thinking loops and re-verification.
HF: huggingface.co/pentacoxian-d…
