

co-founder @elementlpower | building new nuclear former submariner opinions my own
Joined August 2026
- Tweets262
- Following202
- Followers213
- Likes93


Pinned Tweet
Nuclear is having a moment. People want new nuclear, but can we build it?
I've been writing the story of how we got here, what we learned, and why we started Elementl.
How We Got Here: the 2020 "melting ice cube" thesis x.com/davidefaherty/status
Nuclear's Missing Business Model: the industry needed projects, not more designs x.com/davidefaherty/status
Then Demand Showed Up: from replacing the fleet to load growth x.com/davidefaherty/status
Testing the Thesis: lots of meetings and lots of noes x.com/davidefaherty/status
The Mental Model of a Utility Executive: why utilities don't build x.com/davidefaherty/status
A Reactor Is Not a Project: lessons from PJM and Oklo x.com/davidefaherty/status
Making Nuclear Investable: development is using dollars to retire risk x.com/davidefaherty/status
Who Actually Builds a Nuclear Power Plant?: designing a reactor isn't building a plant x.com/davidefaherty/status
More coming.
David Faherty retweeted

The Savannah River Site Area Emergency was terminated at 9:45 p.m. Protective actions have been lifted, and site barricades have reopened.
When more specific information is available, it will be provided to you via SRS.GOV and Facebook.com/savannahriversi….
David Faherty retweeted
Anthropic's IPO was filed on October 26, 2026, and I value it's equity at about $1.475 trillion, which will inform my decision on whether to buy or sell its shares. To make your Anthropic choice, though, you should value it yourself, and I will provide a story and input structure to help you. bit.ly/3UTo3Gj
This @DOE_EDF initiative addresses a major barrier to building nuclear: the cost of capital before construction even starts.
Financing long-lead equipment can reduce reliance on expensive development equity, secure manufacturing capacity and lower schedule risk, driving down financing costs and ultimately the cost of power.
A standardized design and a credible project pipeline make that approach possible at scale.

David Faherty retweeted

The Dept of Energy will provide $17.5 billion in loans that will finance the construction of ten AP1000 reactors in the US. Purchases of long-term components (e.g., reactor vessels) may start late this year. Article link in reply.

Thanks so much for this explanation! The world is changing quickly

Many of you don't understand how serious this is, so let me break it down.
In computer science there is a famous kind of puzzle called 3-SAT. You are given a long list of yes-or-no switches and a set of rules about how they must be arranged, and you have to find a combination that satisfies every rule. The obvious way to solve it is to try every combination, but each new switch doubles the number of possibilities, so a puzzle with a few hundred switches would take longer than the age of the universe to brute force.
For decades, the smartest people in the field found clever tricks that made this a little faster, but every trick still hit the same wall: the time required kept exploding as the puzzle grew.
About 25 years ago, two computer scientists, Russell Impagliazzo and Ramamohan Paturi, working with Francis Zane, turned that wall into a formal idea.
They proposed the Exponential Time Hypothesis, which says this explosion is not a failure of human cleverness but a law of nature. No algorithm, however brilliant, will ever solve 3-SAT without the time blowing up exponentially. Nobody could prove it, but almost everyone believed it, and it became one of the foundations of modern computer science.
Researchers used it as a measuring stick. If you could show that solving some other problem quickly would also crack 3-SAT quickly, you had shown that problem was hopelessly hard too. Hundreds of papers, across scheduling, graphs, logic and much more, rest on this one assumption.
Now an internal AI model at OpenAI claims to have broken it. It says it found an algorithm that solves these puzzles meaningfully faster than the hypothesis allows, and it has checked the proof in a computer verification system called Lean.
And here is the remarkable part: the very people who proposed the hypothesis, Impagliazzo and Paturi, along with MIT's Ryan Williams, are now leading the public review of whether a machine has disproved their own idea.
So what happens next? If the disproof holds, a large part of theoretical computer science has to be revisited.
Every result that said "this problem cannot be solved faster, assuming ETH" loses its foundation, and researchers will have to work out which of those walls were real and which were simply where we stopped looking. It does not mean everything becomes easy. The new algorithm is still slow in absolute terms and this is not the famous P versus NP problem being solved.
But it means our map of what is possible was wrong in a place we were very confident about, and it was an AI that redrew it. If the disproof fails, the hypothesis survives and the field breathes out, but we will still have watched an AI produce serious, checkable work on one of the deepest questions in the discipline, closely enough that the founders of the idea had to take it seriously. Either way, something has shifted.
Building new nuclear in America is a project-delivery problem, not a technology problem. Today Elementl Power announced a preliminary agreement for a development partnership of up to $750 million built to solve it.
The partnership is with a consortium led by DS Investment Partners (DSIP), with Samsung C&T participating as a potential strategic investor. Once finalized, it would be the first private capital facility dedicated exclusively to developing multiple utility-scale U.S. nuclear projects. It would fund permitting, interconnection and long-lead procurement for up to three Elementl projects, including our 1.5 GW project in Ohio, and carry them toward final investment decision.
Development capital only works when technology risk is largely off the table. The @gvhnuclear BWRX-300 builds on decades of boiling water reactor operating experience, runs on commercially available fuel, and is already under construction at Darlington. That lets this capital do one job: make projects ready to finance and build.
Samsung C&T would bring nuclear construction experience and deep access to Korea’s supply chain and engineering bench. American trades will build these plants in Ohio and across our project communities: construction jobs now, operating careers for decades.
That’s what we mean by America’s Nuclear Prime: one repeatable model that brings development, capital and delivery together for successive waves of American nuclear construction.
There’s work ahead to finalize the partnership and deliver these plants. Grateful to DSIP and Samsung C&T, and proud of our team.
bloomberg.com/news/articles/…

David Faherty retweeted

@elonmusk may be right that we'll see unfinished data centers. But not all developers operate the same way.
$WULF follows a disciplined approach:
1. Identify sites with demonstrated customer interest.
2. Secure power from investment grade utilities.
3. Lock down specs, construction costs and schedules through GMP EPC contracts.
4. Secure long-term customer commitments backed by investment grade credit.
5. Arrange financing before committing to major construction.
We may move dirt early, but we don't build on spec.
I suspect we'll see projects stall because of inadequate capital, weak counterparties, execution misses, or regulatory hurdles. For experienced infrastructure developers with strong balance sheets, that creates opportunity.
What others call stranded assets, we may call a development pipeline. @PSInvestor @GavinSBaker

David Faherty retweeted

If you’ve been wondering what’s been happening in nuclear at EDF, I appreciated this conversation with Jason Bordoff
In talking through restarts, uprates, and new builds, we explore the special role of EDF, my admiration for the NRC, implications of direct pay ITCs, and more!

Love this line: “A GPU….is a financing instrument that happens to do matrix multiplication.”
Same chip, different balance sheet, different cost.

I've been critical in the past of AI compute indexes and the willingness to price compute based on the spot rental price, but now that the AI reset is sinking into the repricing of AI buildout debt its time to realize that the cost of capital is what determines the price of compute.
The most important number in GPU pricing right now isn't $/GPU-hour. It's the gap between what a hyperscaler pays to borrow (~90bp over Treasuries) and what a neocloud pays (~1,100bp).
The cost of compute is now set by the cost of capital, and the spot rental rate no longer tells you much.
The price of an H100 isn't one number. The same chip in the same rack costs a different amount depending on whose balance sheet it sits on. A ~1,000bp funding gap is a structural cost advantage that no amount of operating skill closes.
For example, take one GPU-hour apart. Most of it isn't power or space. It's paying back the chip, the interest on the loan that bought it, and the return the equity expects. A $40–55k all-in GPU, 75% debt-funded, at ~7,000 utilized hours a year is a financing instrument that happens to do matrix multiplication.
As the +500bp on neocloud debt (10%→15%) adds $0.20–0.30 to the break-even cost of every GPU-hour, which is then added on to the rental price.
That's 8–10% of the H100 index, from a credit spread alone, driven almost entirely by the cost of capital.
That means that the compute spot index is a derivative of the AI infra debt credit curve and the squeeze on neocloud margins.
David Faherty retweeted

I've been critical in the past of AI compute indexes and the willingness to price compute based on the spot rental price, but now that the AI reset is sinking into the repricing of AI buildout debt its time to realize that the cost of capital is what determines the price of compute.
The most important number in GPU pricing right now isn't $/GPU-hour. It's the gap between what a hyperscaler pays to borrow (~90bp over Treasuries) and what a neocloud pays (~1,100bp).
The cost of compute is now set by the cost of capital, and the spot rental rate no longer tells you much.
The price of an H100 isn't one number. The same chip in the same rack costs a different amount depending on whose balance sheet it sits on. A ~1,000bp funding gap is a structural cost advantage that no amount of operating skill closes.
For example, take one GPU-hour apart. Most of it isn't power or space. It's paying back the chip, the interest on the loan that bought it, and the return the equity expects. A $40–55k all-in GPU, 75% debt-funded, at ~7,000 utilized hours a year is a financing instrument that happens to do matrix multiplication.
As the +500bp on neocloud debt (10%→15%) adds $0.20–0.30 to the break-even cost of every GPU-hour, which is then added on to the rental price.
That's 8–10% of the H100 index, from a credit spread alone, driven almost entirely by the cost of capital.
That means that the compute spot index is a derivative of the AI infra debt credit curve and the squeeze on neocloud margins.
Are we shrinking reactors to solve a construction problem robots are getting better at solving?
If your microreactor thesis needs big-reactor construction to stay broken, you're betting against robots.
Venture Blind Spots in Nuclear, Part 1

David Faherty retweeted

Think the neocloud bond yields are pretty damn attractive.
The equity risk boils down to: neocloud signs 15-20 year leases and PPAs and buys GPU (ie cost side is fixed). Then it signs customers for 3-5 years at a time. Right now it’s great because spot prices are healthy. For example I’m sure OpenAI is very happy with the 300B Oracle contract because it locked in GPU hours at a price lower than spot. But when contracts come up for renewal and spot prices collapse, the margins are each site collapses.
I’ve done some back of envelope math and it looks like the senior down to unsecured tranches of these bonds look pretty safe. Anyone else get to a diff answer?


Thank you for breaking this down, @businessbarista. Now I get why everyone’s talking about @nickcammarata’s essay. If AI turns out to be far more understandable than we assumed, that’s a very big deal!

Everyone is talking about how profound this essay is rn.
For the non-technical person (like myself), a 65-minute read about the inner-workings of neural networks feels very unapproachable.
But people are right, this essay is profound. And it's important to understand its essence even if you don't grok the particulars.
So let me do my best to break it down as I understand it...
Let's start with mechanistic interpretability.
That's what this essay is about & what the field has been obsessed with for a long time.
Mechanistic interpretability is a clunky phrase, but all it means is the process of understanding how an AI model works on the inside:
1) which parts of the model do what
2) how they work together to produce an answer
The next obvious question is: why do we even care about understanding how an AI model's internals work?
There are several reasons, and they all boil down to one word: trust.
reason 1: we've been building ai we don't understand. unlike every other high-stakes technology (computers, internet, planes, medicine), we know if a model works, but we don't know how it works.
reason 2: predicting performance is unpredictable. the way ai is judged today is through tests. problem is, tests don't cover enough ground. a model can perform well in testing, but not deployment. you can't run every test possible. and a model can give you the right answer for the wrong reason.
reason 3: scanning for deception is important. as models get better, there's concern that models will output one thing, while "thinking" something else. if you can only understand outputs, a model can hide its true intentions from you.
reason 4: it allows for precision when improving the model. once you know which internal parts cause what outputs, you can isolate fixes without having to retrain the entire model and praying it works.
reason 5: understanding how the model works is mission critical in high-risk industries. simply saying the model did the right thing "just because" to stakeholders in healthcare, financial services, and government won't fly especially as regulation matures around this technology.
reason 6: humans can learn from how the models "think". models sometimes learn patterns that humans haven't. if we understand their thought processes we can leverage those for humanity's own novel insights.
So, that's why mechanistic interpretability is important.
Next, it's important to understand why there's been so much focus & concern around this area of AI research for a while now.
Prior to this piece by @nickcammarata, the consensus view was...
Progress has been made in the field over the years (from studying toy models to massive production models in short order), but even still, current techniques are slow, expensive, and only cover small parts of understanding a model.
And here's the rough story researchers have generally agreed on re: why the practice of interpretability has remained limited:
1) AI models are built from millions of “neurons,” small units that each light up in response to a given input.
2) Ideally every neuron has one clear job, that way you can map out the model as a diagram of neurons and their corresponding meaning cleanly. Example: there's a "dog ear detector" neuron and it fires on floppy dog ears, from any breed, angle, or photo, and on nothing else.
3) There's a problem: early researchers found that neurons had several unrelated jobs (i.e. they fired on unrelated inputs). The most famous example was of a neuron that fired on both cat faces and fronts of cars.
4) The leading explanation for "messy" neurons was called superposition. The idea was that when a model runs out of room (i.e. more concepts it wants to track than it has neurons to track them with), it crams unrelated concepts into the same neuron because they rarely show up together.
5) If this theory of superposition is true, studying neurons would be a fools errand, because you'd have to use a second AI model (called a sparse autoencoder) to try and untangle the first model, which would be expensive & potentially offer an incorrect understanding of the original model.
Which left mechanistic interpretability in this weird spot. As @nickcammarata points out, it is arguably the most important scientific problem to solve as it helps us understand the most powerful technology in human history, but vibes around cracking the code have been lackluster.
In his new essay, Nick, who has pioneered much of the recent work being done in interpretability, posits that the field has largely thought about this problem incorrectly & he explains why.
Which, if he's right, is hugely positive for the world.
Here's his argument...
He believes that neural networks are in fact largely readable, and the "tangled mess" narrative is oversold as a fundamental property, when it's really solvable problems.
He breaks this belief down into four steps:
"1) Networks use one learning principle, not two (if not everywhere, then nearly enough that it doesn’t matter for study), so there’s no blocker to beginning ordinary science on them."
Translation: Neural networks group things by shared patterns (generalization). They don’t switch to cramming unrelated things together when space runs out (superposition) as mentioned above.
"2) With modern models and tools, that science goes much better than most people expect."
Translation: you can study neural nets just as you study anything with science. Assume the neurons are mostly readable as they are. Study the real model directly. And test your explanations with experiments.
"3) Understanding compounds, so it gets easier as the map fills in. At minimum, then, a network’s own mechanisms should be part of the toolkit."
Translation: studying models gets easier as technology and tooling gets better + as you start filling in your understanding of the model it becomes easier to complete the rest. Think of it like a crossword. Each neuron you explain becomes a reference point for checking the ones around it. Early on, a guess about a neuron has nothing to be checked against. Later, it has to fit with everything connected to it, so wrong guesses get caught and right ones get confirmed quickly
"4) Highly speculative: this might be most of what we need, and interpretability might be far more tractable, possibly in the near term, than we’ve assumed."
Translation: if steps 1-3 hold and scale, direct investigation might take us most of the way to understand an AI model & possibly soon. The reasoning is that models have finite number of neurons, most are readable and AI agents can audit them at scale, understanding compounds (crossword effect), so mapping a model is a large, but finite engineering problem.
He goes on to share evidence for his changing worldview as well as steelman the weaker parts of his argument.
First, evidence. Cammarata provides 8 supporting cases.
1) The case for superposition relied heavily on two examples from vision models and they were misread
- The cat/car neuron turned out to detect pointed V shapes. It was also activated when detecting flames, fox snouts, and other pointy things and went negative when round shapes were presented.
- The car-detecting neuron that appeared to be "stashed" inside dog neurons were found to not be dog neurons but instead pose neurons: which detected the orientation of an object. Cars and dogs can both be in a head-on pose which would activate the neuron.
2) InceptionV1 an image-recognition model from 2014 was the first model researchers studied closely. It's early layers were easy to read (neurons for edges, curves, colors), but it's final layer (where the model makes abstract judgements), looked like nonsense. Almost no neurons could be described (0-5%) understandable. This became industry evidence for the "Neural nets are hopelessly tangled" view.
Nick argues that this model had very explainable problems (a bad camera & a poorly built model), and everyone through the baby out with the bath water.
3) Superposition theory says that when a model runs out of neurons, it starts cramming unrelated things together. So Nick deliberately took neurons away (480 --> 10) to see if that happens. It did not, the model just started using broader categories. Think of it as a finance org going from five finance specialists to one person handling all of finance.
4) Recursive generalization explains the leftover mess. The leftover mess is that some neurons still look messy even in good models. But as Cammarata watched neurons form during model training, he found that this "mess" builds up through a chain of small, coherent jumps the neurons make as the model is trained. Think of a tree. A trunk splits into branches, which split into smaller branches, which split again. If you only saw three leaves from far-apart twigs, they might seem unrelated. Follow the branches back and they all connect to the same trunk.
5) If neurons were scrambled (via superpositioning), an untangling tool (sparse autoencoder mentioned earlier), should have uncovered many hidden concepts the neurons don't show. Instead, about 88% of what it found was just copies of existing neurons. Meaning the model had already organized itself into clean units, so the untangling step just rediscovered what was there.
6) Superposition believers think that rare concepts might be secretly stashed in hidden combinations of neurons where no one would notice them. Cammarata test this theory by checking all the hiding spots. He found that the model doesn't have a hidden layer of secret machinery. Even when it handles, rare, weird or random things it uses the same known neurons it uses for everything else.
7) People worry that image models may be clean to interpret but not language models. This comes from two efforts in 2023 to read language neurons where Anthropic found the average neuron to be a 0 (on a 0-14 scale of how understandable it was) and OpenAI found only 1.7% of neurons understandable. But after Nick's audits of 1,000 neurons within Qwen3-32B, he found 90% have one main job, 7% have two related jobs, and 2-4% are random mixtures. Several changes caused greater neuron understandability: bigger, better models, much better AI research assistants, grading for correctness, knowing what to look for, better data to test on, and the crossword effect.
8) His response to "If neurons are this readable, why did so many smart researchers including himself, believe the opposite for years?" An analogy for his explanation is roughly doctors studying x-rays with a blurry, miscalibrated machine, the only have small low-quality scans, they've never been taught what certain healthy structures look like, and there's a popular theory that the organ is naturally deformed.
Finally, the weaker parts of his argument he calls out.
1) Language model evidence is thin. Most of the detailed, controlled experiments are on image models. For language models, he has audits and case studies, and the detailed technical paper isn’t out yet.
2) There's subjectivity in the headline numbers around understanding the job of each neuron. “90% have one job” depends on what counts as one job, how far into the faint signals you look, and how related two things must be to count as the same.
3) Faint signals don’t have a trusted test yet. That’s exactly where superposition defenders would now say the hidden concepts are.
Recap: AI models may be much less of a black box than we thought. For years, researchers focused on mechanistic interpretability believed the inner workings of neural networks were fundamentally scrambled, so trying to study them directly was hopeless. This essay argues that belief was a mistake caused by weak tools and older AI designs.
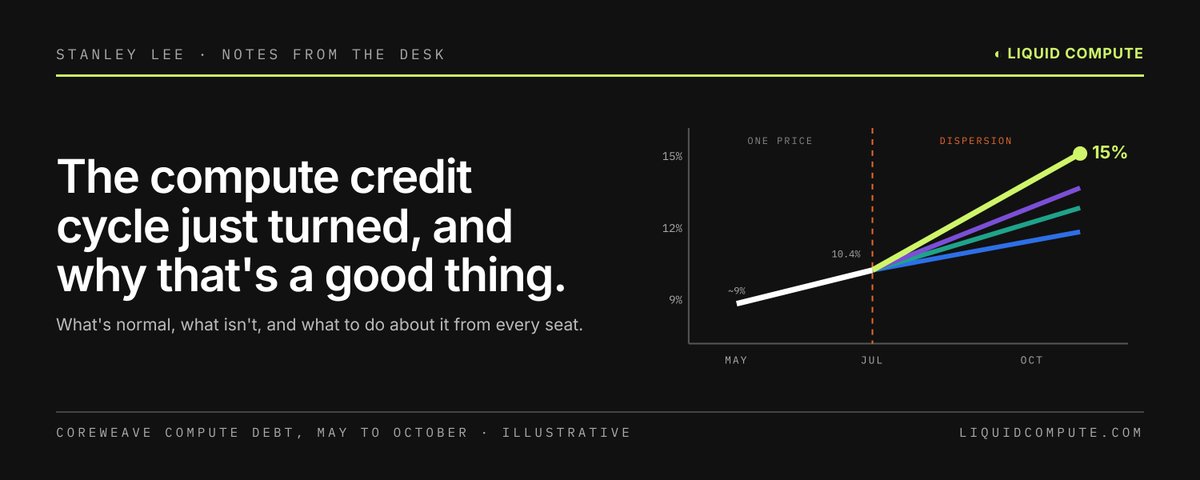
Fascinating take on $CRWV, AI credit, valuations, and historical comparisons by @stanleylee21 Worth reading for anyone following nuclear’s exposure to the AI investment cycle.
When the headlines make it feel like the entire AI capex buildout is about to unravel, this provides useful context for understanding what may instead be a normal, and necessary, process of markets repricing risk.
That process can be painful. But distinguishing among borrowers, business models, and financing structures is part of how capital markets redirect money toward stronger investments.
That capacity to adjust is a strength of American capital markets.
A reset in expectations doesn’t have to mean the end of the buildout. It can put the next phase on firmer foundations, and ultimately make the market more durable.

Following the NRC’s AP1000 design certification announcement, it’s worth remembering that DOE put another critical piece of the puzzle in place earlier this year: financing for long-lead nuclear equipment.
The two developments reinforce each other. Standardization makes projects more repeatable. The right financing helps turn that repeatability into an order book.
Nuclear projects require substantial spending before a final investment decision on engineering, licensing, site development and equipment that can take years to manufacture. Much of that spending relies on development equity, the most expensive capital in the project.
That is an expensive way to finance equipment years before a plant earns its first dollar.
DOE’s $17.5 billion conditional commitment under the American Nuclear Supply Chain Loans initiative directly addresses the long-lead procurement piece of that problem for the next wave of AP1000s.
Debt financing for eligible equipment purchases can reduce reliance on expensive equity, secure manufacturing capacity earlier and lower the financing burden carried into construction.
As other reactor technologies mature, similar facilities should develop through DOE, private lenders or both.
Standardized designs are essential to that model. As a credible pipeline develops around the same design, common components become more transferable between projects. If one project slips, its equipment can potentially serve another.
That creates a path toward asset-based financing: lenders can underwrite equipment with multiple potential destinations, reducing dependence on the fate of a single project.
We still need real projects, capable developers and constructors, operators, and financeable offtake. A pipeline of announcements alone will not support this model.
But the connection matters: standardized designs, repeat orders and better financing can reinforce one another to bring down the cost of deploying nuclear.
DOE deserves credit for putting this piece in place. This is real leadership and financial innovation aimed at a practical barrier to getting plants built.
energy.gov/articles/departme…
